Latest edition
AI for Formal Math · Issue 8
Geometric Analysis Enters Lean: The Dual Milestone of Hamilton's Theorem and Verification Boundaries
The main theme of this issue is "formalization crosses from algebra, number theory, and combinatorics into geometric analysis, while the verification boundary i…
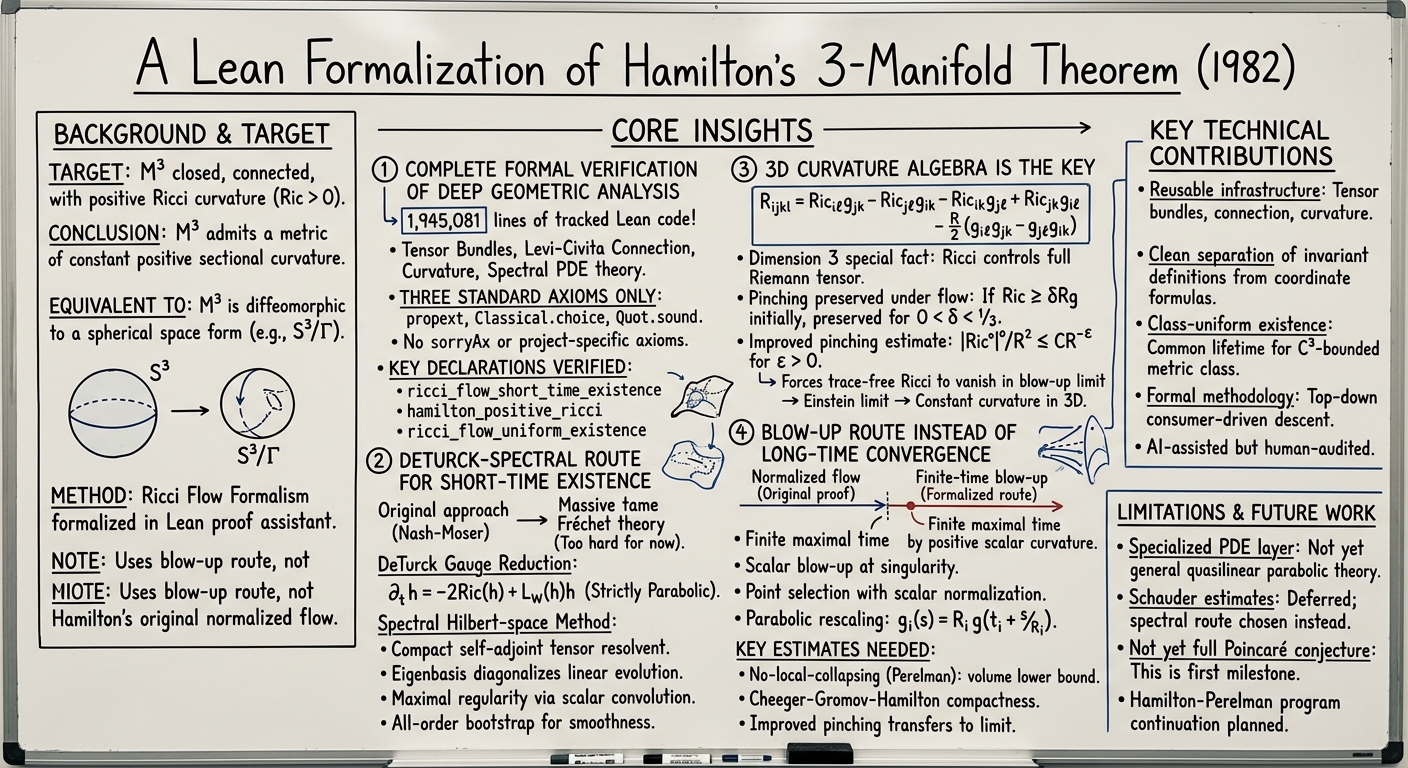 A Lean Formalization of Hamilton's Three-Manifold Theorem (Chow, Liao, Qin)Completes for the first time in Lean 4 the full formalization of Hamilton's 1982 theorem (three-dimensional manifolds with positive Ricci curvature are spherical space forms), with the artifact comprising approximately 1.94 million lines of Lean, including short-time existence of Ricci flow (DeTurck spectral route), Riemannian tensor calculus, scalar and tensor maximum principles, three-dimensional curvature algebra, pinching preservation and improved pinching estimates, and concluding with an alternative blow-up route rather than the original normalized flow proof; the axiom audit contains only standard axioms. Compared to FormalFlow's MIP*=RE in Issue 7, the increment lies in advancing formalization to a core theorem of geometric analysis and establishing reusable geometric analysis infrastructure; the "consumer-driven top-down descent" methodology separates mathematical direction from proof execution and is worth careful reading for anyone doing research-level agentic formalization.
- GenLimitLib: A Formal Library for Language Generation in the Limit and AI-Assisted Mathematical ResearchOrganizes for the first time a formalization library around a single research literature (language generation in the limit): covering 30 papers, 405 statements, and 124,000 lines of Lean, extracting shared definitions and reusable proof components across papers, and thereby repairing proof gaps in published theorems, improving impossibility results, and solving a special case of an open problem. Compared to Lean Pool in Issue 7 (merging independent projects) and MathAtlas in Issue 2 (automated formalization benchmark), the increment lies in treating the library as a "literature-aligned research tool" rather than a domain foundation or benchmark; experiments show that library access improves kernel-verified proof success rates from 48% to 79%, with direct value for designing agentic proof search.
- LeanPolish: Verified Supervision for Lean Proof CompressionA symbolic Lean 4 proof compression pipeline, releasing 33,402 kernel-verified local edits and 65,596 associated failed attempts, and systematically exposing selection effects in search-generated supervision (first-success ordering shortcuts, deletion triviality). Compared to proof optimization systems such as ImProver and ProofOptimizer, the increment lies in explicitly separating proposal/policy/verification and using a controlled evaluation protocol with full candidate pools, frozen baselines, and symbolic fixed points to distinguish "learning to imitate search strategies" from "improving on top of search"—a long-neglected blind spot in proof compression and learning from verification search data.
Pretraining Data · Issue 8
Wild AI Text Becomes an Independent Data Axis
The clearest signal this issue is that "wild AI text" has been established as an independent data axis. How Much Is an AI Token Worth for the first time separat…
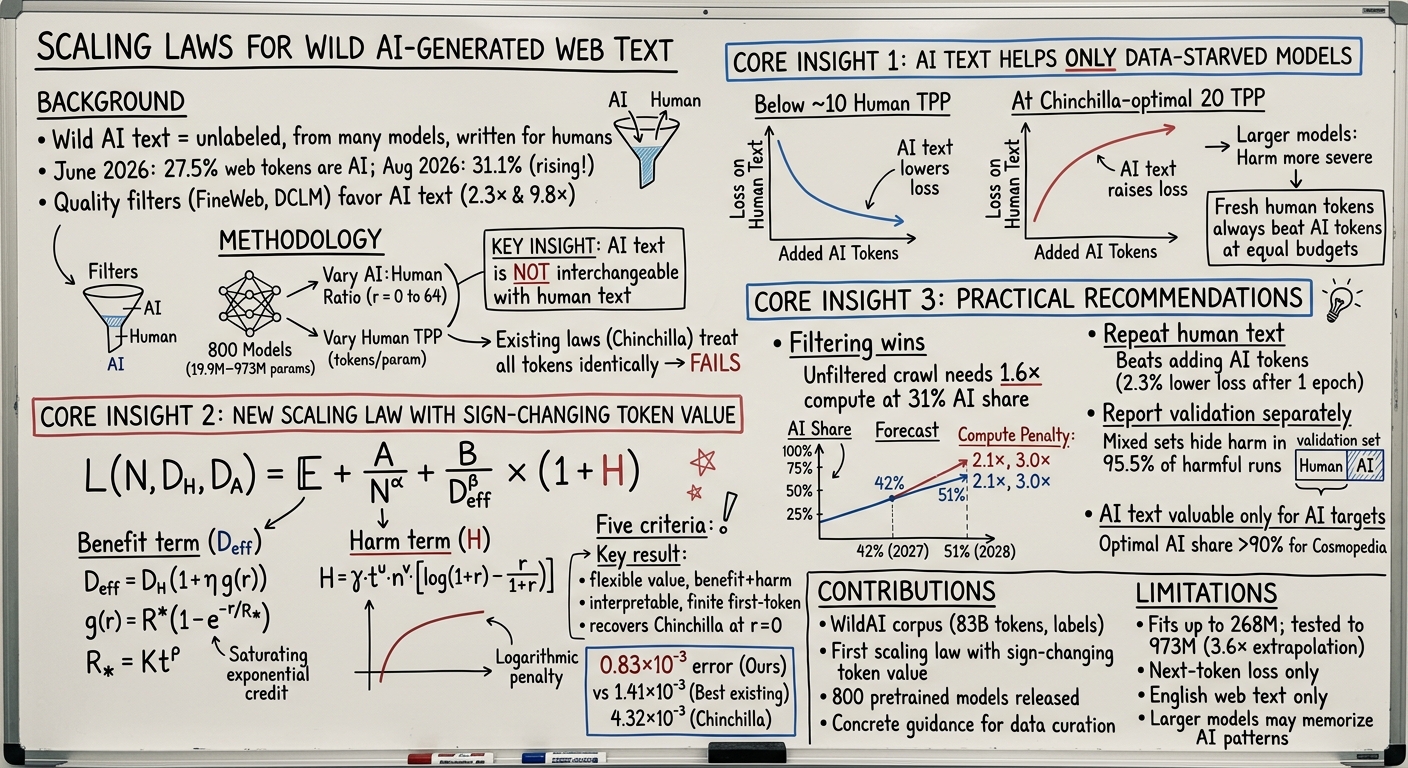 How Much Is an AI Token Worth? Scaling Laws for Wild AI-Generated Web TextFor the first time, "wild AI text" is separated from synthetic data and model collapse settings, treated as a naturally occurring, unlabeled independent data source in pretraining corpora, with scaling laws that can flip the sign of AI token value: separating saturating benefits from logarithmic harms, and degrading to Chinchilla when no AI text is present. Controlled ablations across 800 models (19.9M–973M) show AI tokens only benefit data-hungry models; at the Chinchilla-optimal 20 TPP, the benefit vanishes and turns into harm, while existing repetition/mixing laws fail to predict this behavior. Relative to Issue 1's *Internal Data Repetition* and Issue 3's *Scaling Laws for Mixture Pretraining*, the increment is treating AI text as an independent data source and providing actionable prescriptions (filter AI text, prioritize repeating human text over expanding AI corpora, report human/AI validation losses separately). Publicly releases the Wild AI corpus (83B tokens), 800 models, and code. Limitations: max scale 973M, base loss as criterion.
- ReScraper: Unified Scraping and Cleaning of Web Data for Effective LLM PretrainingCompresses the entire "HTML scraping + rule-based cleaning" pipeline into a single 0.6B model, using four operation types (extract/keep/edit/delete/rewrite) to unify the conversion from raw HTML to pretraining text, and demonstrates that an end-to-end unified model outperforms any "scraper+cleaner" cascade (including the multi-agent DataOrchestra). Controlled ablations at 400M/1.4B/2.8B scales and 22 DCLM Core tasks show each operation contributes gains individually, and at 2.8B scale, repeating 7.5 times still beats the baseline—quality gains can offset repetition costs, key evidence for data-constrained allocation decisions. Relative to Issue 6's WeVisDoc and Issue 1's EDGAR, the increment is jointly optimizing "extraction" and "cleaning" within a single model. Publicly releases data/models/code. Limitation: criterion remains base benchmark.
- Everything in Moderation: Per-Domain Coverage Optima and Alignment-Resistant Domain Gaps in Multi-Domain Mid-TrainingFirst systematic test of the irreversibility of per-domain coverage in mid-training on subsequent SFT/RL: at 8B real scale, with 30 mixing ratios, 5 seeds, and a full SFT+RL pipeline, compensatory SFT improves 116/120 cells (mean +4.32pp) but cannot close any inter-domain gap (0/240 pairs closed at the 5pp threshold); permutation tests show gains are systematically placed to preserve gaps. Also provides per-domain internal optimal bands (10–40%) and saddle point evidence. Relative to Issue 6's *Stress-testing Alignment Midtraining* on conflicting data priors, the increment is explicitly studying whether "coverage gaps can be repaired by post-training." For allocation decision-makers, "compensatory SFT cannot close mid-training gaps" is a strong design constraint. Limitations: single logical reasoning setting, short RL leg.
MoE & Sparse Experts · Issue 8
Load Balancing Enters the Era of Cybernetics and Precision, Evidence Standards for Routing Drift Are Re-examined
The main theme of this issue is that "load balancing is moving from heuristic approaches to cybernetics and precision," while the evidence standards for routing…
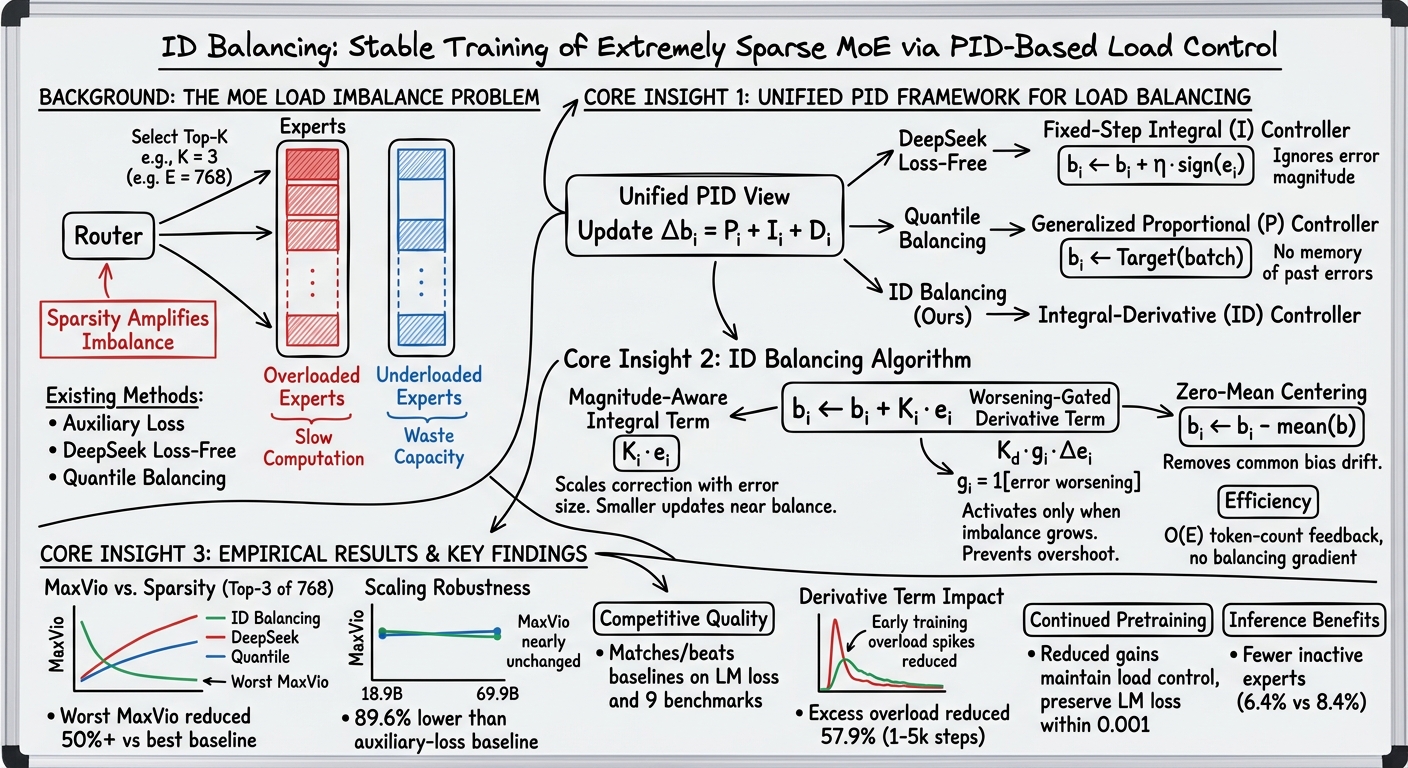 ID Balancing: Stable Training of Extremely Sparse MoE via PID-Based Load ControlMust-read. For the first time unifies auxiliary-loss-free load balancing into a PID control framework: DeepSeek's loss-free is fixed-step integral control, Issue 1's Kimi K3 Quantile Balancing is generalized proportional control. Based on this, the paper proposes ID Balancing with magnitude-aware integral term and deterioration-gated derivative term, validating stability advantages on Top-3/5/10-of-768 extreme sparsity and 69.9B scale, reporting full routing statistics and dense baselines. Compared to Issue 1's Kimi K3, this paper provides a cybernetic unified perspective and provable stability increments.
- Exact Quantile Balancing and Load-Error Injection for Mixture-of-ExpertsMust-read. For the first time advances the global quantiles of Quantile Balancing from rank averaging/histogram approximation to exact computation: two-pass BF16 radix selection recovers global batch empirical quantiles, with communication cost independent of token count and invariant to data partitioning; also proposes Load-Error Injection, using the constant diagonal Jacobian of unnormalized router scores as an STE proxy to inject local load errors, avoiding GShard's cross-expert coupling. Compared to Issue 1's Kimi K3 histogram approximation and Issue 5's Router Prior Bias soft anchoring, this paper provides provable increments in global quantile exactness and reports global and local MaxVio with dense baselines on 7.5B/500B tokens.
- T1: Terminal Agent Reinforcement Learning for Long-Horizon TasksMust-read. For the first time decomposes training-inference consistency into two orthogonal axes—token fidelity (TITO) and routing fidelity (R3)—in agentic RL at 122B scale MoE: TITO uses token-in/token-out concatenation to ensure per-token alignment, R3 records and replays actual expert selections per layer during rollout (not just logits). Compared to Issue 1's PR² predictive replay, this paper directly records actual sampled routing, reducing the log-prob gap from 0.021 to 0.013 on long-horizon tasks with 300+ tool calls, marking the first validation of routing replay at frontier scale and in agentic scenarios.
Efficient Sequence Modeling · Issue 8
What Does the Recurrent State Remember: A Memory Anatomy of Linear Attention
The strongest signal this issue is a set of mechanistic works simultaneously asking the same question: what exactly does the linear/recurrent state remember, an…
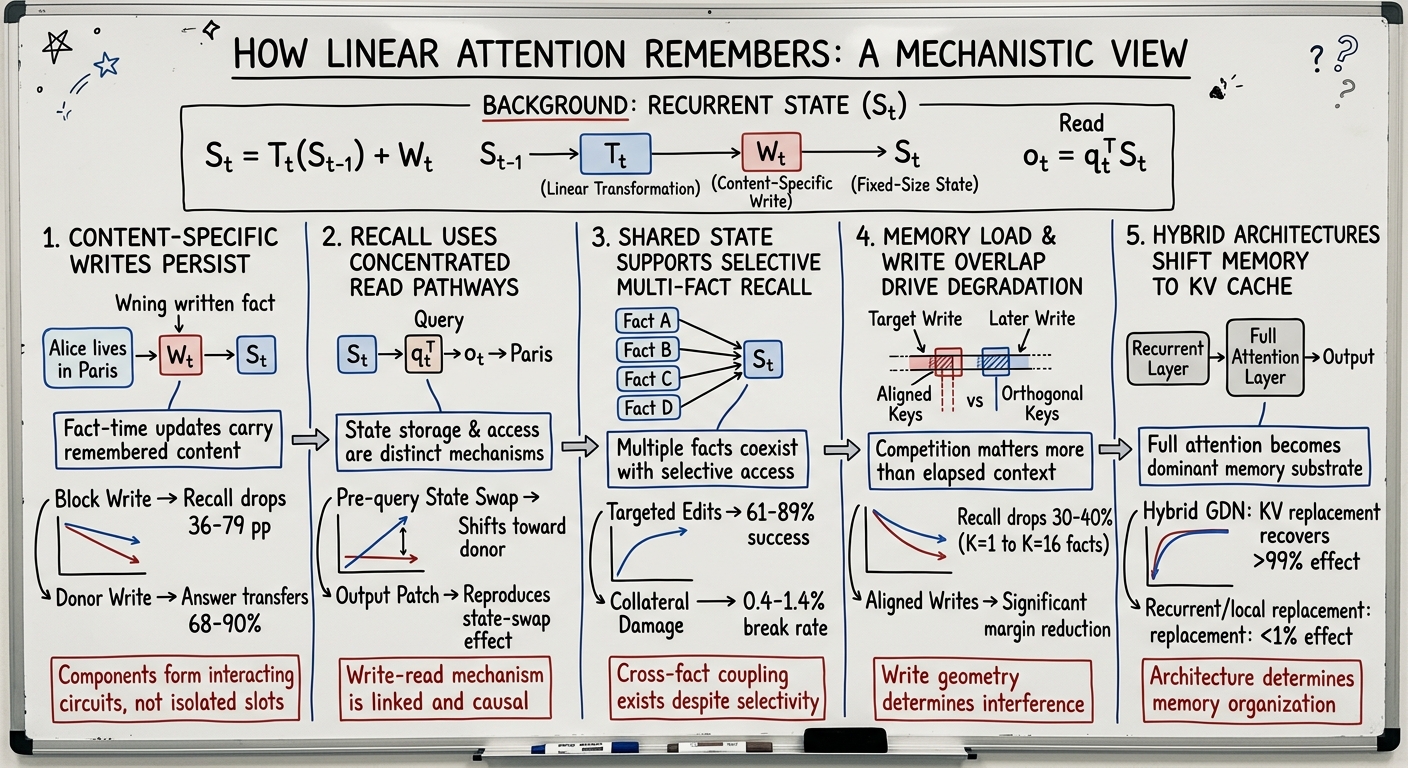 How Linear Attention RemembersUses three types of causal interventions—donor-state swap, write blocking, and output patch—on pretrained GLA/GDN to separate the write, retention, and read phases of recurrent memory, and quantitatively proves that in hybrid architectures, the runtime memory directly supporting recall is almost entirely transferred to the full-attention KV state (KV recovery >99% vs. recurrent <1%). Relative to Issue 5's 'What Attention Recalls' channel-level intervention, the increment is pushing interventions to the single-head write/read lifecycle and providing quantitative evidence of memory substrate transfer—a must-read for anyone doing hybrid layer ratio design.
- Anatomy of Associative Recall in Fixed-State Recurrences: A Matched-State Decomposition, an Interference Wall, and a Curriculum That Breaks ItFirst single-knob decomposition of associative memory in linear attention/SSM under a fixed state budget: short convolution is the dominant lever (+0.47/+0.44), the advantage of rank-1 transfer shrinks to +0.034 with convolution, and state-matched Mamba-2 can match rank-1 units, thereby refuting architectural category claims. More critically, it finds that the interference wall (haystack retrieval at random at the shortest length) is a training coverage gap rather than a capacity issue, and a distance curriculum can improve the unmodified architecture from 0.021 to 1.000. Relative to Issue 5's 'What Attention Recalls' channel-level separation, the increment is providing factor decomposition under fixed state and causal evidence from the training side.
- How Local Mixing Encodes Relative Position in Global NoPE AttentionProvides a mechanistic explanation of how hybrid architectures (SWA + global NoPE) implicitly encode relative position: local mixing induces a recency bias in the residual stream that is preserved across sequence lengths (contrary to the length dilution of global NoPE), is selected by global NoPE attention logits, and strengthens with depth. The key design insight is that the smaller the window, the stronger the recency bias and the lower the validation loss—providing a testable mechanistic basis for window hyperparameter selection, and the mechanism holds on 4096+ tokens.
Scaling Laws & Training Methods · Issue 8
Warmup Duration Enters Scaling Laws: Hyperparameters Shift from Fixed Heuristics to Predictable Axes
The most prominent progress this issue is the re-integration of hyperparameters previously treated as fixed heuristics into the scaling law framework. Balancing…
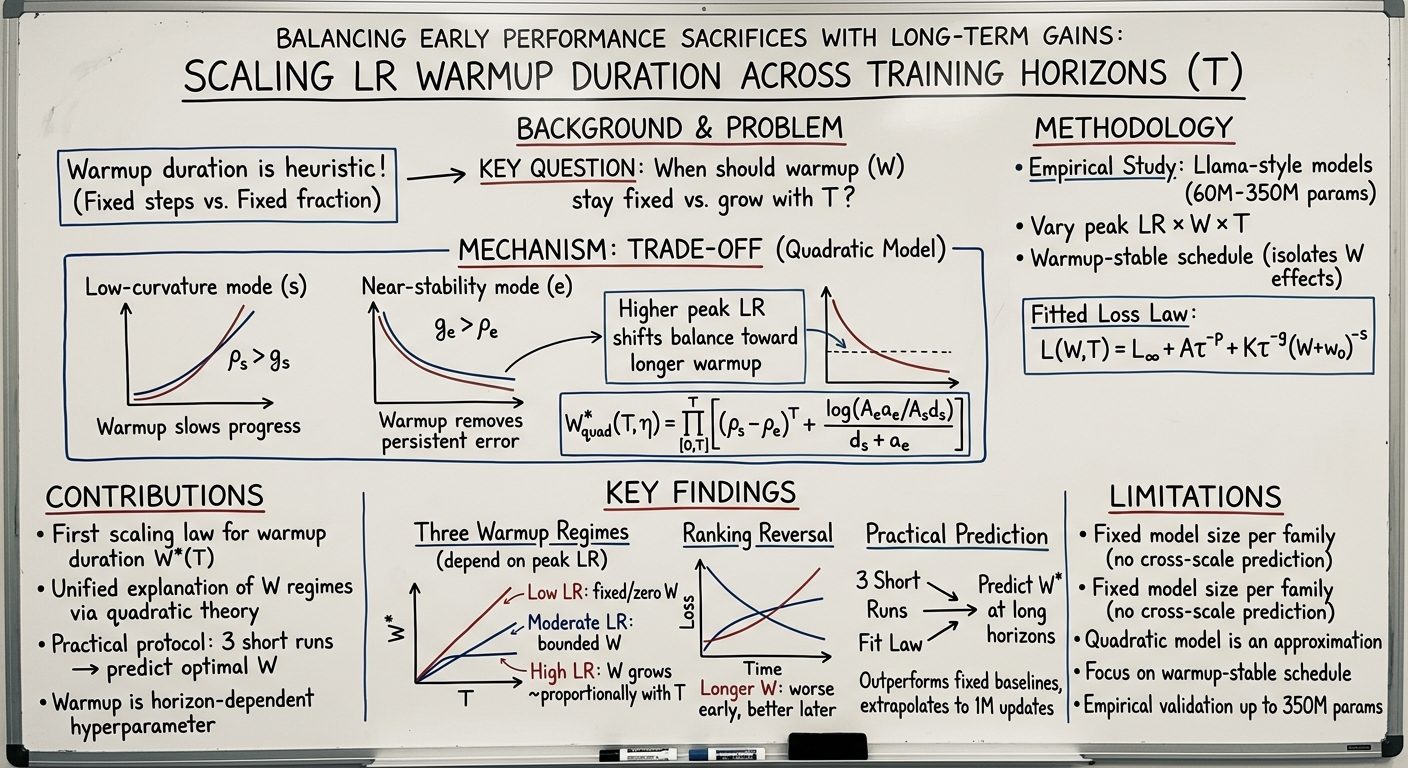 Balancing Early Performance Sacrifices with Long-Term Gains: Scaling Learning-Rate Warmup Duration Across Training HorizonsFirst to elevate the learning rate warmup duration from a fixed heuristic to a hyperparameter that scales with training level, proposing a compact loss law involving W and T and proving that the optimal warmup duration grows as a power law with T, with the growth exponent determined by the peak learning rate. Validated at 60M/100M/350M scales and providing a protocol for extrapolation from three short runs, directly addressing the extrapolation reliability of hyperparameter scaling laws.
- Cost-free Spectral Estimation for Adaptive Newton--Schulz in Matrix OptimizersFirst to extract spectral moments at zero cost from the intermediate Gram matrices of Newton–Schulz iterations, using maximum entropy moment fitting to recover the empirical singular value distribution and adaptively selecting polar decomposition routines for each matrix. Compared to the static spectral scaling laws of Spectral Scaling Laws of Muon in Issue 3 and the offline measurements of Spectral Allocation in Issue 4, it turns spectral information into an online, per-matrix, training-adaptive mechanism, validated at 160M–1B scales.
- On Trajectory-Aware Training for Masked Diffusion Language ModelsUnifies trajectory-aware training for masked diffusion (progressive unmasking + carry + BPTT) into the PUMBA framework, systematically revealing local overfitting under small u, proving that continuous carry outperforms discrete gradient estimators and that longer BPTT windows are better. Matches or surpasses longer SFT with fewer NFE on LLaDA-8B SFT, directly addressing the data efficiency debate between masked diffusion and autoregressive models.