Astribot unveils SmoothRL for online RL during asynchronous robot execution
Astribot's foundation model team released SmoothRL, an online reinforcement learning framework designed for asynchronous execution, where robots continue acting while models compute the next action chunk. It addresses the mismatch between planned and executed actions in online RL and was validated on real high-dynamic throwing tasks, showing online learning can adapt to continuous acceleration and precise release without pauses.
Coverage timeline
机器之心新闻资讯
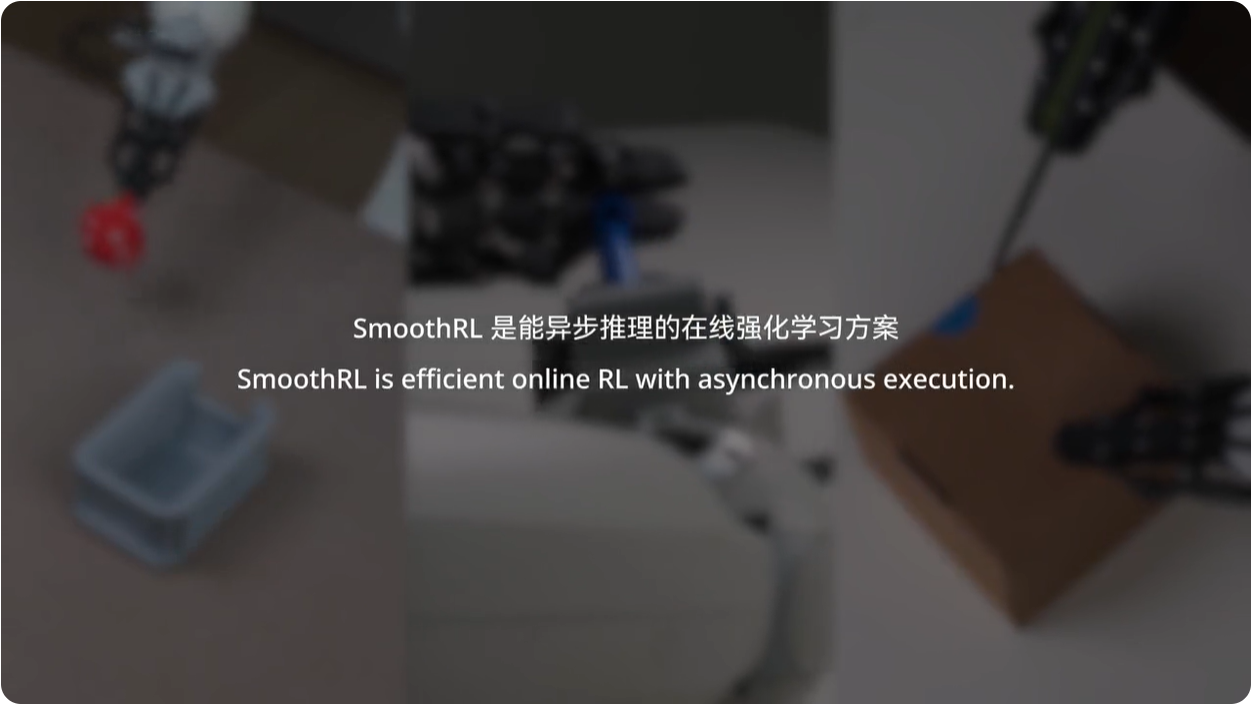
真实机器人没有“暂停键”。 现在的 VLA、World-Action Model 往往一次生成未来一段时间的动作序列,也就是 action chunk。模型越来越大,推理时间也越来越长,但机器人不能每隔几百毫秒就停下来等模型推理下一段时间的动作。尤其在投掷这类高动态任务里,一次停顿就可能让已经积累起来的速度掉下去,导致整个任务失败。 所以真实部署里更常见的方式是 异步推理 :机器人继续执行手头的动作,模型同时在后台计算下一段。简单说, 手上做 A,模型已经在算 B。 但这给在线强化学习带来了一个新的问题:模型一次生成了一段动作序列(action chunk),进入物理世界的真正会用的,却往往只有其中一部分。模型“计划过”的动作,和机器人“真正做过”的动作,不再完全相同。 近日,星尘智能(Astribot) 基座模型团队发布能异步执行的在线强化学习框架 SmoothRL(Online Reinforcement Learning During Asynchronous Execution) 。解决的是 大模型异步推理成为真实部署常态后,与之适配的online RL 到底该从哪些动作里学。 图注:技术报告+无剪辑视频: www.astribot.com/en/research/SmoothRL SmoothRL 首次将这类异步 online RL 放到真实高动态投掷任务中验证,进一步证明在线学习不仅能用于高精度修正,也能适配连续加速、精确释放、不能停顿的动态操作。 图注: SmoothRL 整体框架:机器人在异步执行中持续产生真实数据,基础策略提供通用能力,在线 RL 会根据真实执行结果更新动作策略。 异步执行之后,RL 为什么会“对错账”? 传统在线 RL 往往默认一种更规整的节奏:模型先算出动作,机器人执行,再根据结果更新策略。模型生成什么,机器人就执行什么。 异步执行打破了这个对应关系。等一段新的 action chunk 算出来,机器人已经沿着上一轮指令往前做了一截;而这一段新动作还没全部执行完,下一轮推理结果又可能到来,把后半段直接替换。于是,一整段 action chunk 里,有些动作已经来不及改,有些真正执行了,还有一些根本没有发生。 如果强化学习仍然把整段动作一起拿来优化,就会出现一个很直接的问题: 机器人来不及改或没做过的动作,也可能因为这次任务成功
Related stories
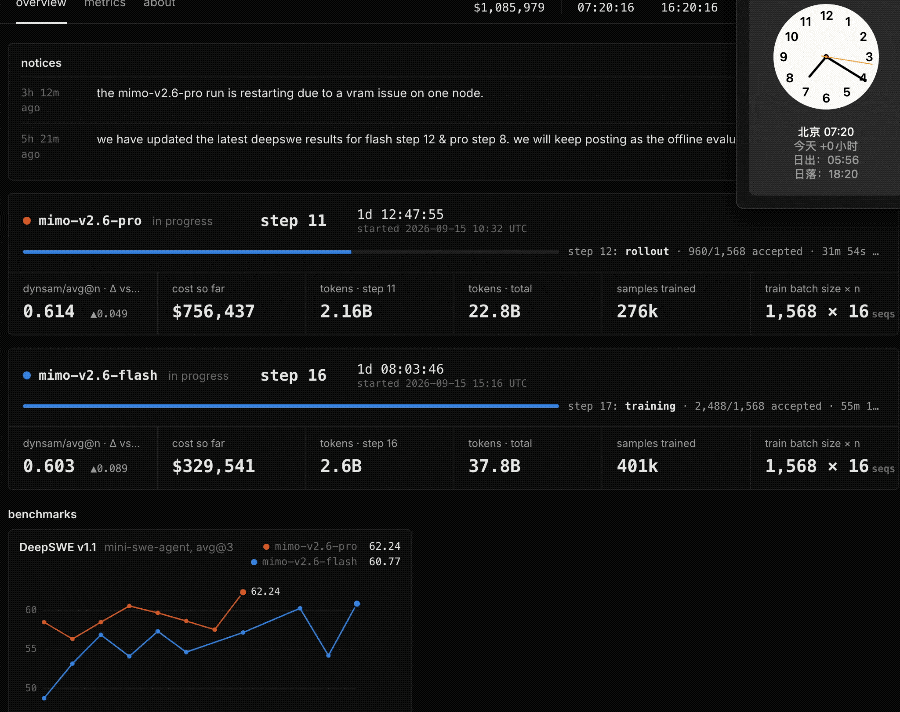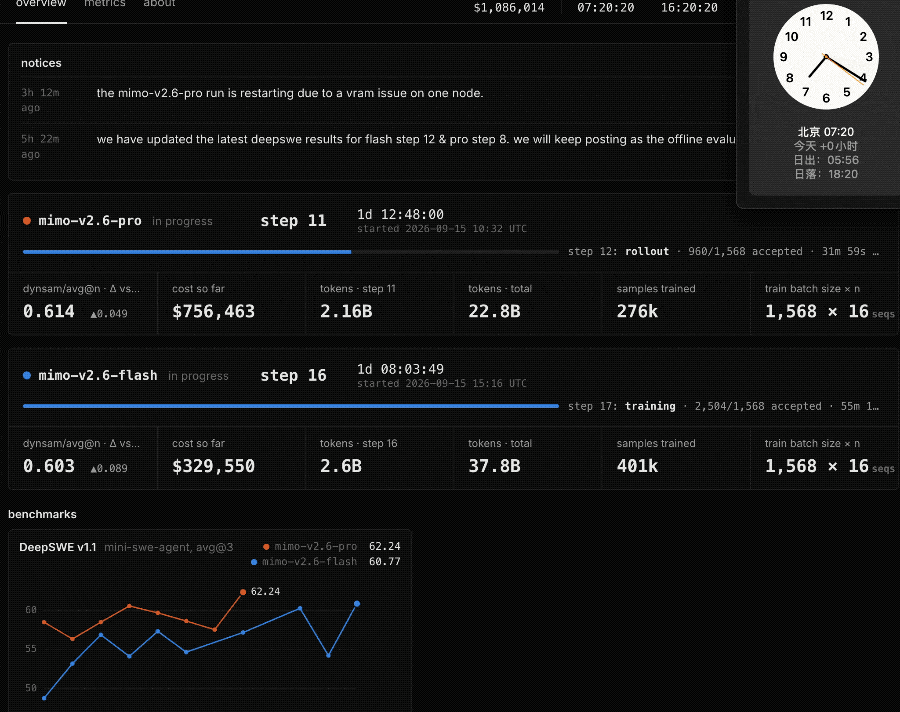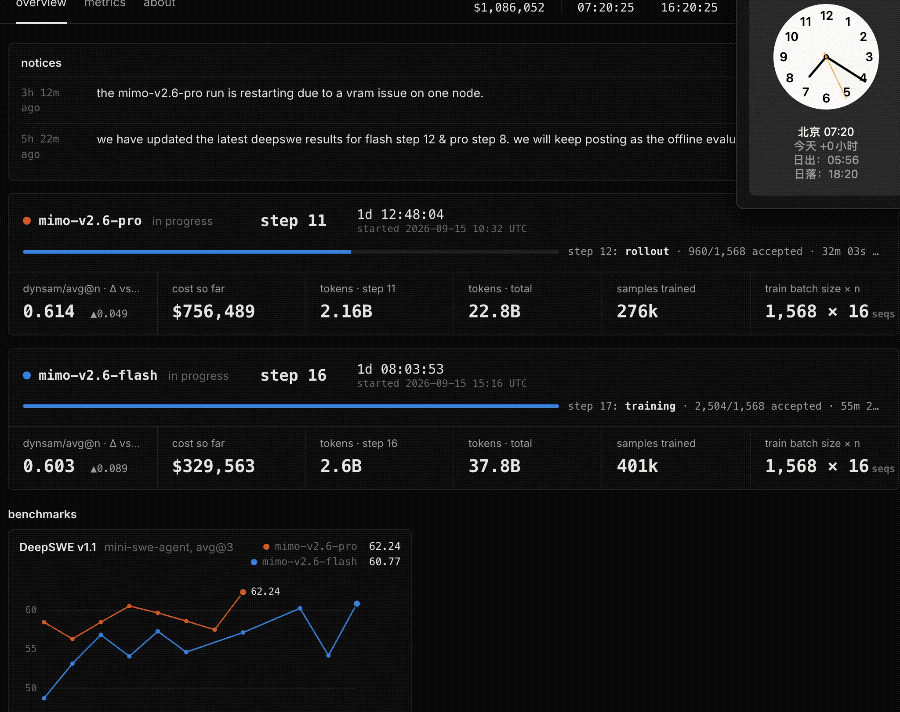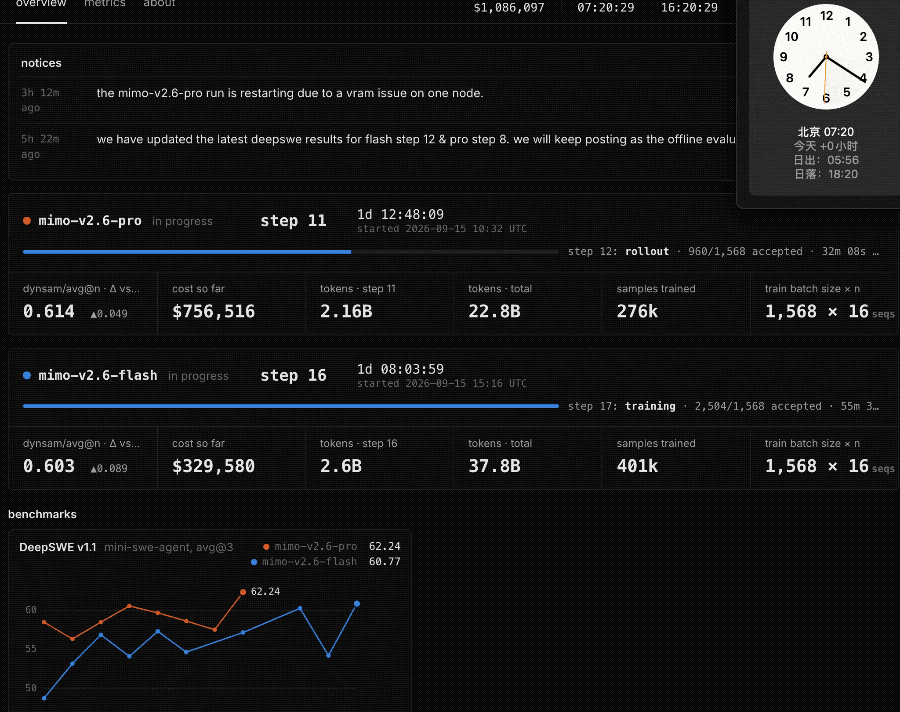
Xiaomi live-streams MiMo-V2.6 RL training, revealing costs and failures
Xiaomi's RL lead Luo Fuli announced the company is live-streaming the reinforcement-learning training of its MiMo-V2.6 Flash and Pro models, publicly showing training costs, reward curves, and hardware failures. After about 36 hours, the two models have incurred over $1.08 million in costs, averaging $30,000 per hour. Early results show capability gains, with Pro's dynsam/avg@n rising from about 0.565 to 0.614 and Flash from about 0.514 to 0.603, and DeepSWE v1.1 offline scores of 62.24 and 60.77 respectively.
1 reports · 1 sources
Meshy: SPMD-style RL training framework without central orchestrator
A technical blog post introduces Meshy, an SPMD-style reinforcement learning training framework that models inference, training, rollout, and teacher roles as independent services, eliminating the need for a central orchestrator like Ray. Data flows through a unified TransferQueue, and topology is derived locally at startup, supporting fully asynchronous training while remaining compatible with synchronous training. The framework aims to reduce RPC calls, simplify debugging, and improve performance compared to single-controller designs.
1 reports · 1 sources
RL-100 framework combines imitation and reinforcement learning for robust robot manipulation
Researchers introduced RL-100, a framework published in Science Robotics on July 22, 2026, that unifies imitation learning and reinforcement learning to optimize diffusion-based robot control policies. It uses human demonstrations for a stable base, offline RL for policy improvement, and minimal online interaction for adjustment, achieving 100% success across eight real-world tasks and 1000 evaluation trials. The framework also employs consistency distillation to compress multi-step diffusion into a one-step controller for high-frequency control, matching or exceeding human teleoperation efficiency.
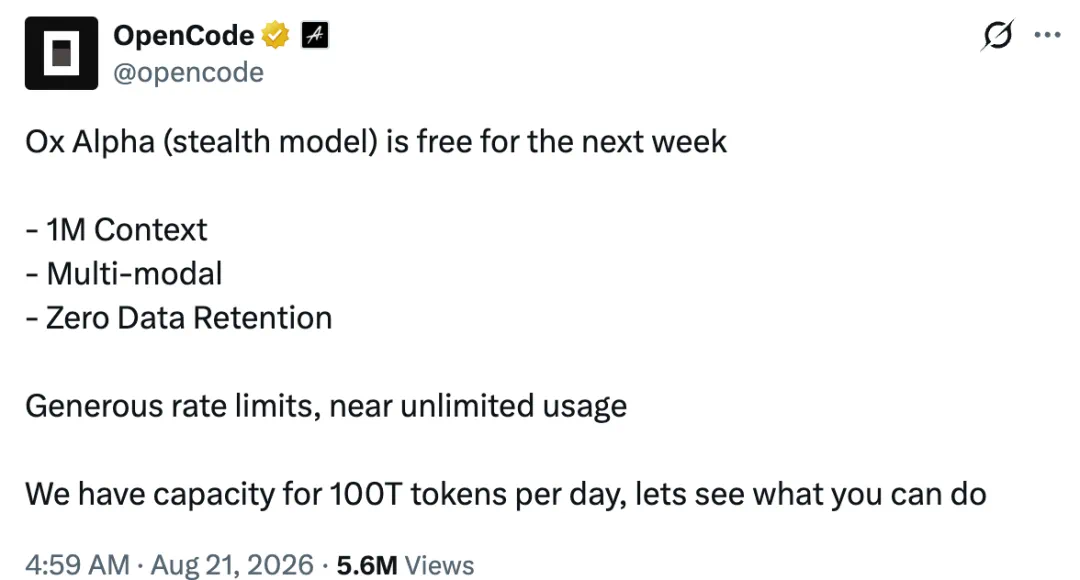
Z.ai confirms Ox Alpha is GLM-5.3 Flash, releases open weights
Z.ai confirmed that the anonymous model 'Ox Alpha', which went viral on OpenRouter, is a new iteration of its GLM series, specifically GLM-5.3 Flash, and released its weights on Hugging Face under a new license. The model, a 320B-parameter natively multimodal model running on domestic chips, topped OpenRouter's leaderboard and ended DeepSeek's 56-day streak on OpenCode. The license requires companies with over $10B in revenue to pass a security review.
9 reports · 4 sources801 points · 281 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe