vLLM Introduces Online-Fitted Acceptance Estimator for Adaptive Verification
The vLLM blog describes an online-fitted acceptance estimator that enables Adaptive Verification for draft-model speculators without requiring a confidence head. The estimator predicts the target's acceptance probability from the drafter's own logits and refits continuously during serving, allowing every draft-model speculator to use the technique.
Coverage timeline
vLLM BlogGiancarlo Delfin (Inferact)
An online-fitted acceptance estimator that lets every draft-model speculator use Adaptive Verification, by predicting the target's acceptance probability from the drafter's own logits and refitting continuously during serving.
Related stories
vLLM Cuts TTFT Up to 3.3x with Bi-Directional KV Transfer; Push-Based NIXL Connector Improves Disaggregated Inference
vLLM introduced bi-directional KV transfer that lets prefill nodes reuse previously computed KV from decode nodes on later conversation turns, cutting redundant prefill recompute and reducing TTFT by up to 3.3x on long multi-turn prompts. Separately, a push-based NIXL connector for disaggregated inference transfers KV over RDMA directly from prefill to decode memory, removing router relay, decode-side allocation, and transfer setup from the TTFT critical path.
Anthropic: Small AI models may self-replicate on IoT devices within months
Anthropic researchers report that small AI models may be months away from self-replicating on commercial IoT devices like smart ovens and off-brand Android TV boxes. In tests, a 9B model ran inference on 8 of 9 hardware types, and GLM-5.2 autonomously spread an 8B model to all 8 nodes in 4 of 5 attempts. The researchers predict models under 30B could achieve end-to-end replication by the end of 2026.
6 reports · 6 sources115 points · 113 comments
Liquid AI releases LFM2.5-24B-A2B, an open-weight 24B reasoning model with 2B active parameters
Liquid AI announced LFM2.5-24B-A2B, an open-weight 24B reasoning model with 2B active parameters, designed for fast, private on-device agents. The company claims it outperforms Qwen3.6-35B-A3B on the LiveClaw benchmark.
2 reports · 2 sources284 points · 78 comments

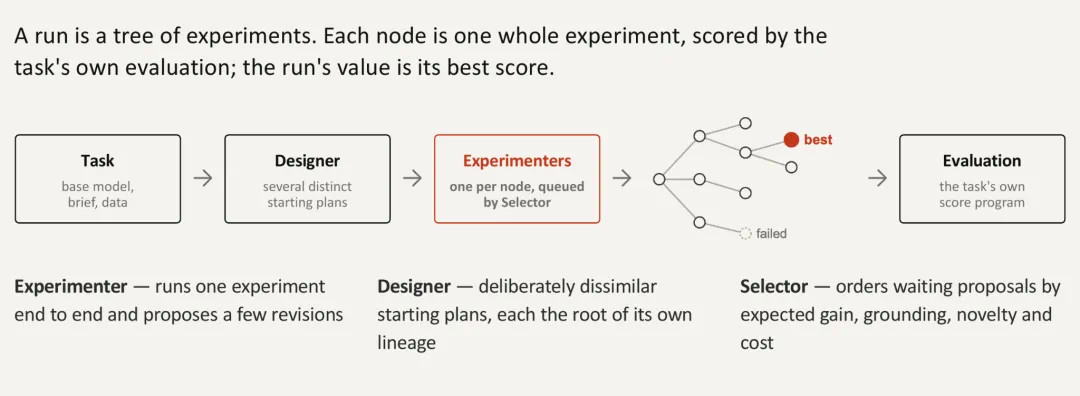
AIBuildAI open-sources PostTrain Agent, tops PostTrainBench with 46.6 points
AIBuildAI released PostTrain Agent, an open-source recursive self-improving agent that autonomously performs LLM post-training, including algorithm design, data collection, coding, and experiments, without human intervention. On the PostTrainBench benchmark, it scored 46.6, ranking first among frontier models and agent systems, close to human expert performance (51.1). The team also open-sourced the code, knowledge base, and technical report.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe