AlphaGo co-author Thore Graepel: LLMs cannot reason, leaves DeepMind to build reasoning AI
Thore Graepel, a core author of AlphaGo, published an MIT Technology Review essay arguing that large language models cannot truly reason, drawing praise from Turing Award winner Yann LeCun. He also announced he has left Google DeepMind to start a company focused on giving machines real reasoning ability, citing AlphaGo's move 37 as an example of reasoning through search rather than intuition.
Coverage timeline
机器之心机器之心
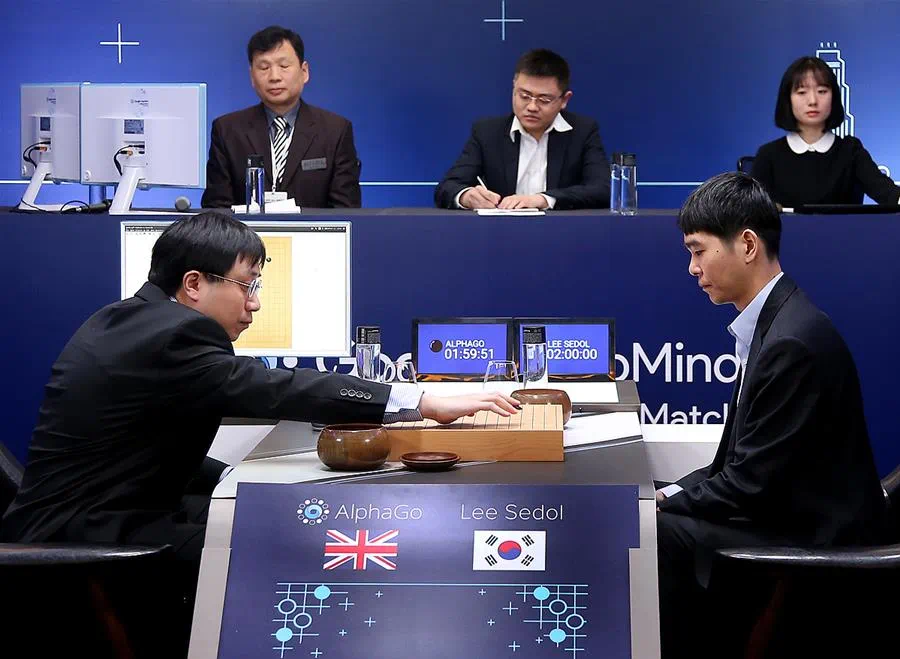
2016 年 3 月,首尔四季酒店。 人机大战第二局进行到中途,AlphaGo 把一颗黑子落在了第五线上。现场解说一时语塞,有人怀疑程序出了 bug,因为在职业棋手的常识里,这手棋近乎于白送。 后来的故事大家都知道了。AlphaGo 不仅赢下了那一局,还以 4:1 的总比分击败了李世石。赛后李世石说了一段被反复引用的话:「我原以为 AlphaGo 只是基于概率计算的机器。但看到那一手,我改变了想法。AlphaGo 一定有创造力。」 那就是著名的第 37 手。 十年过去,当年亲手造出 AlphaGo 的人却站出来说了一句:那一手棋所依赖的能力,今天的 AI 恰恰没有。 说这话的人是 Thore Graepel,AlphaGo 的核心作者之一,长期从事机器学习研究。最近他做了一个颇耐人寻味的决定 —— 离开 Google DeepMind,去创业做一件他认为更要紧的事:给机器装上真正的推理能力。 那个辛辣的观点出自他最近发布在 MIT Technology Review 上的一篇文章,文章标题非常直接,就叫「别被骗了 ——LLMs 不会推理」。看完这篇文章,图灵奖得主 Yann LeCun 表示赞赏,强调「真正的推理必须涉及搜索,LLM 不具备这一能力」。 Thore Graepel 为什么这么说?我们一起来看看这篇文章写了什么。 第 37 手不是「灵光一闪」,而是推理的产物 很多人对第 37 手的叙事是「机器直觉的神话时刻」——AI 电光石火之间,看到了人类千年棋谱之外的妙手。Graepel 说,这是大家对 AlphaGo 最大的误解。 要理解这一点,得先拆开 AlphaGo 的内部构造。它由两套系统组成:一套是策略网络(policy network),通过学习海量人类棋谱,来预测「高手在这一局面会怎么下」,这是直觉的部分。另一套是搜索机制,它不关心某手棋「看起来像不像人下的」,而是显式地构建一棵包含数千个分支的博弈树,逐一推演每个候选落点通向的未来。 关键在于:在策略网络眼里,第 37 手平平无奇 —— 职业人类棋手下出这一手的概率大约只有万分之一。如果只听直觉的,这一手根本不会被选中。是搜索机制在深算之后发现,这手「不像话」的棋通向一个更好的终局。 Graepel 借用了卡尼曼那个著名的框架来解释这件事。人类的思考分为两种模式:系统 1 快、凭直觉、毫不费力;系统
Related stories
Google DeepMind alumni launch startups exploring alternatives to LLMs
Bloomberg reports that a wave of Google DeepMind researchers have recently left to launch AI startups focused on alternatives to large language models. The report highlights a London breakfast attended by 15 current and former DeepMind employees where the topic was discussed.
1 reports · 1 sources
DeepMind launches institute to debate AGI deployment, Legg warns on safety
Google DeepMind cofounder Shane Legg has launched the DeepMind Institute to publicly explore questions around the deployment of artificial general intelligence (AGI). Legg warned that advancing AI must never run ahead of safety, amid growing calls for an industry slowdown.
2 reports · 2 sources
Anthropic CEO proposes 'pacing the frontier' plan; OpenAI, Musk, Hugging Face respond
Anthropic CEO Dario Amodei published an essay on September 12, 2026, urging the AI industry to slow the pace of frontier model development to address safety risks, proposing a three-part plan: embedded third-party evaluators, coordination among democratic countries, and global coordination including with authoritarian governments. Anthropic unilaterally committed to giving third-party evaluators permanent employee-level access. OpenAI CEO Sam Altman agreed and said OpenAI would do the same, while Elon Musk endorsed the call and Hugging Face launched an Open Alignment Initiative seeking to join the embedded evaluators program.
25 reports · 6 sources330 points · 260 comments

Essay Claims LLMs Do Not Reason, Ignites Debate
An essay arguing that large language models do not actually reason has sparked widespread discussion on Hacker News. The piece challenges the perceived reasoning capabilities of LLMs, prompting a debate among researchers and practitioners about the nature of these models' outputs.
1 reports · 1 sources75 points · 159 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe