Alibaba releases Qwen3.8-Flash, an open-weight 125B-param model on Qwen 4 architecture
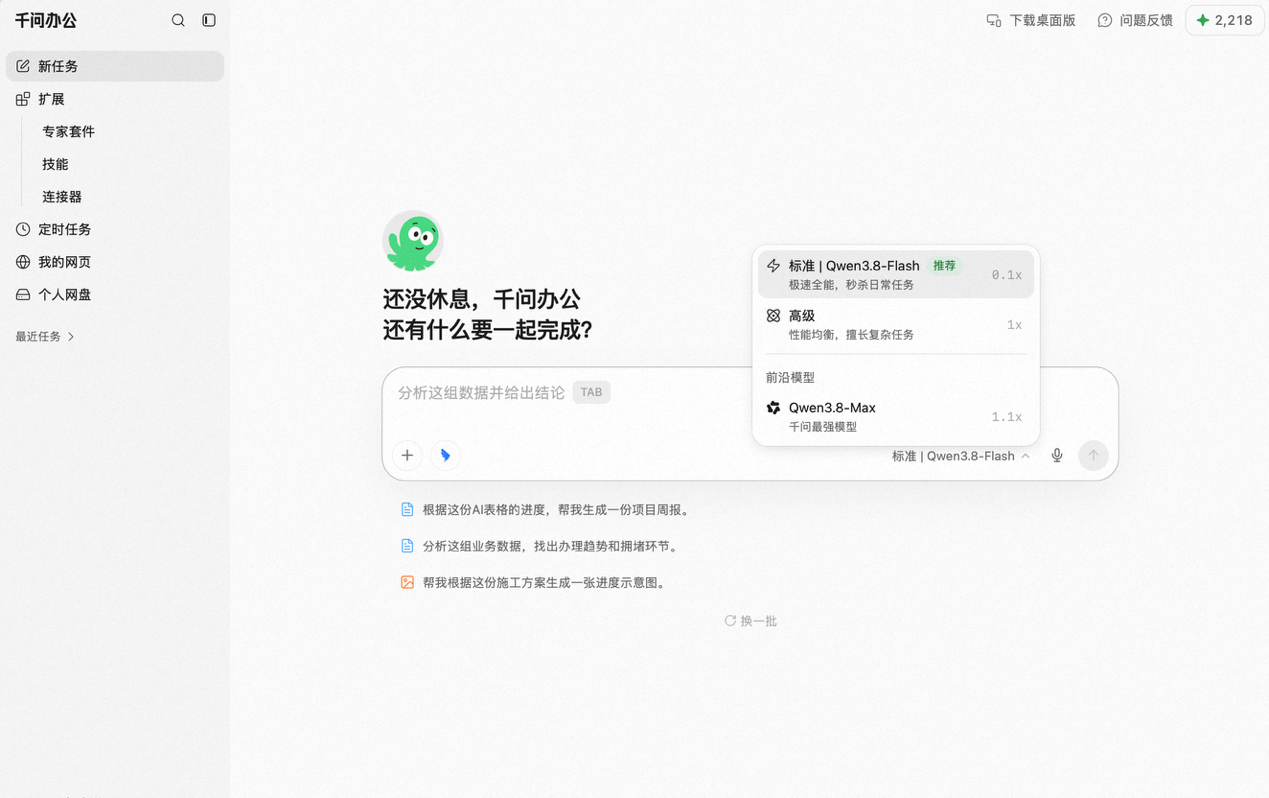
Alibaba released Qwen3.8-Flash, an open-weight 125B-parameter multimodal mixture-of-experts model built on its next-gen Qwen 4 architecture, claiming it rivals Claude Opus 4.6 and V4-Flash. The model has only 6B active parameters, and Qwen Office launched a standard mode powered by it, reporting ~100% faster generation and 75% lower token consumption in real office-task tests. The release also serves as an early preview of the Qwen 4 architecture.
Coverage timeline
Hacker Newsgaro-pro
Techmeme
Luz Ding / Bloomberg : Alibaba releases Qwen3.8-Flash, an open-weight, 125B-parameter model built on its next-gen Qwen 4 architecture, saying it rivals Opus 4.6 and V4-Flash — Alibaba Group Holding Ltd. released the latest model under its popular Qwen series, a lower-priced platform aimed at driving adoption of its marquee AI offering globally.

Hacker Newstosh
Simon Willison
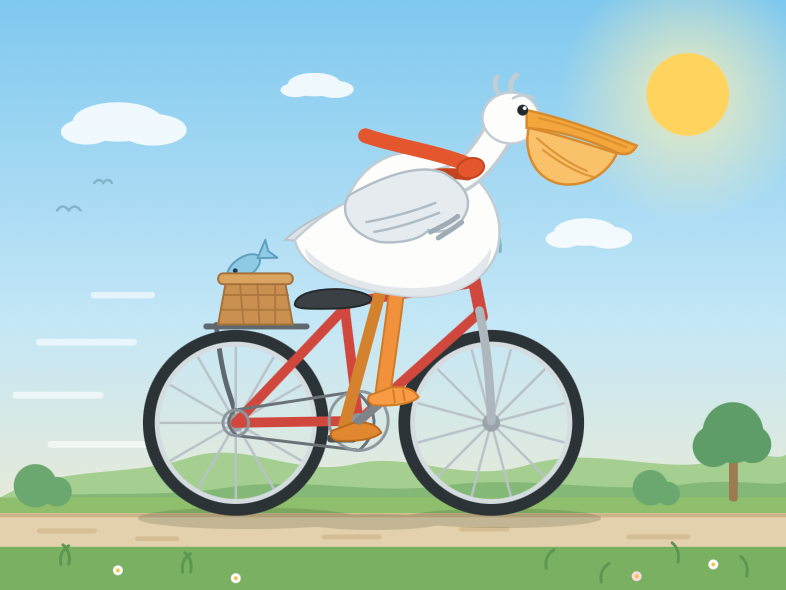
Qwen3.8-Flash-Next Another open weights model from Qwen. This one is "a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4". It's pretty big: 125B tokens, but only 6B active which means it gets a significant performance boost. I've been trying it out on a DGX Spark using these Unsloth quantized models . I'm still exploring the model - so far I've tried the 72.5GB UD-IQ1_S one (producing these pelicans ) and the 78.9GB UD-Q2_K_XL (producing these ). My favorite so far was this xhigh reasoning effort one from UD-Q2_K_XL: Via Hacker News Tags: ai , generative-ai , llms , qwen , pelican-riding-a-bicycle , ai-in-china , nvidia-spark
量子位量子位
千问办公首发上线Qwen3.8-Flash,生成速度提升100%,Token消耗减少75% 量子位的朋友们 2026-08-27 09:45:08 来源: 量子位 8月26日晚,千问办公首发上线刚刚发布的Qwen3.8-Flash模型,同时推出标准模式。 8月26日晚,千问办公首发上线刚刚发布的Qwen3.8-Flash模型,同时推出标准模式。即日起,所有用户可通过全新的标准模式体验Qwen3.8-Flash。基于最新的模型,用户可以用更少的积分消耗、更快的Token吞吐速度完成任务。未来,千问办公的模型供给将只有标准和高级两种模式,95%的日常任务通过千问办公标准模式即可完成,仅5%的复杂任务需要使用高级模式。 用户体验的提升来自模型升级与Agent协同优化。全新架构的Qwen3.8-Flash以千亿级总参数实现了超越Claude Opus 4.6的性能。同时,千问大模型团队与千问办公团队还联合推出了办公专属版本Qwen3.8-Flash,针对多步规划、工具选择、上下文压缩等场景进行专项训练调优,并通过推理优化和定制Harness架构进一步实现吞吐效率提升。在真实办公场景测试中,千问办公标准模式的单任务生成速度提升约100%,Token消耗平均减少75%。 在真实AI应用场景,高性能通常意味着高成本和高延迟,低成本则需要以牺牲智能为代价。Agent与模型的深度协同优化,正在打破性能、成本和速度的“不可能三角”。随着模型智能密度的持续提升,以及千问办公与模型的双向优化,Agent即将告别Token焦虑,迎来“量大管饱”时代。 本文由千问提供,量子位获授权转载,观点归原作者所有。 版权所有,未经授权不得以任何形式转载及使用,违者必究。
机器之心新闻资讯
8月26日晚,千问办公首发上线刚刚发布的Qwen3.8-Flash模型,同时推出标准模式。即日起,所有用户可通过全新的标准模式体验Qwen3.8-Flash。基于最新的模型,用户可以用更少的积分消耗、更快的Token吞吐速度完成任务。未来,千问办公的模型供给将只有标准和高级两种模式,95%的日常任务通过千问办公标准模式即可完成,仅5%的复杂任务需要使用高级模式。 用户体验的提升来自模型升级与Agent协同优化。全新架构的Qwen3.8-Flash以千亿级总参数实现了超越Claude Opus 4.6的性能。同时,千问大模型团队与千问办公团队还联合推出了办公专属版本Qwen3.8-Flash,针对多步规划、工具选择、上下文压缩等场景进行专项训练调优,并通过推理优化和定制Harness架构进一步实现吞吐效率提升。在真实办公场景测试中,千问办公标准模式的单任务生成速度提升约100%,Token消耗平均减少75%。 在真实AI应用场景,高性能通常意味着高成本和高延迟,低成本则需要以牺牲智能为代价。Agent与模型的深度协同优化,正在打破性能、成本和速度的“不可能三角”。随着模型智能密度的持续提升,以及千问办公与模型的双向优化,Agent即将告别Token焦虑,迎来“量大管饱”时代。