Ant Group's OmniTable wins VLDB 2026 industrial best paper, cuts SFT data prep from 14 days to 2.5
Ant Group's OmniTable, a unified wide-table system for petabyte-scale LLM data curation, won the VLDB 2026 industrial best paper award at the conference in Boston on September 1. In production, it manages over 35 PB and 305 billion records of training data, and in a real SFT preparation task it cut the end-to-end cycle from about 14 days to 2.5 days, reducing manual steps from 45 to 12.
Coverage timeline
量子位量子位
还在为大模型洗数据熬夜?蚂蚁拿下VLDB工业最佳论文,一套宽表搞定35PB语料,效率狂飙5.6倍 量子位的朋友们 2026-09-02 14:20:17 来源: 量子位 蚂蚁集团推出统一宽表系统OmniTable,论文获评VLDB 2026工业赛道最佳论文 训练一个大模型之前,语料要经过解析、清洗、去重、质量评分、Token 化和样本组装。规模来到 PB 级,工程团队每天面对的不止算力账单,还有数百张表、不断增加的特征,以及少数几条就可能让整批任务重跑的异常数据。 今年的 VLDB 工业赛道最佳论文,关注的正是大模型训练中非常重要,但也常被忽视的环节——数据准备。论文《OmniTable: A Unified Wide-Table System for Petabyte-Scale LLM Data Curation and Exploration》介绍了一套由蚂蚁集团研发的统一宽表系统 OmniTable。 (图说:蚂蚁集团论文《OmniTable: A Unified Wide-Table System for Petabyte-Scale LLM Data Curation and Exploration》获评 VLDB 2026 工业赛道最佳论文,9 月 1 日在波士顿举行的大会上获颁奖项。) 论文链接:https://www.vldb.org/pvldb/vol19/p4276-fu.pdf 论文披露,OmniTable 已在生产环境管理超过 35 PB、3050 亿条以上的大模型训练数据,覆盖 Web、代码、PDF 和 SFT 等数据域。在一项真实 SFT 数据准备任务中,端到端周期从约 14 天缩短到 2.5 天,手工操作步骤从 45 步降至 12 步。 这个结果并非来自一台更快的机器。OmniTable 改了数据工程师组织数据和特征的方式:同一数据域在上层呈现为一张逻辑宽表,底层继续按数据规模、访问方式和计算引擎拆分;特征也从脚本中的临时计算,变成带有定义、版本、依赖和血缘的系统资产。 一个特征,为什么会牵出 106 张表 传统的大模型数据加工通常围绕物理表展开。一个数据源接入后,解析结果落一张表,清洗结果再落一张,质量分、领域标签、去重签名和安全标记继续产生新的表或中间结果。Web、代码、PDF、SFT 又各自维护一套流程。 单条管道并不难理解。数
Related stories
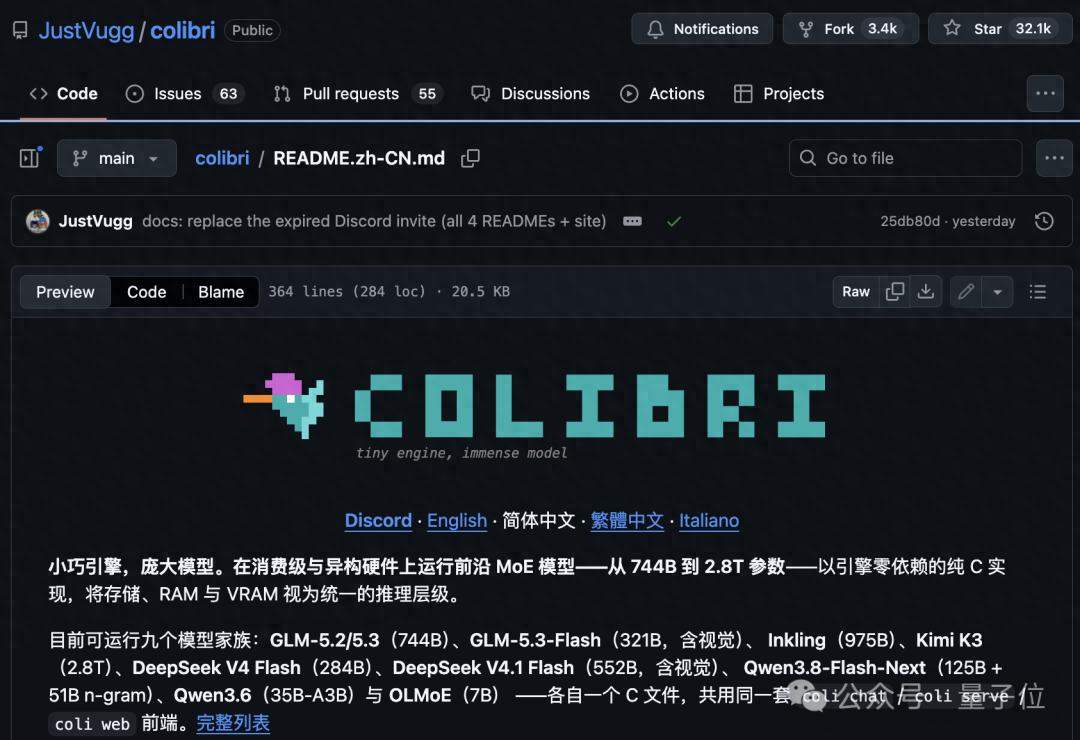
Colibrì: C-based inference framework runs 744B-param GLM-5.2 on laptops via SSD offloading, no GPU needed
Colibrì, an open-source C-based hierarchical inference framework, has gained 32k GitHub stars for enabling large MoE models to run on laptops with limited RAM by offloading inactive experts to SSD, without requiring a GPU. It supports models from GLM-5.2/5.3, DeepSeek V4 Flash, Qwen, to 975B Inkling and 2.8T Kimi K3, with RAM requirements as low as 16GB for int4-processed GLM-5.2.
1 reports · 1 sources
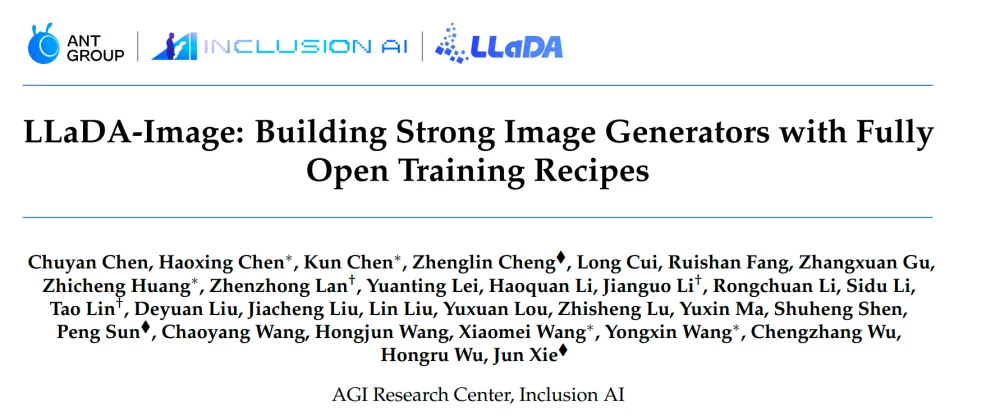
Inclusion AI's 6B LLaDA-Image tops Qwen-Image-Bench, open-sources weights
Inclusion AI released LLaDA-Image, a 6B-parameter diffusion transformer trained from scratch, achieving top scores on Qwen-Image-Bench for both English (53.53) and Chinese (53.38) among open-source models. Over 90% of its 220 million cumulative training samples used image-only supervision, with image-text pairs reserved for later language alignment. The model weights, training code, and recipes are open-sourced, along with a distilled Turbo variant requiring only 2-4 sampling steps.
1 reports · 1 sources
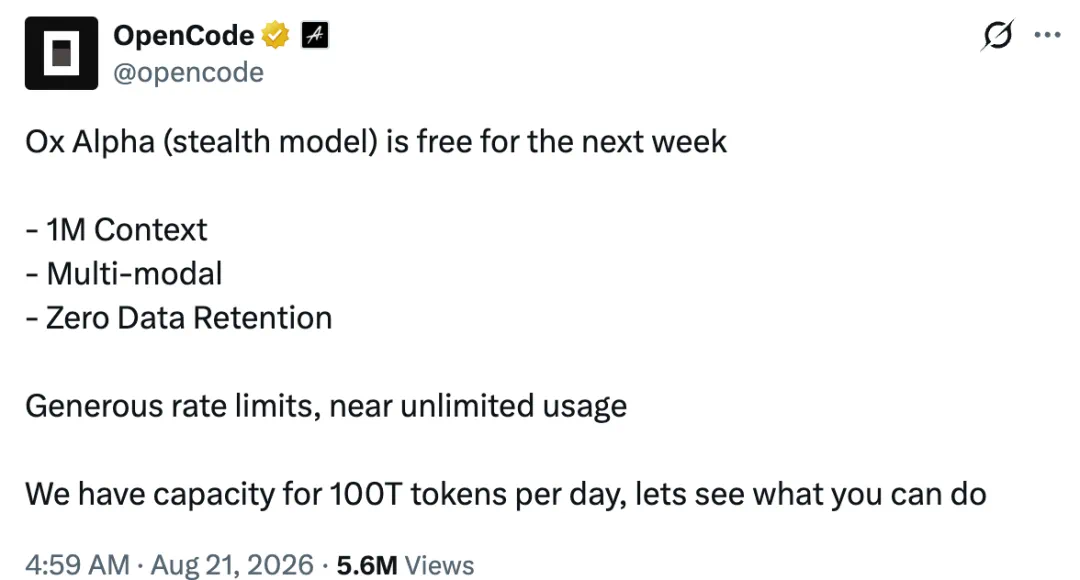
Z.ai confirms Ox Alpha is GLM-5.3 Flash, releases open weights
Z.ai confirmed that the anonymous model 'Ox Alpha', which went viral on OpenRouter, is a new iteration of its GLM series, specifically GLM-5.3 Flash, and released its weights on Hugging Face under a new license. The model, a 320B-parameter natively multimodal model running on domestic chips, topped OpenRouter's leaderboard and ended DeepSeek's 56-day streak on OpenCode. The license requires companies with over $10B in revenue to pass a security review.
9 reports · 4 sources801 points · 281 comments
Alibaba releases Qwen3.8-Max, open weights due next week
Alibaba released Qwen3.8-Max, a 2.4-trillion-parameter MoE model with 95B active parameters, on August 3, 2026. It tops several benchmarks, including Artificial Analysis's Agentic Index (55.4) and OSWorld-Verified (86.1), and its API is now available on QwenCloud with open weights expected next week. The model also powers Alibaba's new agent product 'Qwen Office'.
4 reports · 3 sources1110 points · 608 comments

News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe