iFlytek unveils Spark X2.5, a 293B MoE trained on domestic 10k-card cluster
On September 7, 2026, iFlytek released the Spark X2.5 model, a 293B-A30B MoE architecture focused on code and agent capabilities, covering over 200 languages. The model was pre-trained and post-trained on a domestic 10,000-card 910B cluster, with inference also on domestic platforms using multi-step speculative decoding. Notably, Spark X2.5 now participates in optimizing NPU operators, marking AI's role in refining underlying compute.
Coverage timeline
机器之心机器之心
编辑|Clio 最近几个月,国产 AI 算力开始密集跨过一个新的数量级。 7 月,全国产十万卡 AI 超集群落成;9 月初,无锡国产万卡级智算中心一期 2000 张摩尔线程 MTT S5000 GPU 智算卡已全部投入运行,集群算力需求基本达到满载;国产卡正在进一步向万卡乃至十万卡级训练基础设施迈进。 无锡(惠山)国产智算中心机房内 集群规模越来越大,新的问题也随之而来:这些芯片究竟能发挥出多少实际训练能力? 大模型训练里,卡数增加的同时,系统复杂度也会跟着上升。一块芯片上的算子效率差异,放到数万块芯片上会不断被放大;小规模训练里不太显眼的通信等待,到了万卡集群会变得很可观;节点数量增加、训练周期拉长之后,软硬件故障也会更频繁地进入日常运维。 因此,评价一套算力系统,除了看芯片数量和单卡性能,还要看算子、通信、并行调度、故障恢复以及软件栈之间能不能配合起来。 最近一个新发布的模型引起了我们的注意。 9 月 7 日,科大讯飞正式发布星火 X2.5。该模型采用 MoE 架构,参数规模为 293B-A30B,重点提升代码和智能体能力,同时覆盖 200 余种语言,在语言理解、答题、推理等通用任务上保持优异效果。 其中,万卡规模国产 910B 集群承担了模型的预训练和后训练,线上推理基于国产平台,并配合多步投机解码提升推理效率。 值得一提的是,随着代码和工具调用能力增强,星火 X2.5 也开始参与 NPU 算子优化,AI 开始反过来参与底层算力的优化。 通过这次真实的大模型训练,也可以进一步探讨万卡国产算力面临的几个具体工程问题:算子效率、长上下文处理、万卡通信和长周期训练稳定性,以及模型与底层算力之间正在形成怎样的反馈关系。 这次星火 X2.5 的训练优化,也基本围绕这些问题展开。 万卡国产芯片,怎么真正干活? 可以把大模型训练想象成一座超大型工厂。 万卡集群里的芯片,是成千上万名「工人」;显存是存放模型参数、上下文和中间数据的「仓库」;通信网络则是芯片之间交换数据的「运输通道」。当规模扩大到万卡级,计算速度、显存容量、通信效率和系统稳定性,都会直接影响整座「工厂」的效率。 而推理和训练,对这座「工厂」的要求并不相同,这也是「推理适配」和「全国产训推」的关键区别。 推理适配主要解决模型能否在国产芯片上高效部署运行;完整训练还涉及参数持续更新、跨卡同步、数值稳定和长周期故障恢

Related stories
Z.ai confirms Ox Alpha is GLM-5.3 Flash, releases open weights
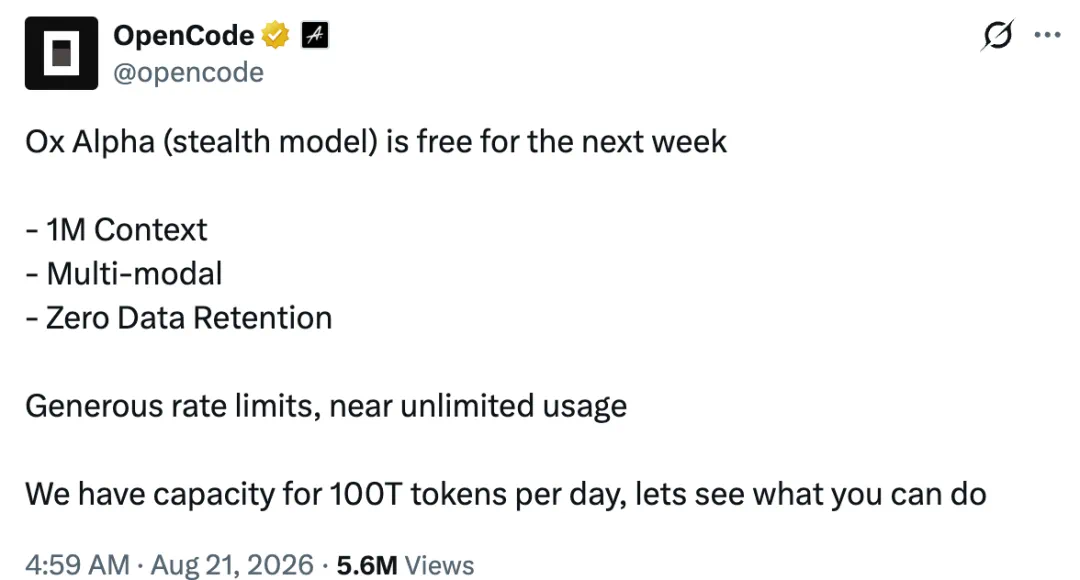
Z.ai confirmed that the anonymous model 'Ox Alpha', which went viral on OpenRouter, is a new iteration of its GLM series, specifically GLM-5.3 Flash, and released its weights on Hugging Face under a new license. The model, a 320B-parameter natively multimodal model running on domestic chips, topped OpenRouter's leaderboard and ended DeepSeek's 56-day streak on OpenCode. The license requires companies with over $10B in revenue to pass a security review.
9 reports · 4 sources801 points · 281 comments
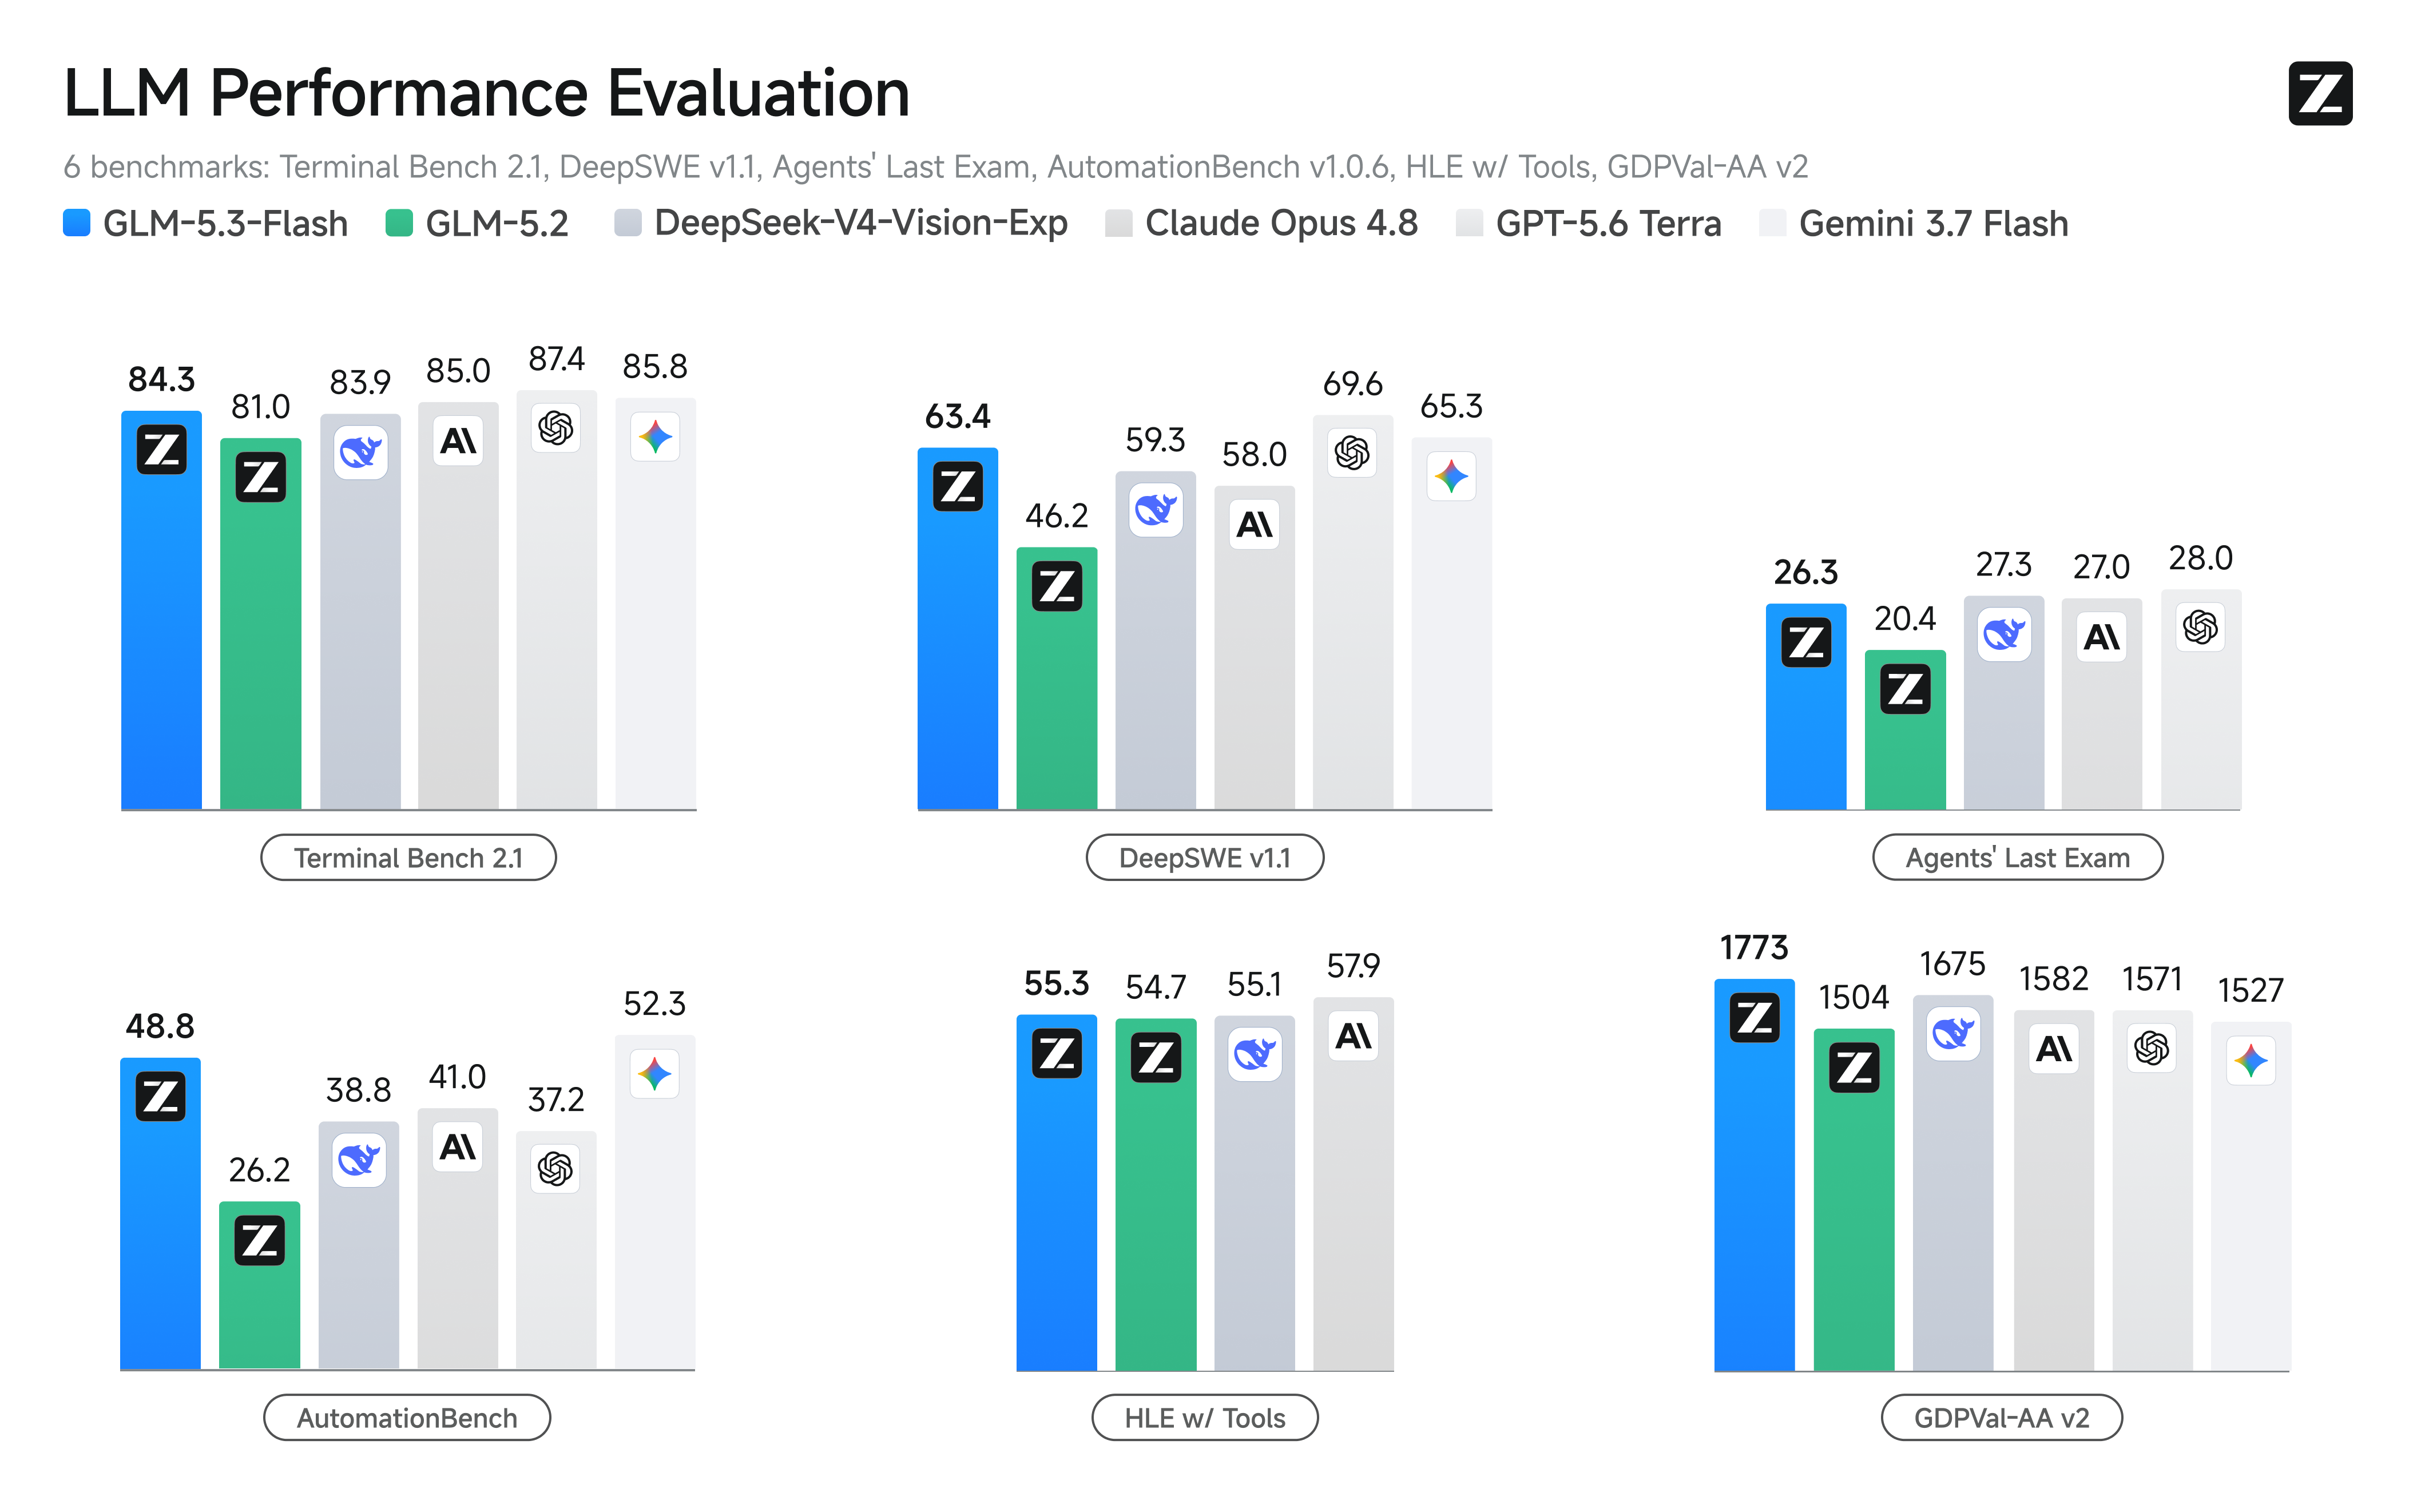
Zhipu AI open-sources GLM-5.3-Flash, a 320B multimodal model priced at 1/40 of Claude Opus 4.8
Zhipu AI released and open-sourced GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series, with 320B total parameters (18B active). It scores 57 on the Artificial Analysis Intelligence Index, matching Claude Opus 4.8, and is priced at one-tenth of GLM-5.3, or one-fortieth of Opus 4.8. The model uses a hybrid sparse and linear attention architecture, runs on domestic Chinese chips, and was tested anonymously as Ox-Alpha on OpenRouter and OpenCode.
8 reports · 5 sources1126 points · 573 comments
Meta releases Muse Spark 1.3, claims big coding gains at same price
Meta released Muse Spark 1.3 on Wednesday, available in Muse Code and the Meta Model API, claiming significant improvements in coding and agentic performance at the same price as Spark 1.2. The max reasoning variant, in limited preview for partners, scored 62 on the Artificial Analysis Intelligence Index, behind only Claude Fable 5.1 and Claude Opus 5. Mark Zuckerberg also said the Watermelon model and Muse Spark open weights are coming soon.
3 reports · 1 sources
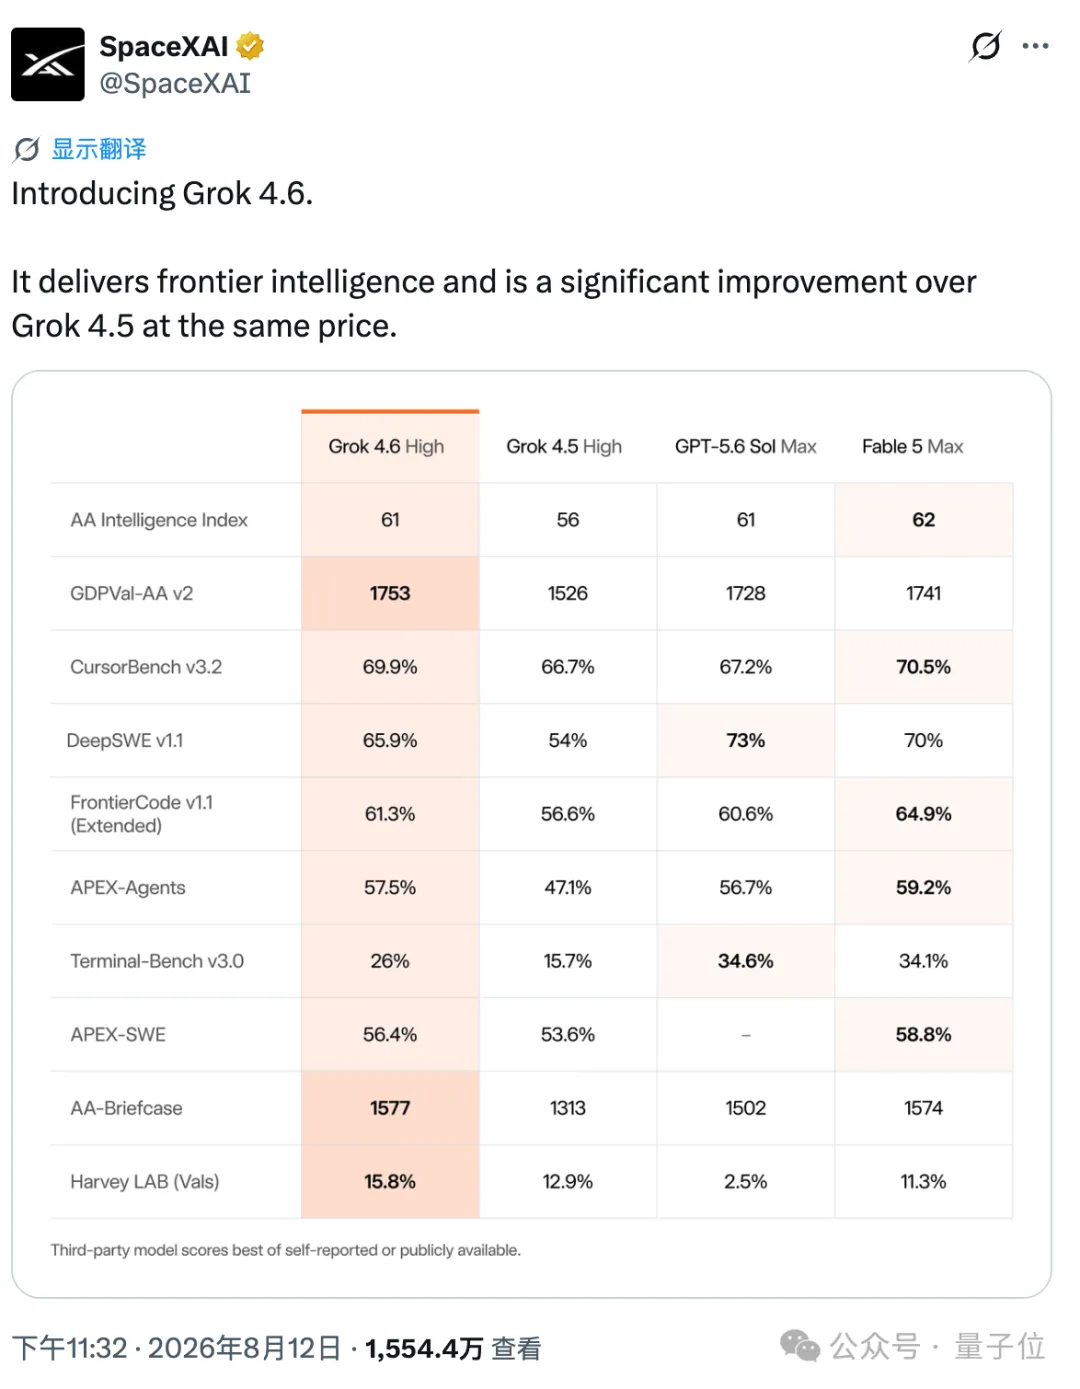
xAI and SpaceXAI release Grok 4.6, matching GPT-5.6 Sol on AI Index
xAI and SpaceXAI released Grok 4.6, a frontier model focused on long-running agents, available in Cursor, Grok Build, Grok Bot, and API. It scores 61 on the Artificial Analysis Intelligence Index, matching GPT-5.6 Sol, and tops GDPVal-AA v2 with 1753 points, priced at $2/1M input and $6/1M output tokens.
3 reports · 3 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe