Shanghai AI Lab and partners release Sage S2.1 Flash technical report, 320B MoE model tops four agent benchmarks
Shanghai AI Laboratory, together with Fudan University, CAS Institute of Software, Renmin University, and other institutions, released the technical report for Sage S2.1 Flash, a 320B-parameter mixture-of-experts model. The model achieves state-of-the-art results on four agent benchmarks and integrates unified scientific multimodal perception, enabling tasks such as reconstructing 3D bone models from CT images via tool use. The report details the full training pipeline and architecture, including a scientific perception module for molecular and spectral data.
Coverage timeline
机器之心机器之心
只需一个指令,Agent 就能从 12,487 张 CT 图像中,重建一个三维骨骼模型? Sage S2.1 Flash 做到了,它的答案是找出属于目标扫描序列的切片,整理好,再操作医学影像软件 3D Slicer,重建立体可见的骨骼模型。 近日, 上海人工智能实验室联合复旦大学、中国科学院软件研究所、中国人民大学、中国科学院自动化研究所、华东师范大学、哈尔滨工业大学、北京大学等多家科研机构与高校 ,正式发布 Sage S2.1 Flash 技术报告。报告系统披露了这一总参数量达 320B 的混合专家(Mixture-of-Experts,MoE) 模型的完整训练流程与技术细节,读懂分子和光谱、接连调用工具、在专业软件中交付作品,这几项本领如今集中在了同一个模型身上。 论文:https://arxiv.org/abs/2611.21072 项目主页:https://internlm.github.io/Sage-S2.1-Flash/ Hugging Face:https://huggingface.co/papers/2611.21072 Github :https://github.com/InternLM/Sage-S2.1-Flash 上线首周,好评不断 上线首周,Sage S2.1 Flash 在真实用户的实际使用中收获了不少积极反馈,多名体验者评价模型 “快且聪明”,在多轮任务测试中感受到流畅的工具调用体验;在更贴近实际开发的场景中,模型也能承担完整的任务执行;在” 鹈鹕测试” 中,模型生成的画面也获得了体验者的大力肯定。 统一科学多模态架构 让模型直接理解科学数据 Sage S2.1 Flash 采用 320B 混合专家(MoE)架构 ,通过动态专家路由控制推理计算量,并结合稀疏注意力与线性注意力支持长上下文处理。模型主干能够在共享上下文中处理文本、图像和科学数据表示,为复杂推理与多步骤任务执行提供基础。 这一通用模型主干为科学数据理解、代码执行、复杂检索和专业软件操作提供了共享的推理能力,也为进一步接入科学专用模态奠定了架构基础。 Sage Sci-Perception:将结构化科学数据接入通用语言模型 针对分子、蛋白质、核酸及光谱等科学数据,研究团队设计了 Sage Sci-Perception 科学多模态感知模块 ,采用 MoleculeSTM(
Related stories
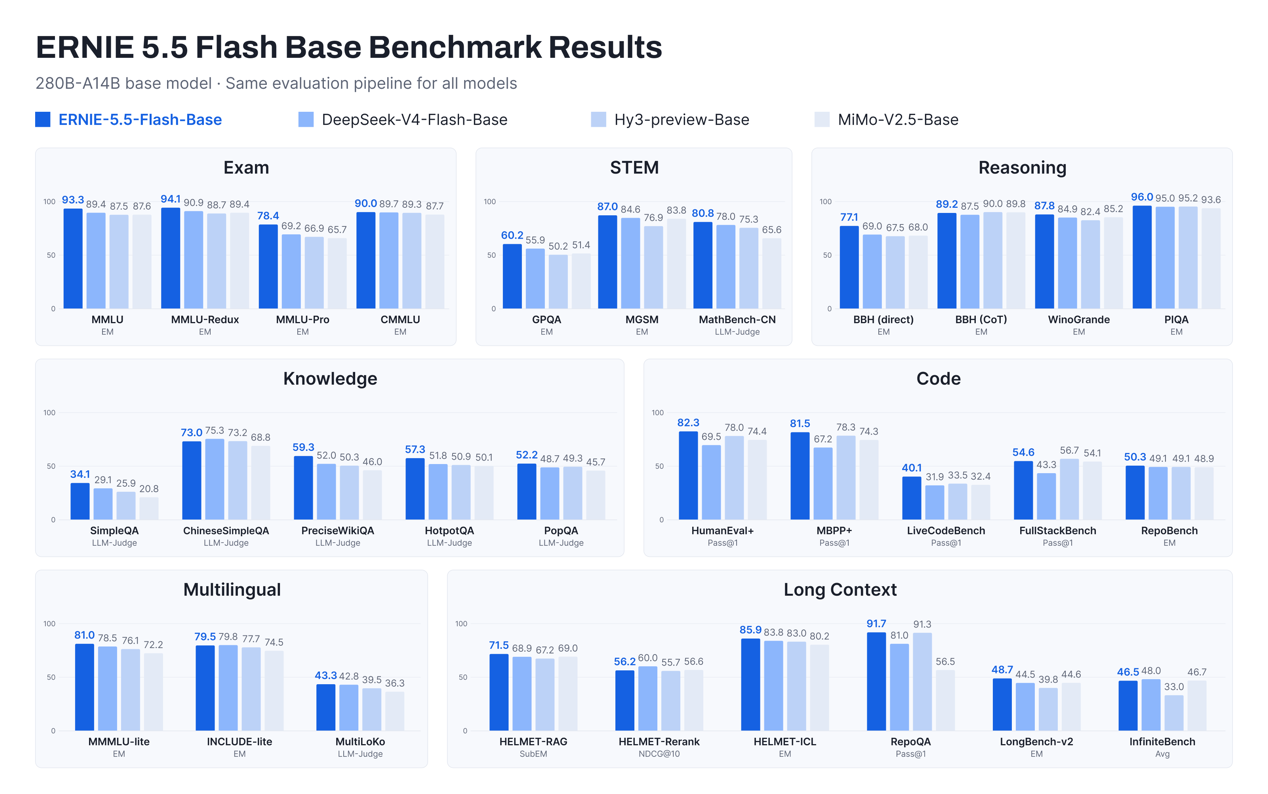
Baidu open-sources ERNIE 5.5 Flash Base, 280B MoE model with 14B active parameters
On November 5, Baidu open-sourced ERNIE 5.5 Flash Base, a sparse MoE language model with 280B total parameters and 14B active per token, pretrained on 33.5T tokens with up to 128K training context and 1M-token context for fine-tuning and inference. The company claims SOTA results among same-size models on benchmarks covering knowledge, reasoning, math, code, multilingual, and long-context tasks, surpassing DeepSeek-V4-Flash-Base, Hy3-preview-Base, and MiMo-V2.5-Base. The release includes weights on Hugging Face and ecosystem support with vLLM and SGLang.
3 reports · 2 sources
DSpine parallel speculative decoding achieves up to 4x SGLang throughput, open-sourced
Researchers from Tencent Youtu Lab, Shanghai Jiao Tong University, and Xiamen University released DSpine, a parallel speculative decoding method that injects forming prediction features from predecessor positions into successors at each layer of the draft network, then uses a transition cache for conditional correction. The method achieves up to 4x SGLang throughput and is open-sourced, addressing the suffix decay problem in parallel drafting.
1 reports · 1 sources
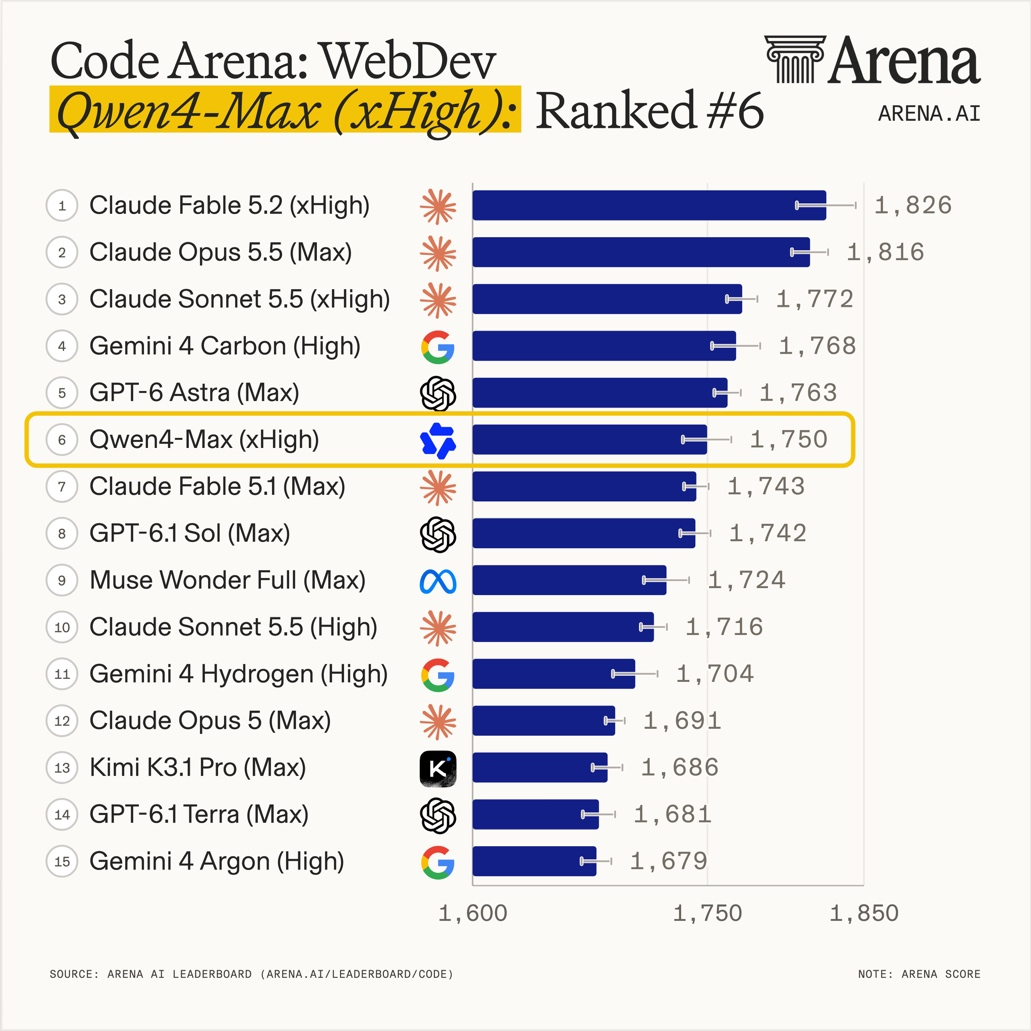
Alibaba launches Qwen4-Max, a 2.4T-parameter MoE model with 1M context
Alibaba released Qwen4-Max, a new flagship 2.4T-parameter mixture-of-experts model with native vision and a 1M-token context window, available via API on the Qwen AI platform. The company claims it outperforms Qwen3.8-Max with up to ~50% fewer tokens per task and lower costs, while smaller open-weight versions are planned. Independent benchmarks show it scores 43 on the Artificial Analysis Intelligence Index, trailing Kimi K3.1 Pro but at lower cost per task.
Chinese AI startups HyperVolve and Apexin announce funding and model releases
Chinese AI startup HyperVolve announced tens of millions RMB in angel funding led by Lanchi Ventures, with participation from SenseTime Guoxiang Capital, Lenovo Star, Inno Fund, and Tsinghua alumni seed fund, to build research foundation models using recursive self-improvement. Separately, Apexin, founded by 27-year-old Tsinghua assistant professor Chen Yongchao, released Apex-35B-V1.0, a 35B model claiming SOTA results on 21 benchmarks against comparable models.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe