ScholarEvolve lets AI agents read papers and self-modify code
Researchers from UCSB and Microsoft propose ScholarEvolve, a method that automates the research process for AI agents: reading academic papers, implementing algorithms, and evaluating results to evolve their agent harness without modifying underlying model parameters. The approach addresses the limitation of prior auto-optimization methods that rely solely on the agent's existing knowledge and observed failures, enabling exploration of novel improvements from latest research.
Coverage timeline
机器之心机器之心
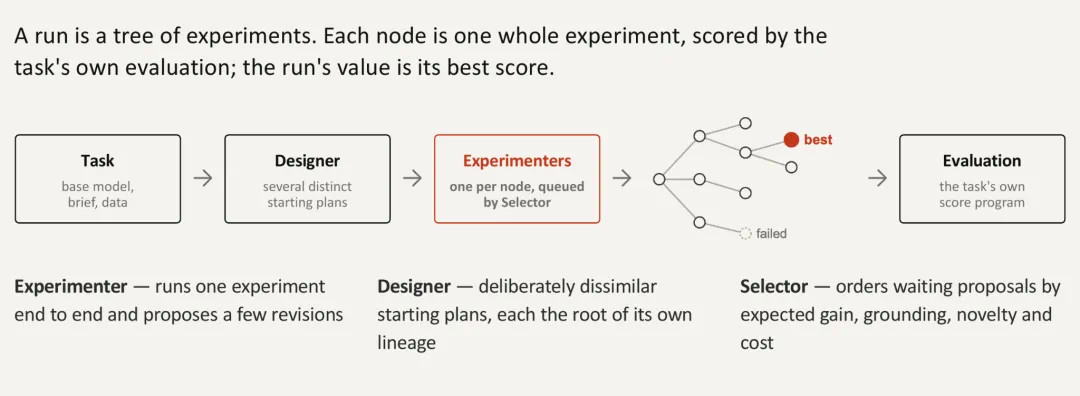
AI Agent 能否像研究人员一样,从论文中学习? 最近两年,大语言模型的能力不断提升,围绕模型构建的 AI Agent 也逐渐能够处理复杂的任务。从调用工具、操作软件,到规划和执行多步骤工作流,Agent 从处理简单的问答,走向能够独立解决长程复杂工具调用的任务。与此同时,每天也都有很多新的 agent 领域的 preprint 公开在 arXiv 中。 但一个现实问题随之出现: 当 Agent 遇到能力瓶颈时,我们该如何让它变得更好? 最直接的办法是训练更强的模型。然而,Agent 的表现并不完全取决于底层模型。工具如何调用、上下文如何管理、经验如何复用,以及任务如何规划,都会影响最终的执行效果。 这些围绕模型运行的软件系统,通常被称为 Agent Harness 。 近期,Meta Harness 等研究开始探索自动优化 Harness:让一个 Coding Agent 分析任务执行中的失败,再尝试修改 Harness 的代码,并通过实验寻找更好的版本。 这种方式已经展现出一定潜力,但也存在一个明显的局限:Coding Agent 提出的改进,很大程度上依赖于自身 Backbone 模型已有的知识,以及此前观察到的失败案例。如果一个问题还没出现,或者模型本身不知道某种更好的解决方法,它就很难主动探索相应的改进方向。 人类研究人员面对类似问题时,通常会阅读最新论文,了解其他研究者提出的方法,再尝试将这些方法应用到自己的系统中。那么,能否让 Agent 也具备这样的能力? 近日,来自 UCSB 和微软的研究团队提出了 ScholarEvolve ,尝试将阅读研究文献、实现算法、评估效果这一研究过程自动化,让最新的学术成果能够直接参与 Agent Harness 的演化。 论文: Learning from Research: Toward Lifelong Agent Harness Evolution 论文地址: https://arxiv.org/abs/2609.40169 代码地址: https://github.com/UCSB-NLP-Chang/ScholarEvolve 研究机构: 加州大学圣塔芭芭拉分校(UCSB)、微软 在不修改底层模型参数的情况下,ScholarEvolve 将 Qwen3.5-27B 在 AppWorld Challeng
Related stories
RSIGame framework lets AI agents self-improve in game development, beating one-shot GPT-5.5 output
Researchers from UC San Diego, ByteDance, and CMU propose RSIGame, an agentic framework that turns game development into a recursive self-improvement process, where agents playtest, diagnose, fix, and validate games iteratively. Experiments show RSIGame improves game quality scores from 50.26 to 64 starting from GPT-5.5-generated games, and accumulated experience can further train the underlying model.
1 reports · 1 sources
AIBuildAI open-sources PostTrain Agent, tops PostTrainBench with 46.6 points
AIBuildAI released PostTrain Agent, an open-source recursive self-improving agent that autonomously performs LLM post-training, including algorithm design, data collection, coding, and experiments, without human intervention. On the PostTrainBench benchmark, it scored 46.6, ranking first among frontier models and agent systems, close to human expert performance (51.1). The team also open-sourced the code, knowledge base, and technical report.
Google Researchers Propose RRSI to Curb Overfitting in Recursive Self-Improving Agents
Google researchers have introduced RRSI (Regularized Recursive Self-Improvement), a method that adds regularization to recursive self-improving agents to prevent overfitting. The approach targets harness evolution, where agents iteratively modify their own prompts, tool usage, and memory management based on a fixed set of tasks, which can lead to benchmark-specific fitting and evaluation noise chasing. The paper, code, and project page are available online.
Apple and CMU propose SSR framework cutting multimodal search agent inference latency by over 90%
Researchers from Apple and Carnegie Mellon University propose SSR (Selection-based Structured Reasoning), a framework that replaces free-form token-by-token reasoning with selection from predefined reasoning options in multimodal search agents. In experiments across 7 multimodal search benchmarks, SSR reduces per-step inference latency by over 90% while maintaining task success rates comparable to free-form thinking.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe