Inception Labs' Mercury 3 diffusion LLM outruns GPT-6 Luna and Claude Haiku 5.5 in benchmarks
Inception Labs, co-founded by Stanford professor Stefano Ermon, released Mercury 3, a diffusion-based LLM that reportedly achieves faster generation and higher benchmark scores than GPT-6 Luna and Claude Haiku 5.5. The model outputs 1068 tokens per second, up to 8x faster than GPT-6 Luna, with a price of $0.35 per million output tokens and a 1 million token context window.
Coverage timeline
机器之心机器之心
编辑|Neo GPT-6 Luna 要被扩散 LLM 抢饭碗了? 新发布的 Mercury 3 模型规模扩大了 40 多倍,生成速度却依然快得惊人, 每百万输出 Token 的价格更是低至 0.35 美元 。昔日主打速度的扩散模型,如今开始正面挑战主流大模型。 10 月 19 日,由斯坦福大学教授 Stefano Ermon 联合创办的 Inception Labs,拿出了一份颇具冲击力的成绩单:Mercury 3 在官方公布的多项基准测试中超过 GPT-6 Luna 和 Claude Haiku 5.5,输出速度达到每秒 1068 Token, 最高比 GPT-6 Luna 快约 8 倍 。 事实上,第一代 Mercury 就已经实现了每秒千 Token 级的生成速度。 这次真正令人关注的是,当模型规模扩大 40 多倍、能力大幅提升之后,Mercury 3 依然保持了这一速度。 扩散 LLM 要证明的,已经从「我能跑得快」,变成了「我做大、做聪明之后,仍然能跑得快」。 扩散 LLM 开始与 GPT、Claude 拼能力 先看 Inception 给出的成绩单。 在官方披露的同档位对比中,Mercury 3 在 GPQA Diamond 上取得 89.23 分,高于 GPT-6 Luna 的 86.36 分和 Claude Haiku 5.5 的 84.51 分。这个测试考查的是研究生水平的专业科学知识和推理能力,换成更贴近实际开发的任务,差距更加显眼:SWE-Bench Atlas 上,Mercury 3 得分 51.08,对比两款模型的 33.33 和 32.26。指令遵循测试 IFBench 中,Mercury 3 也取得 76.84 分。 也就是说,Inception 这次并不是拿一个只能快速输出简单答案的模型,去跟主流 LLM 比速度。它展示的是,扩散路线也可以处理知识问答、复杂指令和真实软件工程任务。 再看速度:Mercury 3 在 NVIDIA GPU 上的输出吞吐达到 1068 Token/s;Inception 给出的 GPT-6 Luna 与 Haiku 5.5 对应速度分别约为每秒 130 和 240 Token。 能力和速度之外,还有两组数字值得留意。Mercury 3 的上下文窗口扩大到了 100 万 Token,上一代 Mercury
Related stories
Inception launches Mercury 3, diffusion LLM claiming ~1,000 tokens/sec
Inception has launched Mercury 3, a diffusion-based large language model that the company claims is comparable to Luna and Haiku models while being 4x to 8x faster, generating approximately 1,000 tokens per second. The announcement was reported by Techmeme and Hacker News on October 19-20, 2026.
2 reports · 2 sources256 points · 92 comments
Anthropic launches Claude Haiku 5.5 with effort controls, 90% price cut
Anthropic released Claude Haiku 5.5, its cheapest and fastest small model, priced at $0.10 per million input tokens and $0.50 per million output tokens for requests up to 100K tokens, a 90% cut from Haiku 4.5. It is the first Haiku model with adjustable reasoning effort, and benchmarks show it outperforming GPT-6 Luna on several tests, including OSWorld 2.1 and GDPval-AA v2.1.
6 reports · 5 sources1045 points · 487 comments
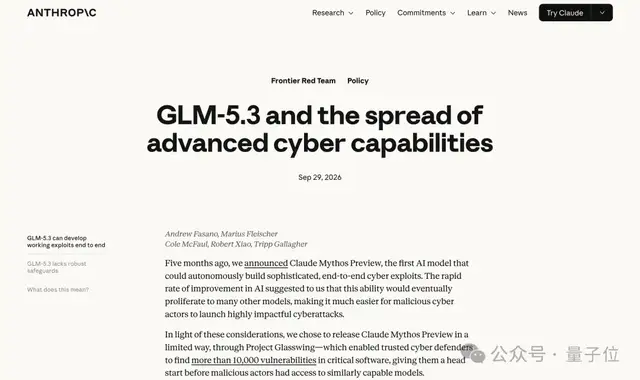
Anthropic warns GLM-5.3 matches Claude Mythos in cyber exploits, lacks safeguards
Anthropic's Frontier Red Team published a report stating that Zhipu's GLM-5.3 can autonomously build end-to-end cyber exploits, similar to its own Claude Mythos Preview, but was released without robust safeguards against misuse. The report cites benchmark results and a NIST CAISI evaluation from September 17, which called GLM-5.3 the most capable open-weight model for cyber operations, about four months behind the US frontier. Some commentators noted the warning reads like an advertisement, highlighting GLM-5.3's strong performance.
3 reports · 3 sources251 points · 234 comments
Anthropic releases Sonnet 5.5, 30% faster and up to 30% cheaper than Sonnet 5
Anthropic has released Claude Sonnet 5.5, a mid-range model that runs 30% faster and costs up to 30% less per task compared to Sonnet 5, while matching or exceeding its predecessor on benchmarks. The model is now available on all major platforms, including AWS, Google Cloud, and Azure, and powers the free tier of claude.ai. Haiku 5.5 is planned for release in the coming weeks.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe