vLLM Announces vllm-metal for Apple Silicon with Concurrent Serving
vLLM announced vllm-metal, bringing its paged, continuously batched serving stack to Apple Silicon. The new offering features flatter time-to-first-token under concurrent agent load, batched multi-token prediction, and automatic M5 prefill acceleration.
Coverage timeline
vLLM BlogRanran Haoran Zhang, Lik Xun Yuan, Chao Ju Chen, Eric Curtin, Michael Goin
vllm-metal brings vLLM's paged, continuously batched serving stack to Apple Silicon, with flatter TTFT under concurrent agent load, batched MTP, and automatic M5 prefill acceleration.
Related stories
vLLM Adds Day-0 Support for NVIDIA Vera Rubin NVL72, Claims 7.8x Throughput over GB200
vLLM announced support for NVIDIA Vera Rubin NVL72, claiming 7.8x throughput over GB200 NVL72. The platform offers daily container builds and day-0 model support for DeepSeek, Moonshot AI, Z.ai, and MiniMax, leveraging Blackwell kernel compatibility and Rubin-tuned kernels via FlashInfer 0.7.0.
vLLM-Omni and FastVideo Optimize MiniMax H3 Serving, Generate MP4 in 8.7s on Eight B300 GPUs
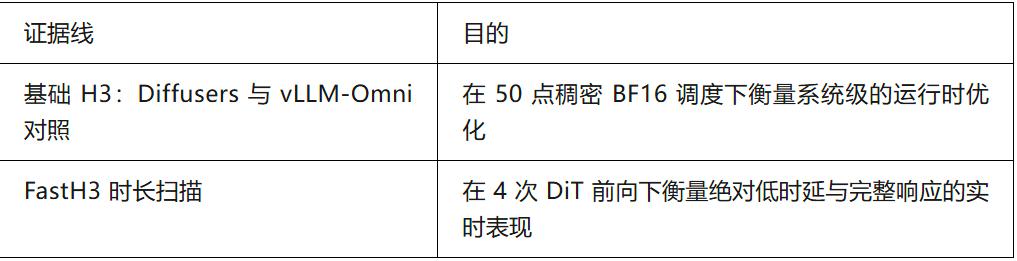
A technical post from vLLM-Omni and FastVideo describes system-level optimizations for serving MiniMax H3, a multimodal model that generates video with synchronized audio. The optimizations span the full resident pipeline, including attention and communication, fused DiT operators, parallel VAE decoding, compact output transfer, and parallel MP4 construction. FastVideo's FastH3 reduces 49 DiT forward passes to 4, achieving real-time full MP4 generation in 8.678–8.710 seconds on eight B300 GPUs for a 10.125-second clip.
2 reports · 2 sources
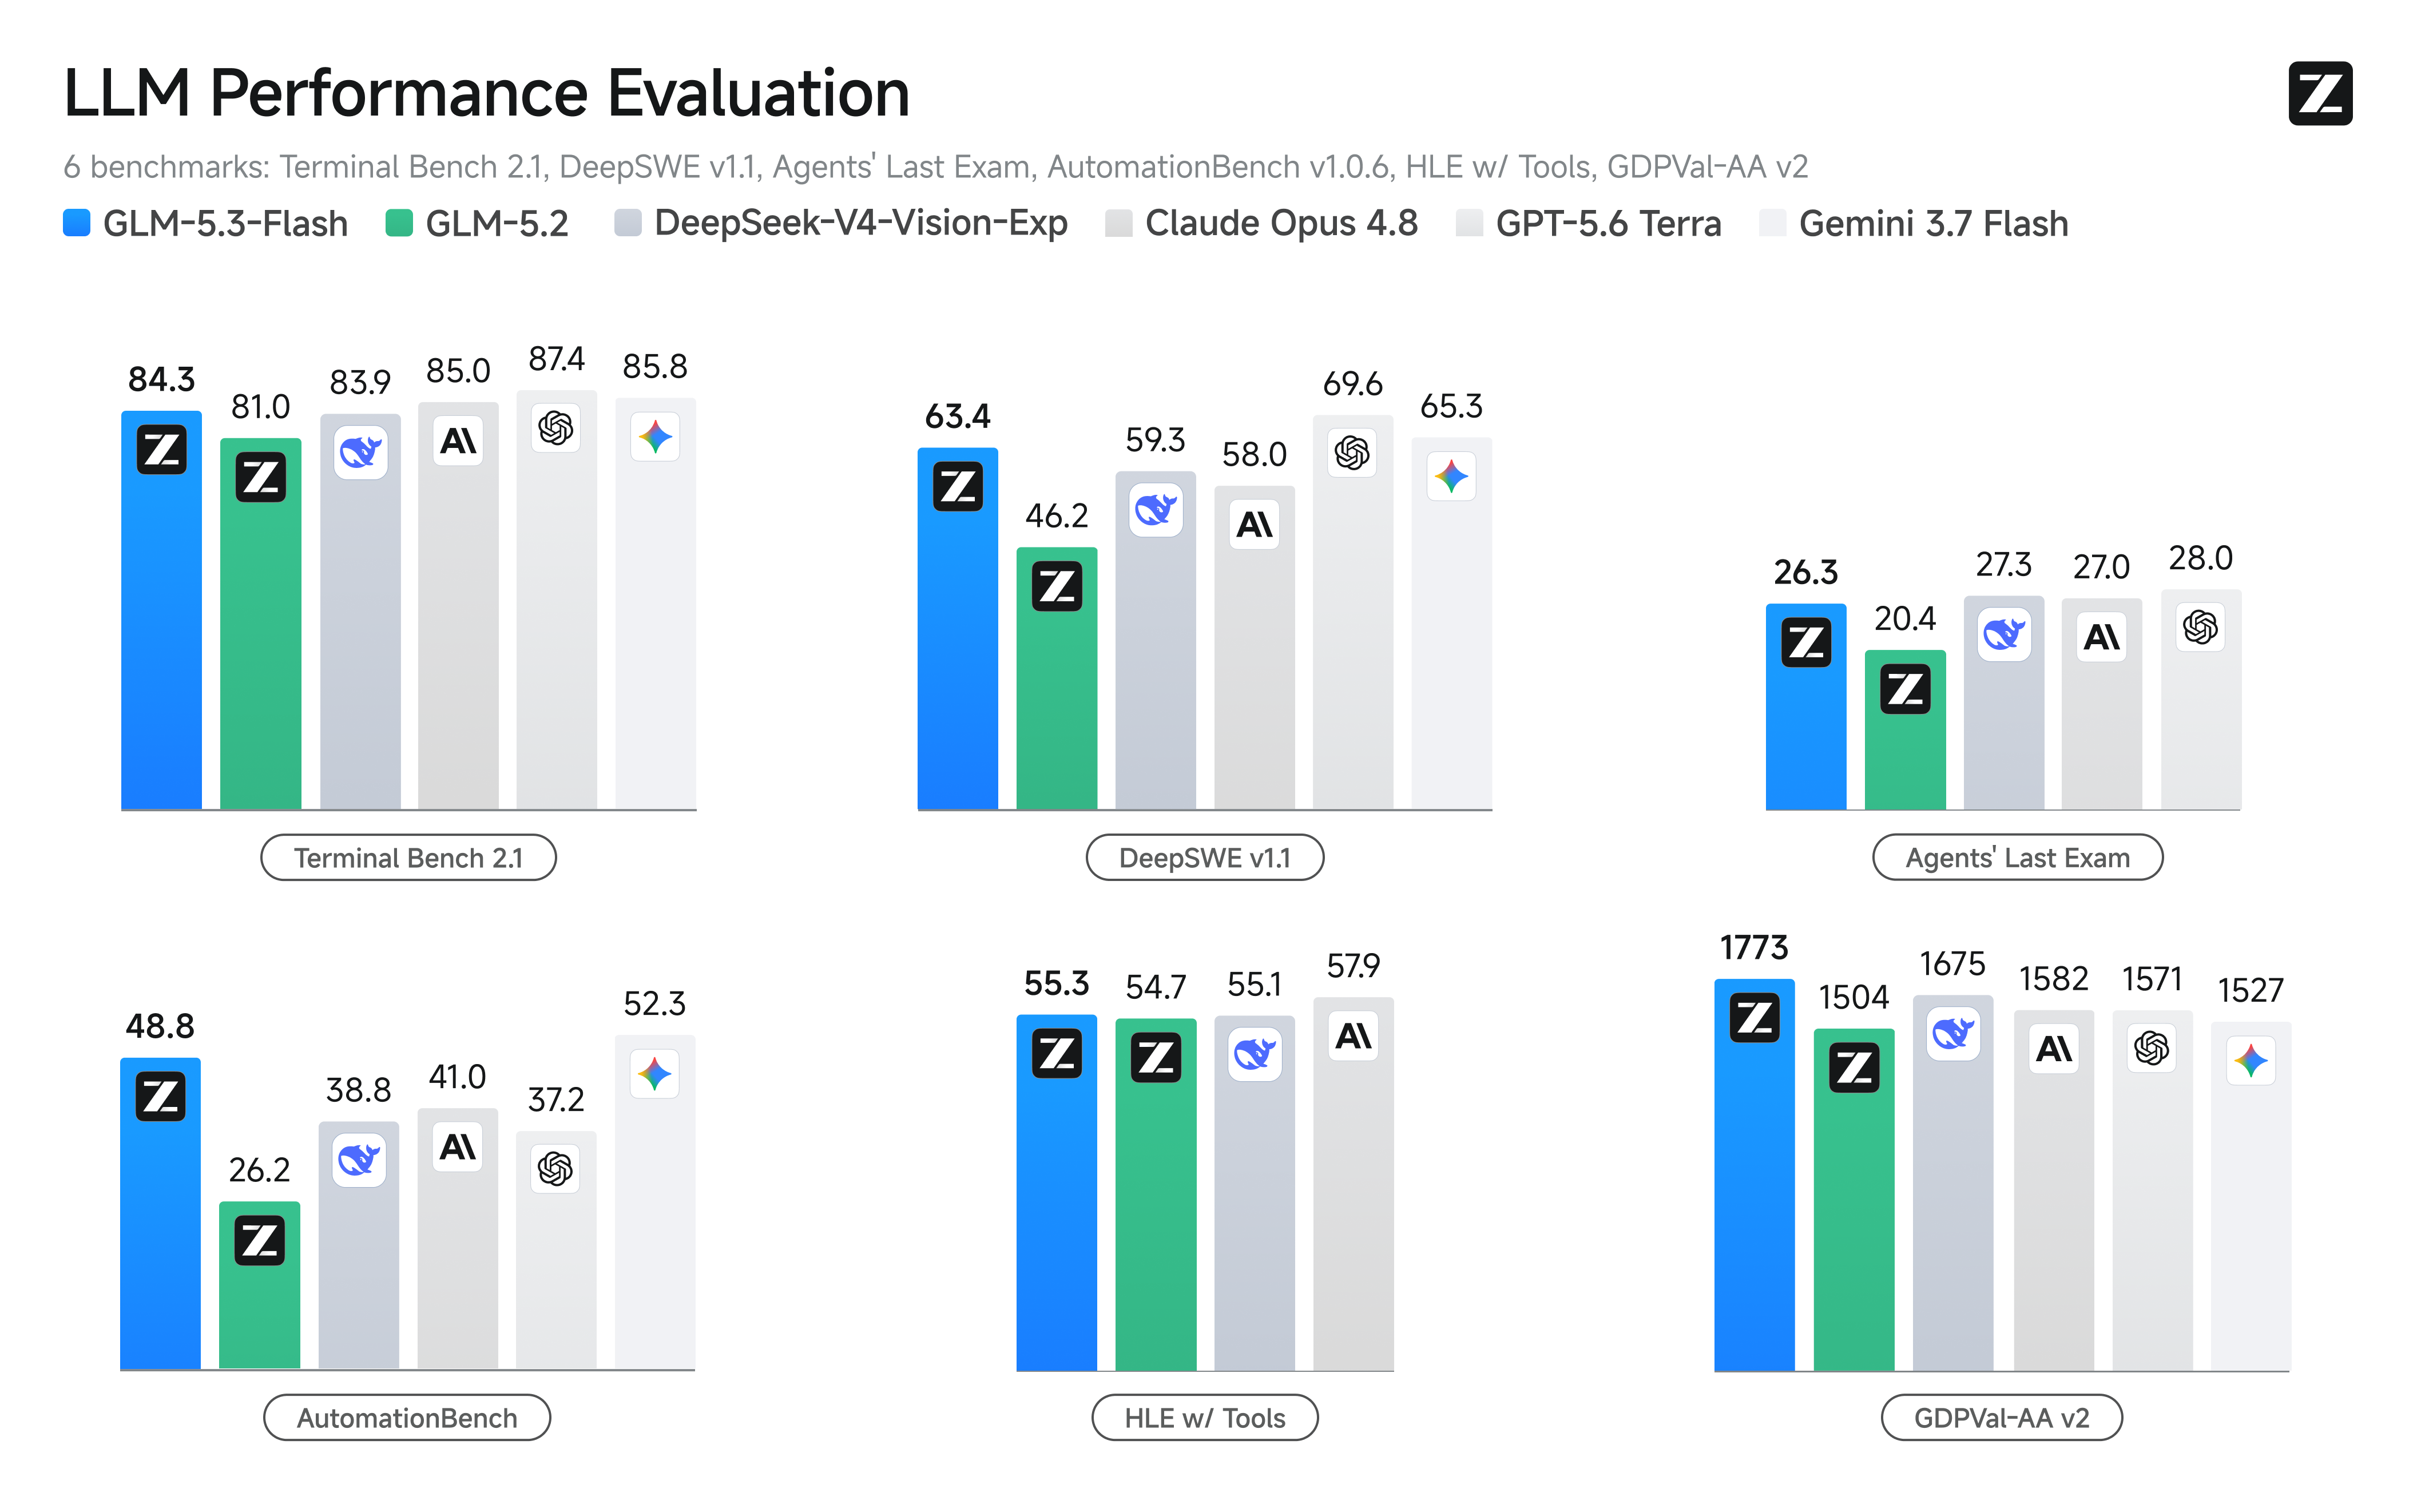
Zhipu AI open-sources GLM-5.3-Flash, a 320B multimodal model priced at 1/40 of Claude Opus 4.8
Zhipu AI released and open-sourced GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series, with 320B total parameters (18B active). It scores 57 on the Artificial Analysis Intelligence Index, matching Claude Opus 4.8, and is priced at one-tenth of GLM-5.3, or one-fortieth of Opus 4.8. The model uses a hybrid sparse and linear attention architecture, runs on domestic Chinese chips, and was tested anonymously as Ox-Alpha on OpenRouter and OpenCode.
8 reports · 5 sources1126 points · 573 comments
vLLM Adds Tenstorrent Plugin for Mesh-Optimized LLM Serving
vLLM announced an out-of-tree platform plugin enabling LLM serving on Tenstorrent accelerators, with optimizations tailored to the mesh architecture. Key features include phase-based scheduling, single-process data parallelism on Galaxy systems, on-device sampling with host fallback, and asynchronous decode overlap.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe