Tencent Hunyuan analyzes batch size impact on scaling RL training at 10K-100K GPU clusters
Tencent Hunyuan's team published a technical analysis on scaling reinforcement learning (RL) training for clusters of 10,000 to 100,000 GPUs, focusing on batch size tuning and scaling. They found that moderately increasing batch size with adjusted learning rates improves throughput, but at 16B batch size the additional sample cost outweighs the gains, slowing time-to-target.
Coverage timeline
机器之心机器之心
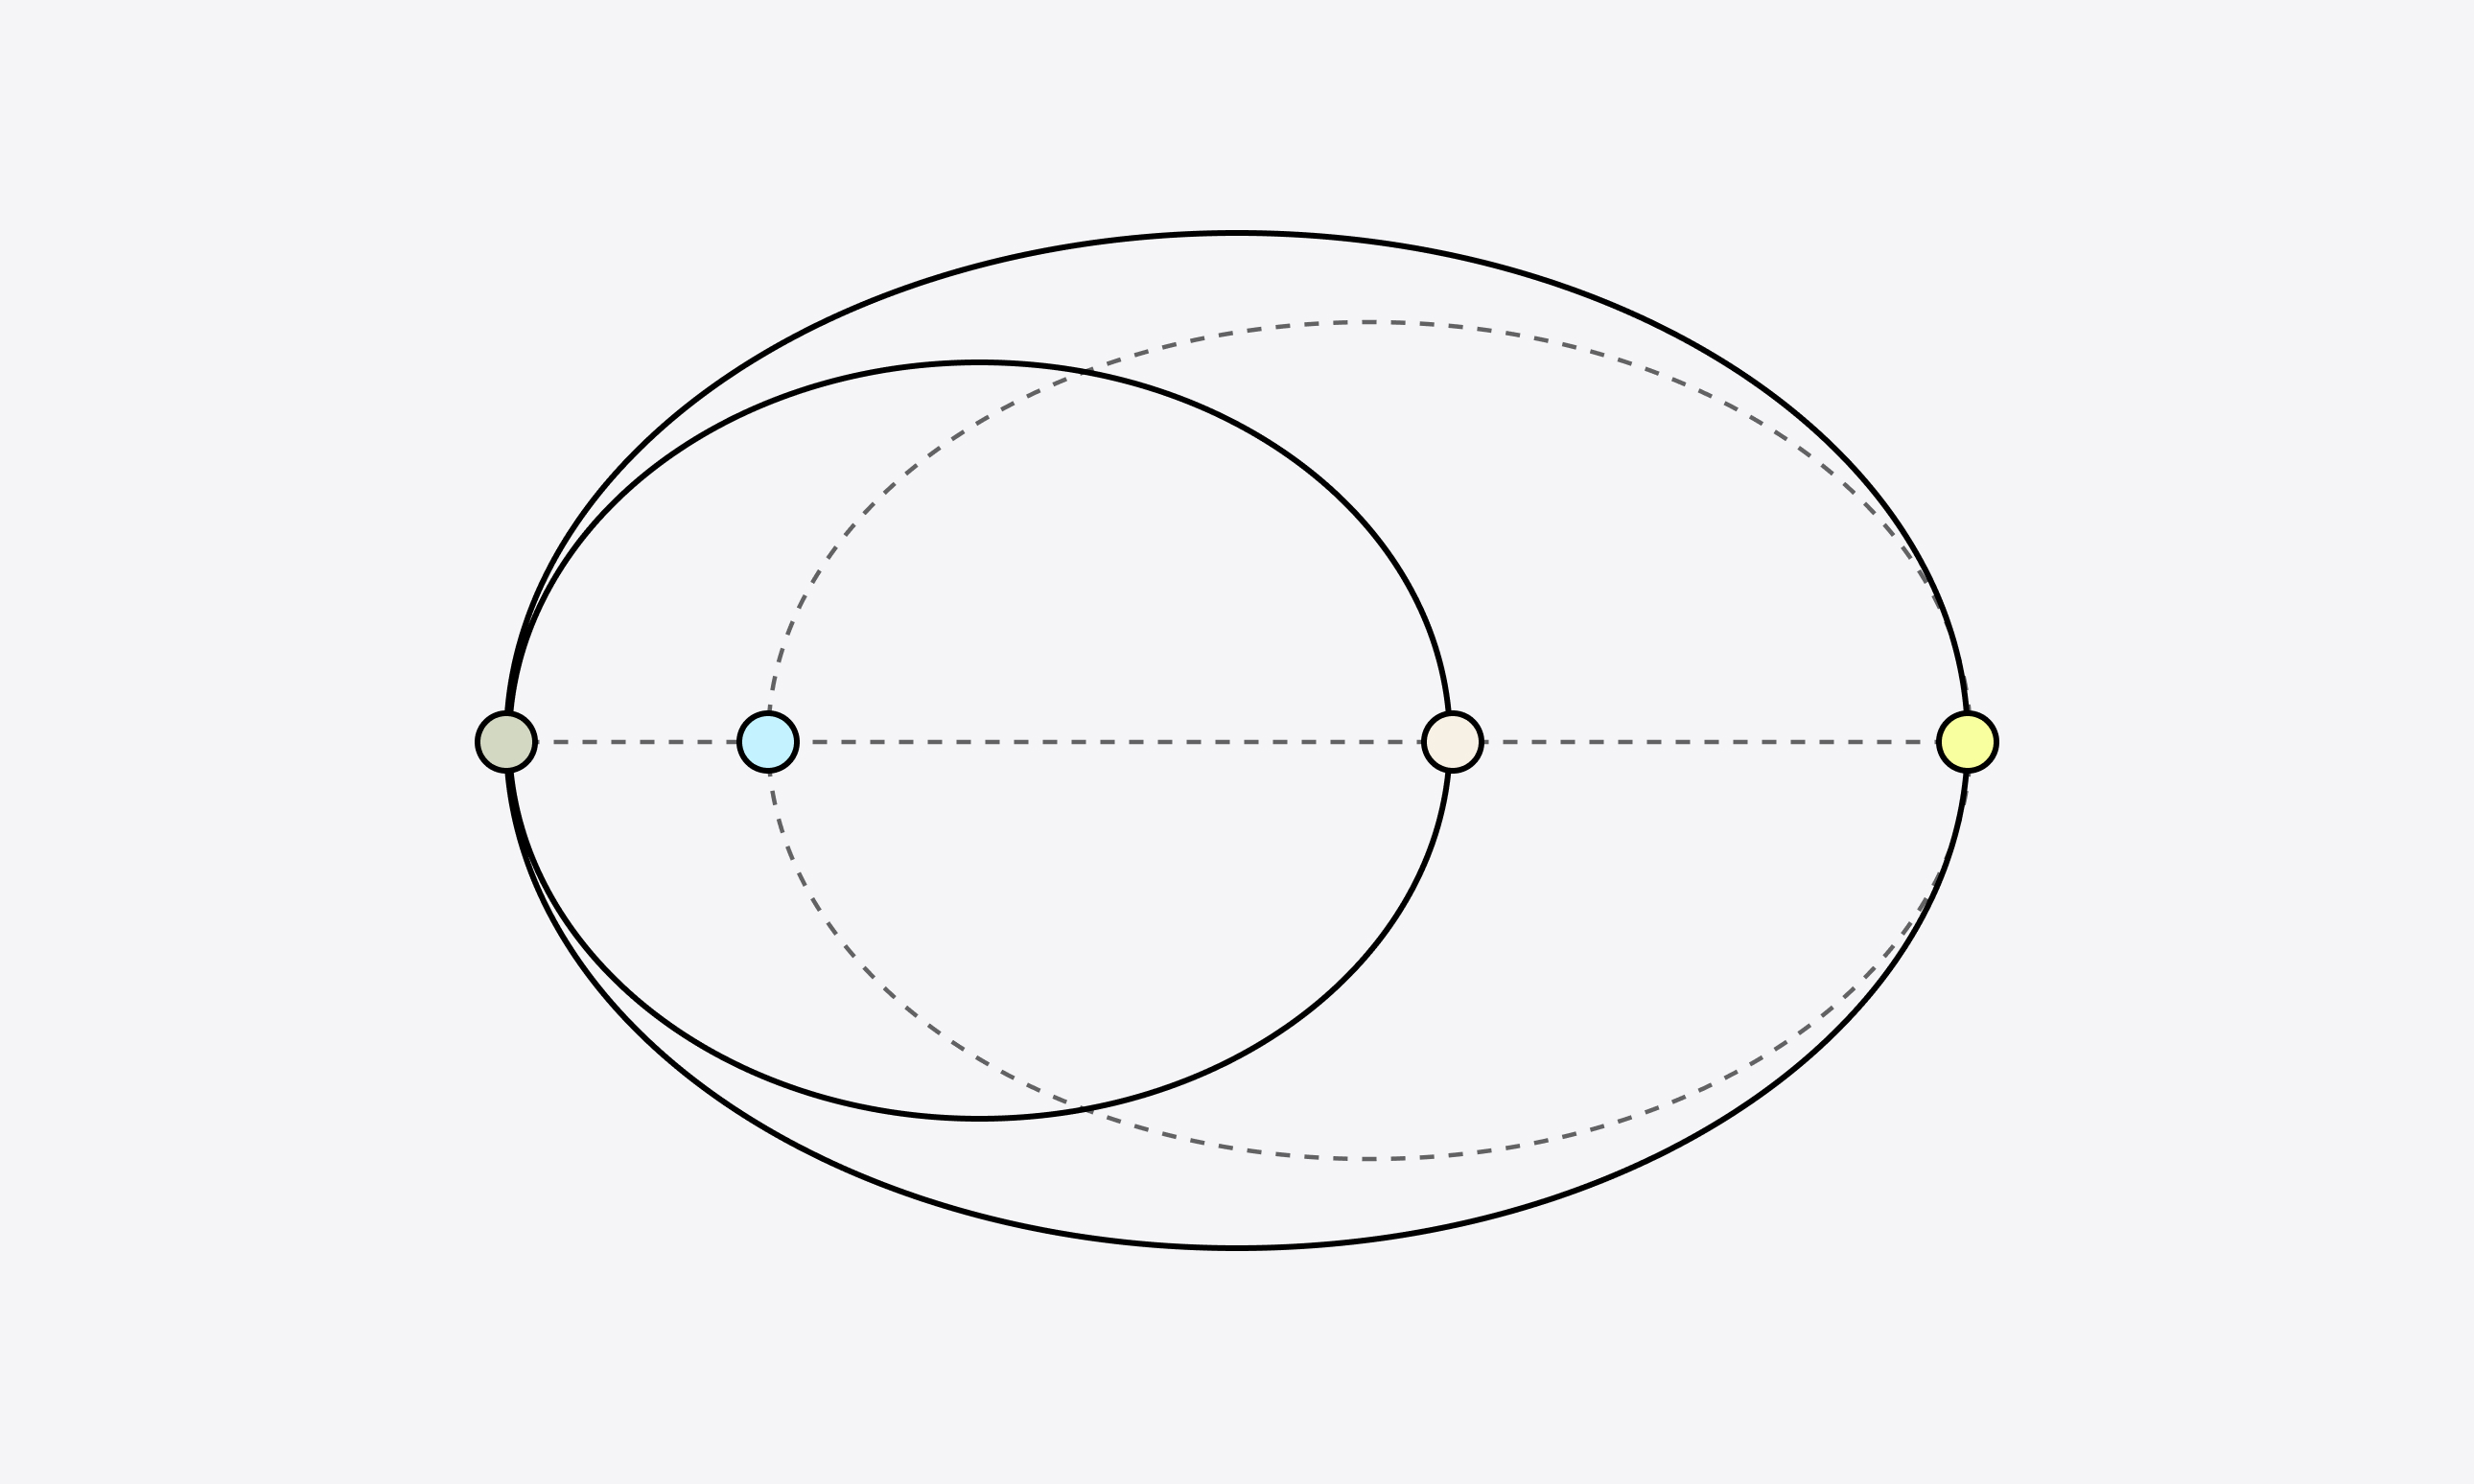
强化学习走向规模化,效率成为关键变量 当预训练将大模型带到新的能力起点,强化学习则通过持续的探索与反馈,不断激发模型在新环境、新任务中的推理与行动能力,决定它们还能走多远。 RL 在模型开发中占的比重越大,训练效率对算力预算的影响也越直接。 算一笔示意账:假设 1 万张 GPU 连续运行 30 天,按每卡每小时 3 美元计算,总费用是 2,160 万美元。如果使用同样的卡数、达到同样的模型效果,但将训练时间缩短 10%,就能少使用 72 万 GPU 小时,按上述假设节省约 216 万美元。对租用集群的团队,这是直接减少的账单;对自建集群的团队,则意味着能更早把这些算力交给下一轮实验。 这些效率收益可以从哪里找?一个最基础、也几乎所有训练配方都无法绕开的参数,就是 Batch Size 。 在实际训练中,Batch Size 常常出现在两类决策中: Batch Size Tuning :让配方适配新条件。 模型变大了,或 GPU 卡型变了,原来的 Batch 和学习率不一定还合适。Batch 太小可能让硬件利用不充分,与之不匹配的学习率则可能让学习变慢甚至不稳定。这时需要找到一组能稳定学习、又能高效使用当前硬件的 Batch 与配套超参数。 Batch Size Scaling :把并行度变成更短的训练时间。 如果同一个模型得到了更多 GPU,Batch 能否同步扩大,让模型更早达标?即使 GPU 数量不变,如果生成并发较低、设备还没有充分工作,能否通过更大 Batch 利用这部分闲置能力? 两类决策最终都指向同一个实际问题: 如何找到最优的 Batch Size,使模型以最短的 wall-clock time 达到预期性能? 更大的 Batch,既可能是加速器,也可能成为减速带。腾讯混元团队在实验中观察到:适度增大 Batch,并同步调整学习率,可以在保持学习效率的同时提高吞吐;但 Batch 过大时,额外样本代价会反过来压过吞吐收益。图 1 把这种反差画成登山:有的路线能更快抵达同一性能「山顶」,有的看似步子更大,登顶反而更慢。 图 1|把训练比作登山:山顶代表达到同一目标性能,四条路线代表不同的 Batch Size,每个路标代表一次优化更新。配套调整学习率后,B、2B 和 4B 在累计样本维度上保持近似相同的学习进度;其中更大的 Batch 因吞吐更高而更快「
腾讯混元 BlogRL Team
!12 Figure 1. Think of training as climbing toward the same capability target. The summit is the shared validation target, each route is a different batch size, and each marker is one optimizer update. After learning-rate retuning, B, 2B, and 4B make similar progress per response, while higher throughput lets the larger batches reach the summit sooner. At 16B, however, the additional sample cost outweighs the throughput gain, so the apparently larger step becomes a slower route. The legend reports normalized time-to-target.! Introduction Pretraining gives large language models a new capability baseline; reinforcement learning determines how far they can continue to advance by learning through exploration and feedback in new environments and tasks. DeepSeek-R1 helped demonstrate how large-scale RL can develop strong reasoning capabilities with little labeled data.[^r1] With Grok 4, xAI pushed the computational scale further: it reported using Colossus, its 200,000-GPU cluster, to run re
Related stories
HKUST and Huawei propose BalanceRoute to cut MoE LLM serving load-balancing bottleneck
Researchers from HKUST and Huawei's 2012 Lab propose BalanceRoute, an online routing method that models synchronous waiting in MoE LLM serving and converts short-term load prediction into routing decisions. In a 96-GPU test, the predictor-based variant BR-H improves decode throughput by about 15% over the strongest baseline. The work is accepted by NeurIPS 2026 and deployed in the jointly built MaaS system MathBot-Pie.
1 reports · 1 sources
Janas Tool Runs LLMs Larger Than RAM by Streaming Experts from SSD
A Hacker News post introduces Janas, a tool that enables running large language models (LLMs) larger than available RAM by streaming expert modules from SSD storage. This approach allows users to execute models that exceed memory capacity, potentially expanding the range of models deployable on standard hardware.
1 reports · 1 sources220 points · 94 comments
Tsinghua team's MGFlow and Elastic Forcing achieve SOTA one-step image generation and efficient 14B video model post-training
Researchers at Tsinghua University and collaborators introduced distributional training, a method that supervises generation by comparing the overall distribution of generated samples with reference samples rather than assigning unique answers per sample. Their MGFlow method achieved state-of-the-art one-step generation on ImageNet 256×256 (pMF-H, JiT-H: 1.45, 1.64 FID) and outperformed the original 4-step FLUX.2 [klein] 4B model in text-to-image (GenEval 0.900, PickScore 21.98). Elastic Forcing, the video counterpart, scored 84.64 on VBench, surpassing Self Forcing, and post-trained a 14B streaming video model on 8 H200 GPUs in 23.2 hours.

Ai2 details GPU scheduler using time budgets and fair-share allocation
Ai2 published a blog post explaining its new GPU scheduler design, which uses time budgets, fair-share allocation, and time-slicing to prioritize high-impact research. The scheduler aims to shorten queue waits and keep GPUs busy. Hugging Face also posted on the same topic, highlighting impactful scheduling strategies for GPU clusters.
2 reports · 2 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe