vLLM Serves DeepSeek-V4.1-Flash at 954K Tokens/s per GPU on GB300 NVL72
vLLM's blog reports that using P/D disaggregation and Wide-EP on a GB300 NVL72 rack, it serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU, matching DeepInfer's performance. This result is 7.9x the aggregated single-node result, demonstrating significant scaling.
Coverage timeline
vLLM BlogInferact and the vLLM Team
With P/D disaggregation and Wide-EP on a GB300 NVL72 rack, vLLM serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU at a P90 of 196 tokens/s per user, 7.9x our aggregated single-node result.
Related stories
vLLM Adds Day-0 Support for NVIDIA Vera Rubin NVL72, Claims 7.8x Throughput over GB200
vLLM announced support for NVIDIA Vera Rubin NVL72, claiming 7.8x throughput over GB200 NVL72. The platform offers daily container builds and day-0 model support for DeepSeek, Moonshot AI, Z.ai, and MiniMax, leveraging Blackwell kernel compatibility and Rubin-tuned kernels via FlashInfer 0.7.0.
vLLM Boosts DeepSeek-V4.1-Flash: 1.9x Low-Concurrency Speed, 5x Agentic Throughput
According to a vLLM blog post dated October 7, 2026, within three weeks of DeepSeek-V4.1-Flash's release, vLLM optimizations made the model 1.9x faster at low concurrency and increased its throughput 5x on the SemiAnalysis AgentX benchmark. The improvements are attributed to SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.
DeepSeek releases V4.1-Flash-1017 open-weight model with faster, cheaper agent tasks
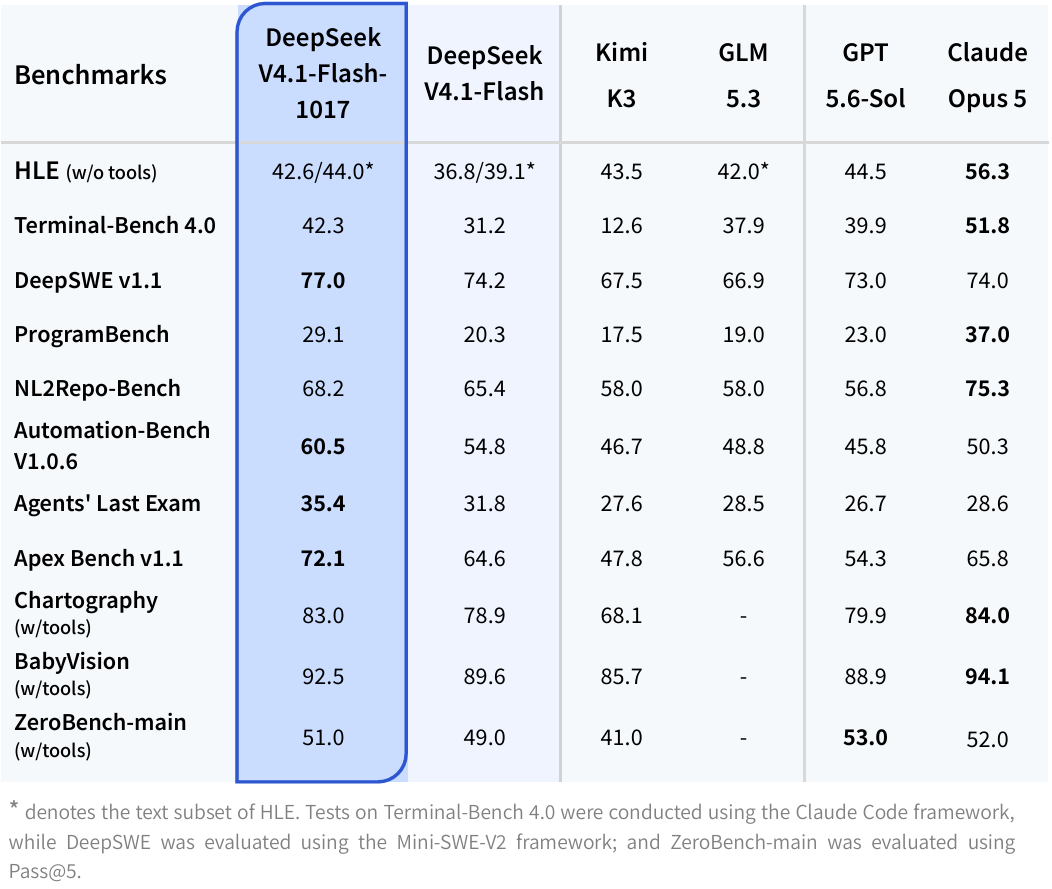
DeepSeek released V4.1-Flash-1017, an open-weight model checkpoint with 763B parameters, now live on its website, app, and API. The update claims stronger benchmark performance, faster task completion, and shorter outputs than its predecessor, achieved via reinforcement learning with self-feedback for end-to-end project development. DeepSeek also opened its Search & Fetch APIs to everyone, priced at $0.75 per 1000 successful requests, and requires DeepSeek Harness v0.2.1-rc.1 or later for optimal use.
9 reports · 6 sources955 points · 717 comments
vLLM Uses AI Agents to Optimize Kimi K3 Decode on NVIDIA GB300, Hitting 840+ Tokens/s
The vLLM team reports using agent-assisted development to build a unified CuTe DSL decode path for Kimi K3 on NVIDIA GB300, covering attention, MoE, and communication across 8 or 16 GPUs. The optimizations achieve over 840 tokens/s at batch 1 on 16 GPUs with DSpark (synthetic AL=6), 1.5–2× higher decode throughput in several configurations, and up to 1.8× higher P90 interactivity on the AgentX workload. The team notes that agent-optimized inference code is outpacing their manual review and maintenance workflow.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe