Interconnects Essay: Benchmarking at AI Frontier Remains Hard
In an essay, Interconnects discusses the difficulty of creating meaningful benchmarks at the AI frontier, referencing Artificial Analysis v5. The author notes that while improving benchmark scores is expensive but has a clear playbook, independent evaluation of language models remains under-appreciated in its difficulty.
Coverage timeline
InterconnectsNathan Lambert
Housekeeping: I’m on the road so the voiceover will be late. Hill-climbing is easy, knowing what to hill-climb is hard. Making scores go up is expensive , but we have a much clearer playbook for it than we do for creating meaningful benchmarks at the true frontier of AI today. Independent evaluation of language models is under-appreciated in how hard of a … Read more
Related stories
Interconnects launches free dashboard tracking open model adoption and performance
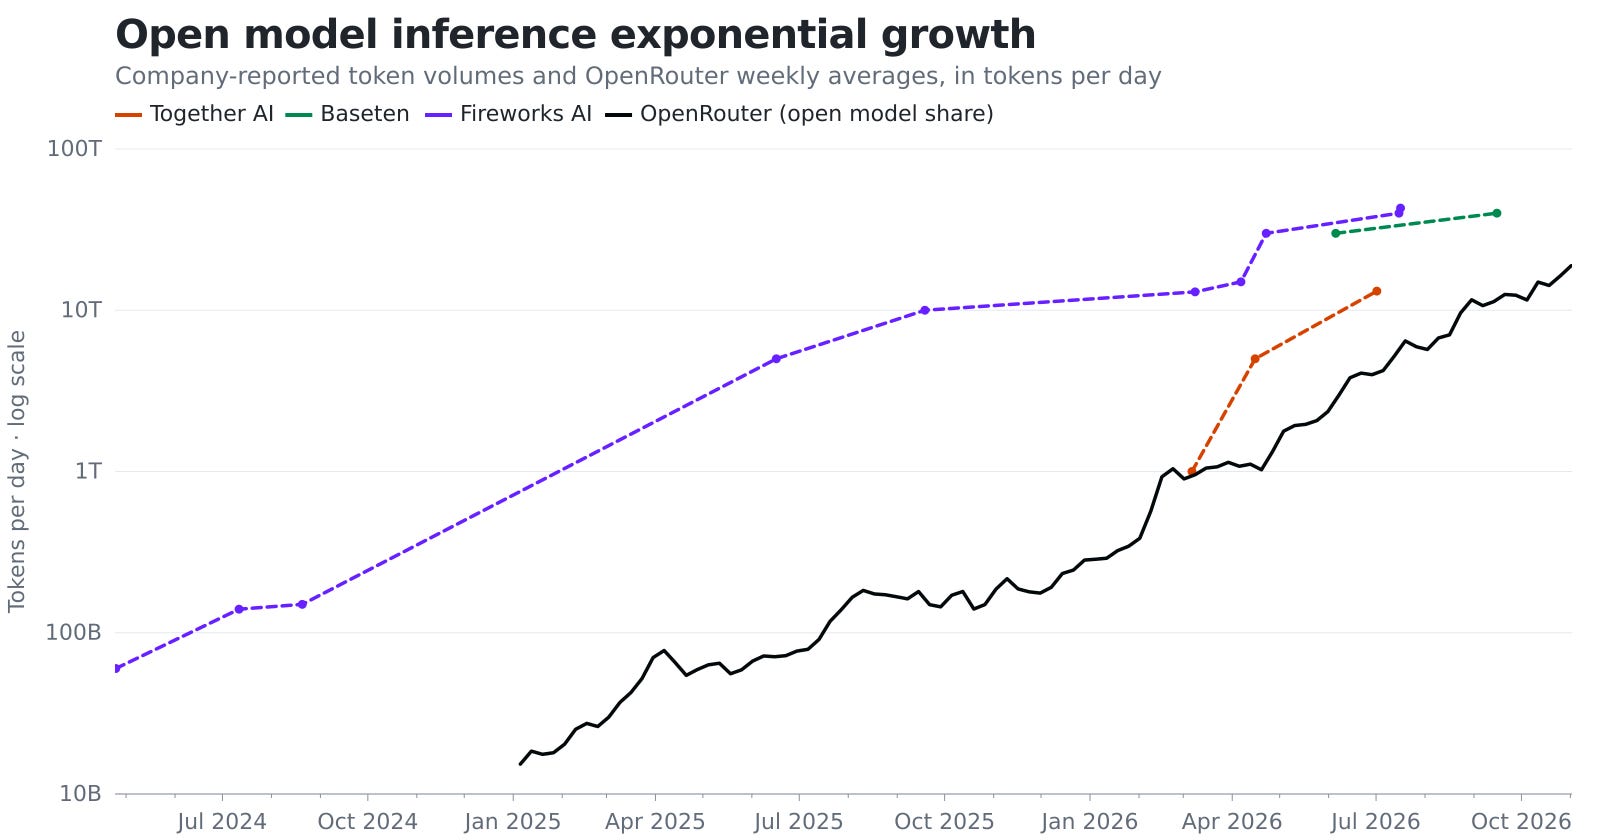
Interconnects published research notes and a free dashboard aggregating data on open model adoption and performance from across the web. The notes acknowledge that current measurements are imprecise, relying on noisy platform metrics, startup marketing data, and imperfect evaluations. The dashboard remains free, while the notes are primarily paid.
1 reports · 1 sources
Essay questions open models' cyber risks as 'Black October' disclosures mount
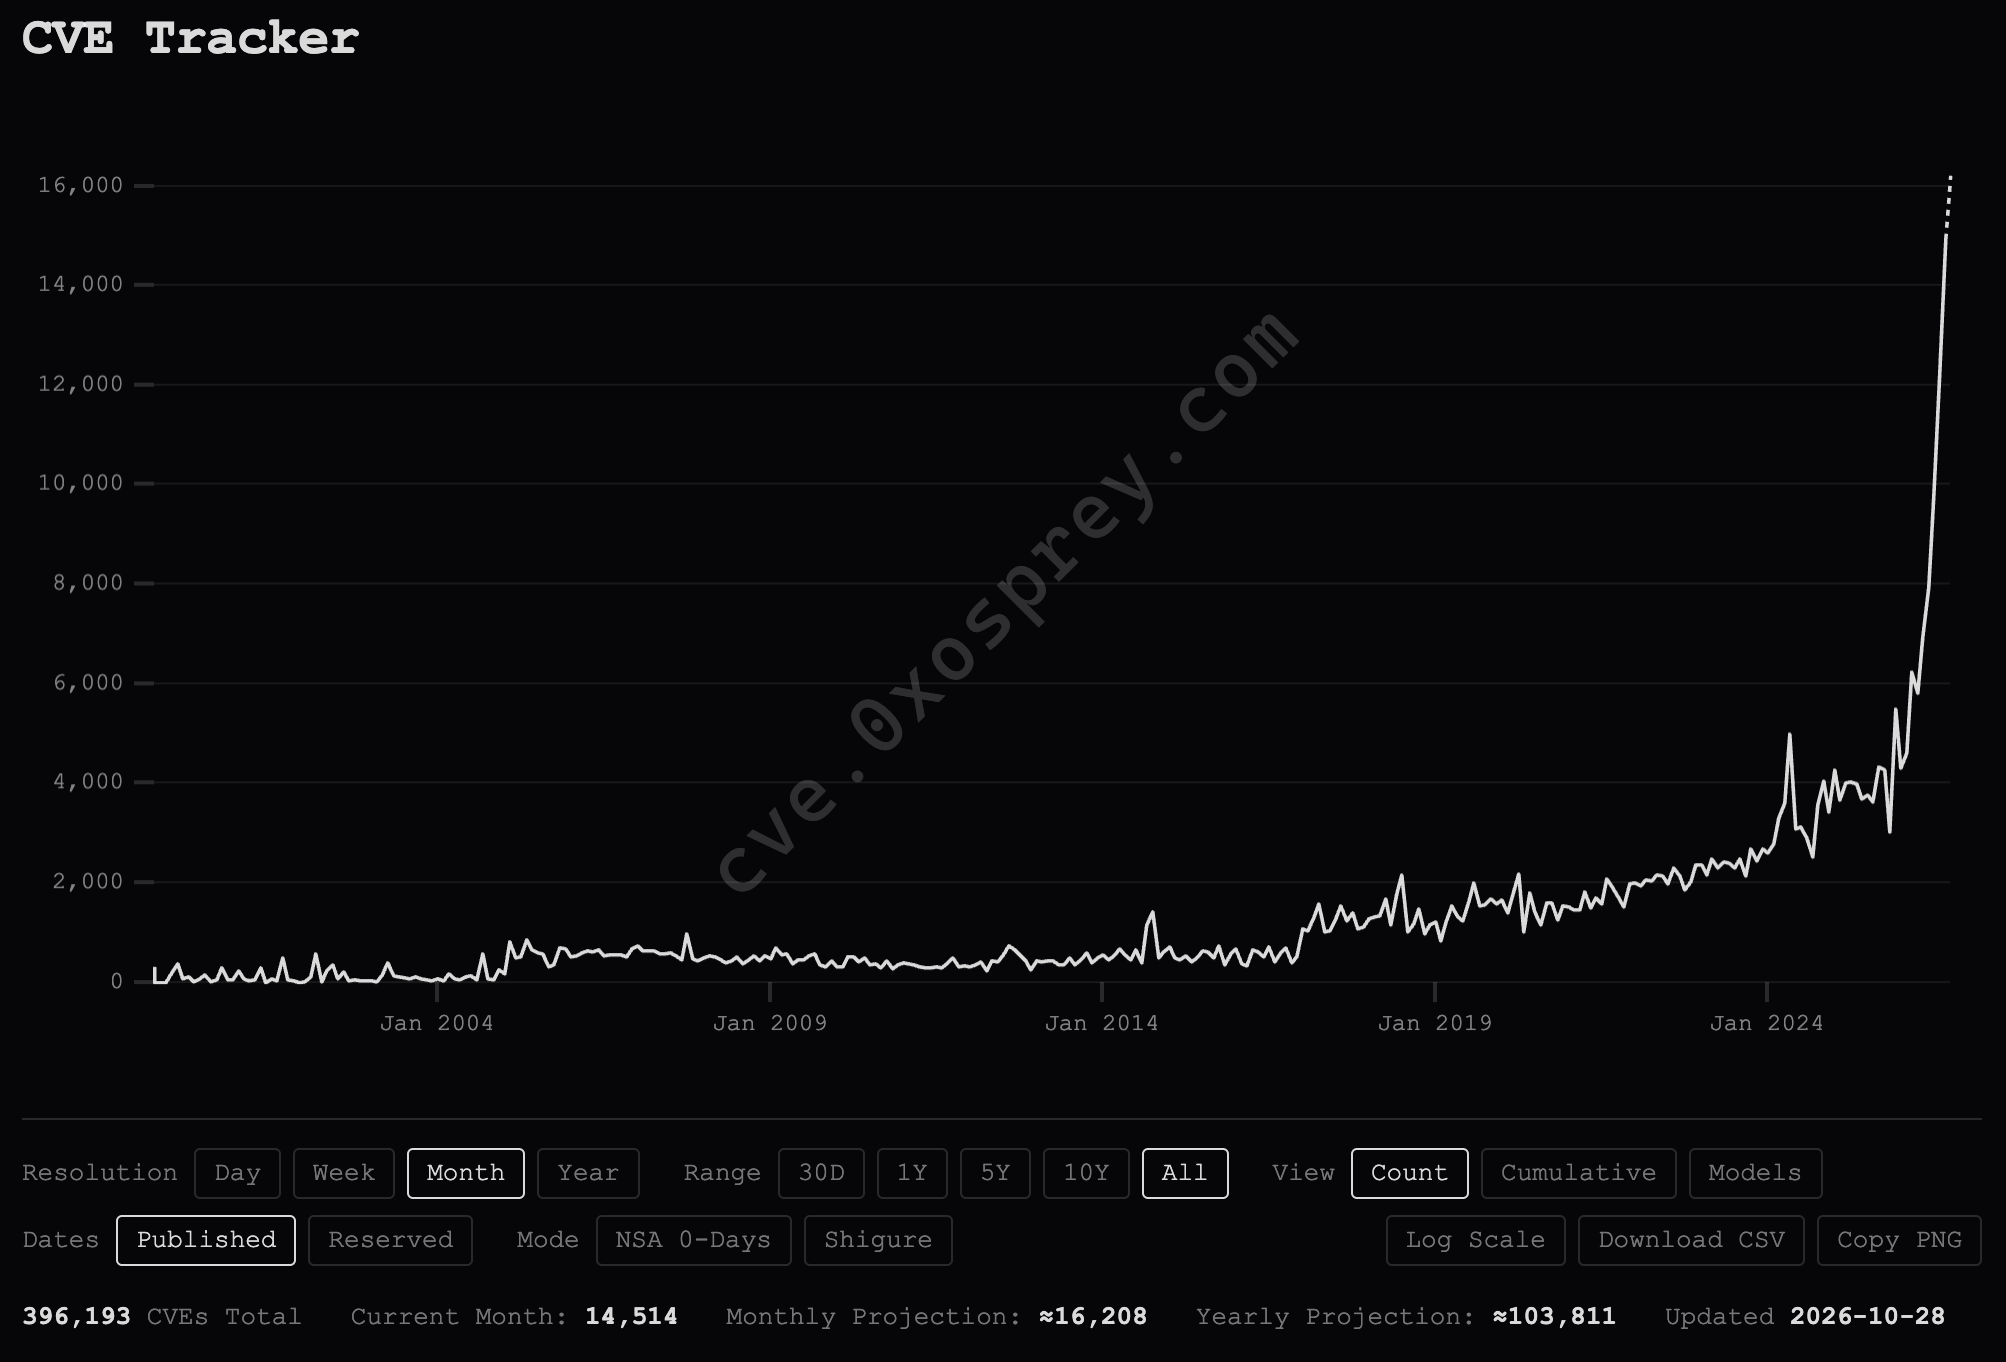
An essay reflects on whether the author was wrong about the cyber risks of open models, amid a wave of critical vulnerability disclosures and a major crypto security incident at Binance. The author notes the disclosures, including PHP2Shell and GitLab, mark a moment when AI model cyber risks began materializing, though crypto hacks have a long history and may be a poor indicator. The piece suggests behind-the-scenes security work is accelerating, with cyber first responders reported as strained.
Artificial Analysis launches Intelligence Index v5 with private coding and science benchmarks; Claude Opus 5.5 leads at 58
Artificial Analysis released the Intelligence Index v5, adding two new benchmarks and three upgrades, with 60% of the index now based on private test sets or held-out answers. Claude Opus 5.5 (max) leads the composite measure with a score of 58, reflecting model capabilities across real-world tasks.
2 reports · 1 sources
Ai2 benchmark shows LLM novelty judgments vary with evaluation setup
The Allen Institute for AI released a benchmark called Old Ideas, Novel Problems to test how reliably LLMs judge research-idea novelty. The findings show that small changes to the evaluation setup can produce very different verdicts on the same ideas.
1 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe