Tsinghua's BaGuaLu-2 adapts MoE memory management at runtime, boosting throughput on 12,288 DCUs
At SC26, Tsinghua researchers present BaGuaLu-2, a runtime-adaptive memory management system for MoE training that adjusts recomputation and offloading per operator based on real-time load, preventing activation spikes from causing out-of-memory crashes. Tested on 128 to 12,288 Hygon DCUs with models from 188B to 1.04 trillion parameters, it achieves an average 1.14x throughput gain over baselines, with total throughput of 2.012 EFLOPS at 12,288 cards and average MFU of 32.9%.
Coverage timeline
机器之心机器之心
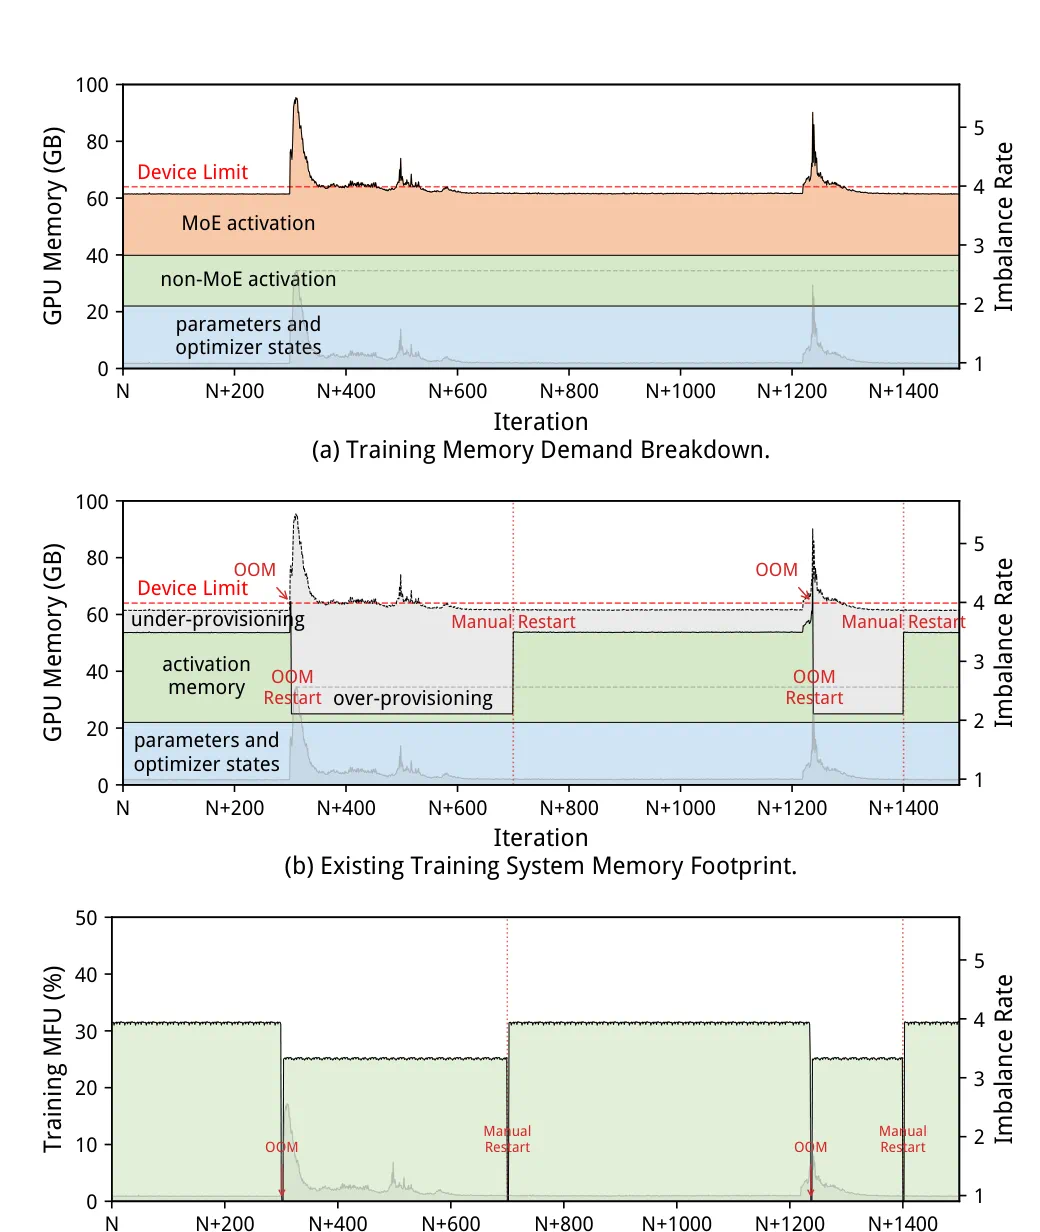
大模型训练已经跑到万卡集群规模,显存始终是那道隐形的门槛。 MoE 架构把大模型推到了万亿参数级别,也埋下了一颗定时炸弹:显存尖峰。某个微批次的 token 一旦集中涌向少数专家,激活显存瞬间飙升,一张卡 OOM,整个分布式任务直接挂掉 —— 几百步白跑。 重计算、激活卸载都是常用手段,但问题在于静态配置。激进配置平时 MFU 30%,尖峰必崩,一次冷重启 284 秒;全层重计算稳是稳,MFU 直接掉到 24.6%,算力长期闲置。怎么选都亏。 能不能让系统自己跟着显存压力走 —— 平稳时全速跑,尖峰来了临时加码,过去了再收回来? 清华大学翟季冬教授团队的答案是八卦炉2(BaGuaLu-2 ),相关论文已被SC26录用。运行时自适应,零配置干预 —— 门控算完、专家算之前这个窗口里,系统根据真实负载实时决策,不同算子分别选择保存、重计算或卸载,把显存峰值压在设备上限以内。不用停任务,不用改配置。 万卡智算中心实测:128 到 12,288 张海光 DCU,188B 到 1.04 万亿参数,平均吞吐比基线高 1.14×,12,288 卡下总吞吐 2.012 EFLOPS,平均 MFU 32.9%、最高 35%。 论文链接:https://arxiv.org/abs/2610.23064 一、问题背景:MoE 训练中的显存尖峰痛点 如果你训练过 MoE 模型,大概率遇到过这种情况:训练跑了几百个迭代都很平稳,突然某个微批次里 token 集中涌向少数几个专家,激活显存瞬间飙升,一张卡 OOM,整个分布式任务直接挂掉。 问题出在 “选择” 本身 MoE 的核心是路由器为每个 token 选择少数专家执行。现代负载均衡方法能抑制长期的专家拥塞,但无法预知当前批次的具体内容。实测数据:97.1% 的迭代中专家负载不均衡率低于 1.2×,但 2.9% 的异常迭代中最高达到 2.6×。就是这极少数迭代,反复打断训练进程。 流水线让问题更严重 流水线预热阶段只有前向、没有反向释放激活,多个微批次的激活同时驻留设备。如果其中一个批次把大量 token 路由到当前设备的少数专家,额外的 MoE 激活叠加在已驻留激活之上,局部偏斜直接变成设备级 OOM。 静态配置的两难 重计算和卸载是常用工具,但传统做法是在启动前写死配置。激进配置正常阶段 MFU 30
Related stories
HKUST and Huawei propose BalanceRoute to cut MoE LLM serving load-balancing bottleneck
Researchers from HKUST and Huawei's 2012 Lab propose BalanceRoute, an online routing method that models synchronous waiting in MoE LLM serving and converts short-term load prediction into routing decisions. In a 96-GPU test, the predictor-based variant BR-H improves decode throughput by about 15% over the strongest baseline. The work is accepted by NeurIPS 2026 and deployed in the jointly built MaaS system MathBot-Pie.
1 reports · 1 sources
Tsinghua and Qujing Introduce KTransformers-FineTune for CPU-GPU MoE Fine-Tuning
Tsinghua University's MADSys lab and Qujing Technology, with LlamaFactory, introduced KTransformers-FineTune (KT-FT), a CPU-GPU co-computation method for fine-tuning mixture-of-experts (MoE) models. It claims 2.5-21.2x throughput gains over traditional offloading by having the CPU compute expert weights directly instead of transferring them to the GPU. The approach includes a semantic-aware proactive layout engine and dynamic thread scheduling for routing skew, and is fully open-sourced.
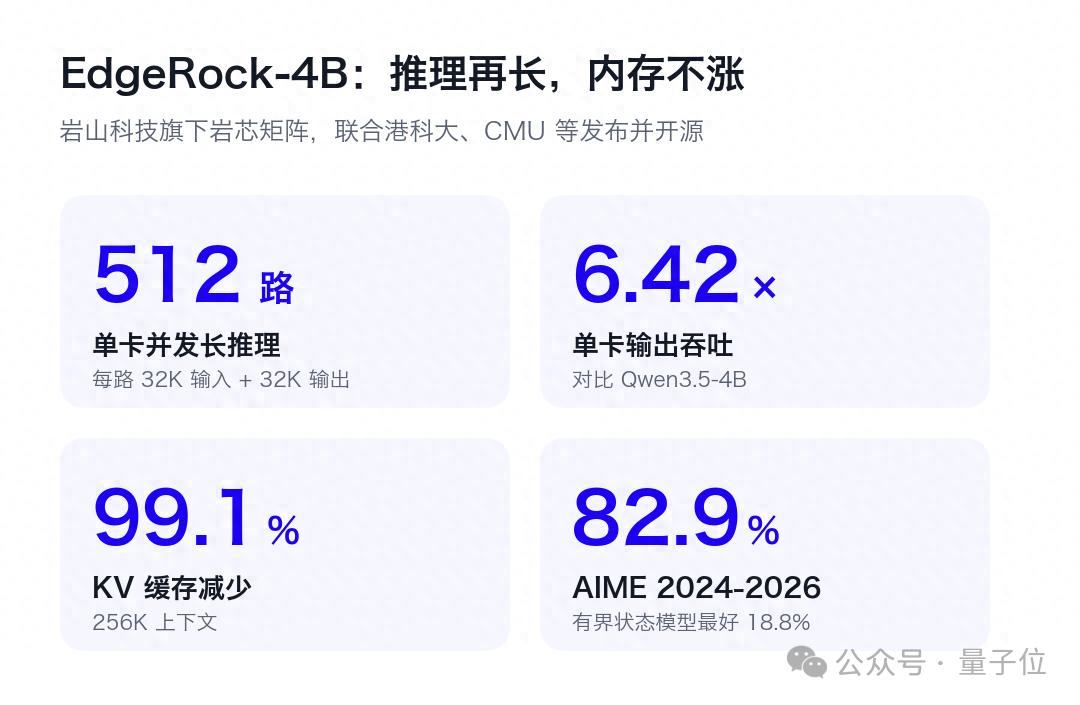
EdgeRock-4B open-weight model cuts KV cache 99.1%, boosts throughput 6.42x
Rock Matrix (a unit of Yandex? no, 岩山科技) together with HKUST and CMU released and open-sourced EdgeRock-4B, an open-weight model that keeps KV cache fixed at 72MiB from 4K to 256K context, a 99.1% reduction versus the source model. On a single 80GB GPU it runs 512 concurrent long-context inferences at 12,124 tokens/s output throughput, 6.42x the source model, while retaining an 82.9% average pass rate on AIME 2024-2026, far above the best bounded-state model at 18.8%. The model supports text and image inference, with weights and code open-sourced.
1 reports · 1 sources
Huawei, CUHK, HKUST release LegoFlow for automated code data engineering
Researchers from Huawei, CUHK, and HKUST introduced LegoFlow, an automated framework that streamlines code data engineering from repository collection to training and evaluation. They released LegoFlow-SWE with 5,000 tasks and 2,780 verified trajectories, and demonstrated recursive self-improvement: two iterations raised Qwen3.5-35B-A3B-Base's SWE-bench Verified score from 7.6% to 64.4%.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe