Naive AI open-sources first model built with AI-led R&D
Naive AI, founded by Dai Jifeng, has open-sourced its first model, developed from day one with AI models handling coding, experiments, and analysis while humans set goals and constraints. The company focuses on post-training and agent development based on open-source models, echoing recent disclosures from Anthropic and OpenAI about AI-led research proportions.
Coverage timeline
机器之心机器之心
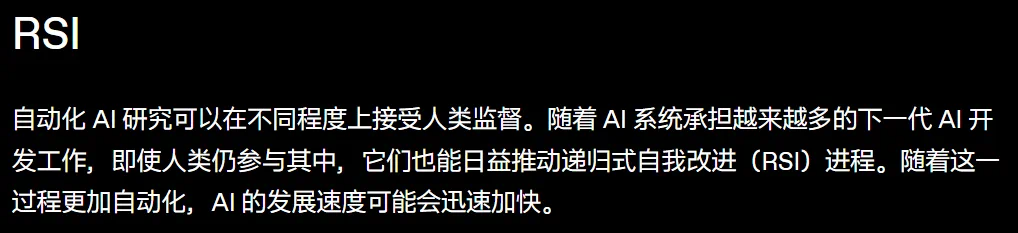
编辑|Panda、小熊猫 Naive AI 正在探索一条令人兴奋的新路径:让当前的 AI 模型去承担下一代模型的研发工作,并且让每一代诞生的模型都能够比上一代承担更多的研发工作。 10 天前,Anthropic 公布了一组少见的内部数据:公司内部的 AI 研发工作中,已有 26% 由 Claude「主导」完成。所谓主导,是指研 究员只需给出一条高层指令,Claude 就能端到端地完成任务的大部分,人类负责监督 。而在今年 2 月,这个比例还不到 1%。 而这并不是一个孤立事件。更早几天,OpenAI 宣布去年定下的「自动化研究实习生」目标已经达成:按标准工作日折算,其研究团队每投入 1 个人类工作日,就有约 3.1 个智能体工作日在同时运转。 9 月 21 日,OpenAI 又提议由美国牵头制定前沿 AI 全球技术标准,并把 递归式自我改进(RSI) 列为重点议题。 国内,智谱也在 9 月 17 日披露,由 GLM-5.3 驱动的 Infra Agent 在十万卡国产集群上,从零搭起了 GLM-5.3-Flash 的推理服务。 OpenAI 博客中对 RSI 的定义 短短半个多月,「 让 AI 研发 AI 」就已经从一个偏理论的话题变成了头部实验室争相公开的量化指标。 但仔细看,这些数字回答的大多是同一个问题: 研发下一代大模型,AI能接手多少工作? 而就在今年 2 月,当 Anthropic 的 AI「主导」比例还接近零的时候,代季峰的创业团队 Naive AI 成立了。 这家新创公司从一开始就摒弃了传统以人类为中心的研发体系, 把写代码、跑实验、监控流程、分析结果等研发工作交给 了 AI 模型 。而人类研究员把精力集中于三件事:提出目标,设定约束与评价标准、最终决策。 从第一天起让 AI 研发 AI, 这家新公司交出了首款模型 路线选择上,Naive AI 专注于开源模型后训练与 Agent 研发,没有从零预训练,而是以开源模型为起点,做架构改造、增量预训练和后训练。 开源生态正在成为新一批实验室的起点。前 OpenAI 首席技术官 Mira Murati 创办的 Thinking Machines Lab,7 月推出的首款模型 Inkling 虽是从零训练,架构却沿用了 DeepSeek-V3 的混合专家设计。 Naive AI 更进一步,直接基于开源基模继续
Related stories
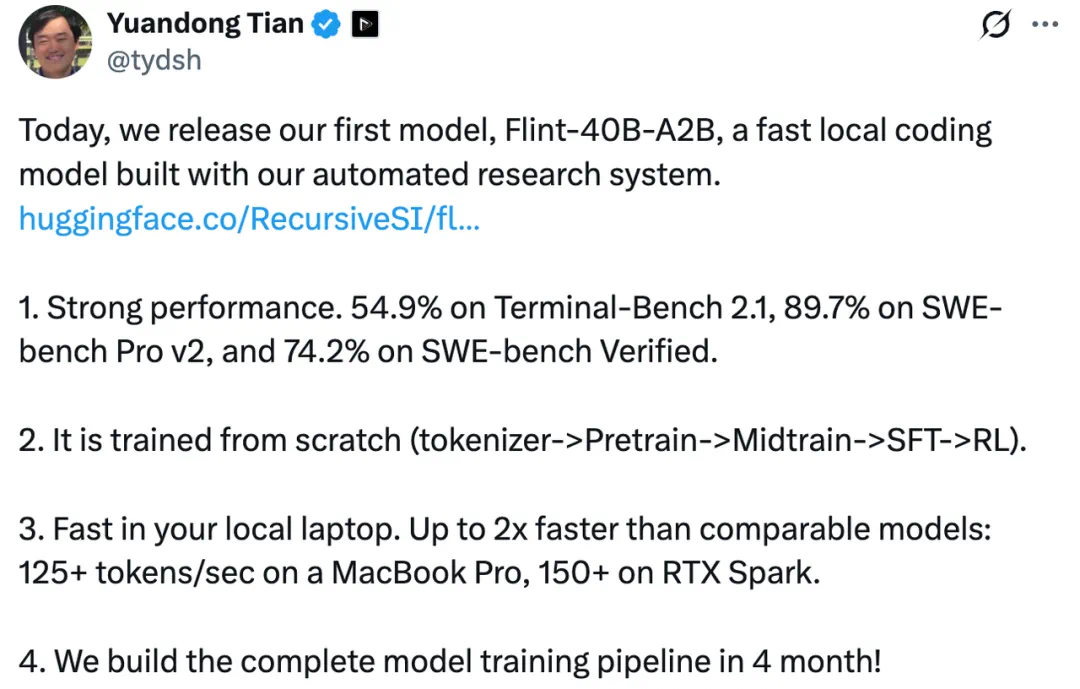
Recursive releases Flint, 40B coding model built largely by its Eureka Machine AI system
Startup Recursive has released Flint, an open-weight, 40B-parameter mixture-of-experts coding model with 2.5B active parameters per token, built in under four months with heavy automation from its Eureka Machine AI research system. The model outperforms sub-50B MoE models on coding benchmarks like SWE-Bench Pro v2 and runs at over 125 tokens per second on a MacBook Pro M4 Pro, with weights available on Hugging Face under Apache 2.0.
3 reports · 3 sources
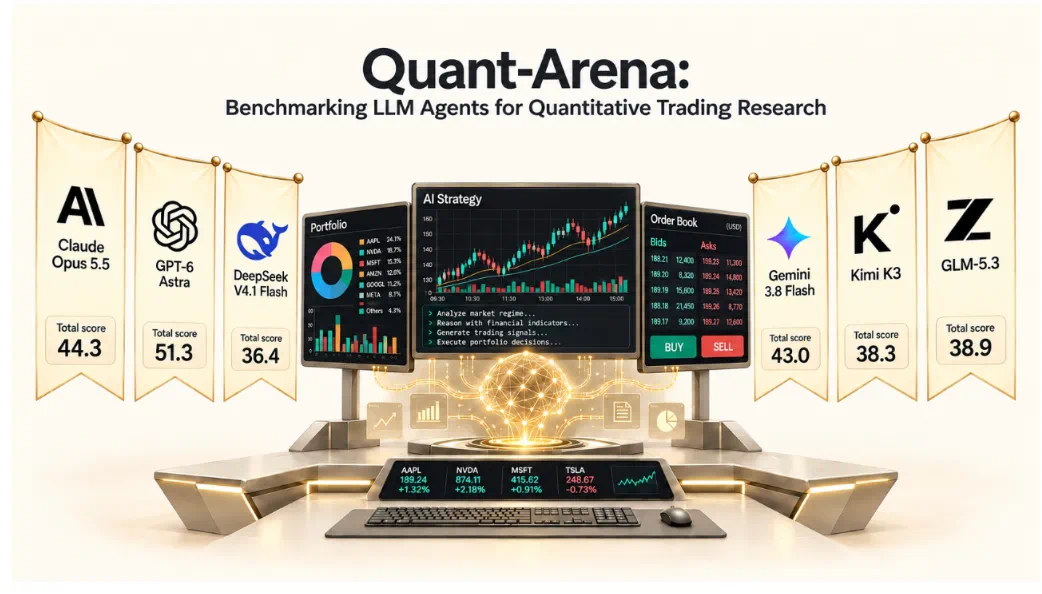
EinsiaAI's Quant Arena benchmark: most LLMs lose money on A-share trading
EinsiaAI's Navers Lab released Quant Arena, a benchmark testing nine models from six frontier model providers on A-share quantitative trading using real historical data from 2022-2023 and sealed 2024 market data. Only GPT series and Claude Opus 5.5 achieved profitability; the top scorer GPT-6 Astra posted 10.7% annualized return, below the 17.1% market benchmark. The study highlights that better market prediction does not necessarily translate into higher returns.
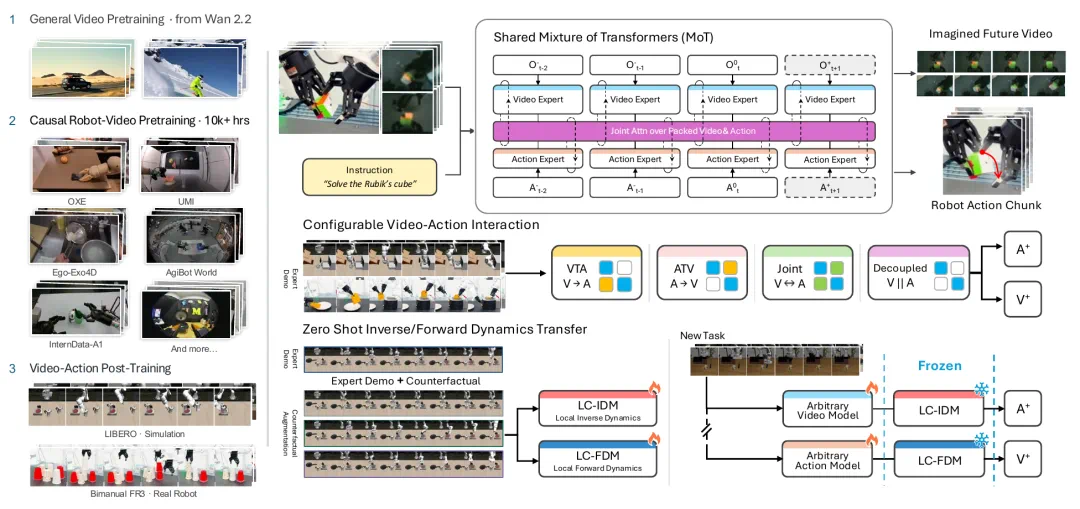
Stanford's OpenWAM framework isolates design choices in world-action models
Stanford researchers led by Li Fei-Fei, Jiajun Wu, and Ehsan Adeli released OpenWAM, an open framework for composable world-action models, aiming to systematically isolate which design choices drive performance gains. The release follows Black Forest Labs' open-source FLUX 3 Action, a 7B world-action model that surpassed Cosmos 3 Nano on Nvidia's RoboLab-120 leaderboard with less than half the parameters.
AIBuildAI open-sources PostTrain Agent, tops PostTrainBench with 46.6 points
AIBuildAI released PostTrain Agent, an open-source recursive self-improving agent that autonomously performs LLM post-training, including algorithm design, data collection, coding, and experiments, without human intervention. On the PostTrainBench benchmark, it scored 46.6, ranking first among frontier models and agent systems, close to human expert performance (51.1). The team also open-sourced the code, knowledge base, and technical report.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe