Xiaomi open-sources MiMo-V2.6 Pro and Flash; Pro tops open-weight leaderboard
Xiaomi's MiMo team released and open-sourced the MiMo-V2.6 series, including Pro and Flash omnimodal models, after a six-day livestreamed reinforcement learning training run that cost $3.5 million. MiMo-V2.6-Pro scored 46 on Artificial Analysis' Intelligence Index, tying Grok 4.7 and beating GLM-5.3, making it the top-scoring open-weight model on that benchmark; Xiaomi claims Pro performs on par with Opus 5 and GPT-5.6 Sol across most agent benchmarks.
Coverage timeline
小米 MiMo Blog
Frontier intelligence, all the modalities, built in public.
Techmeme
Xiaomi : Xiaomi debuts open-weight omnimodal models MiMo-V2.6 Pro and Flash; Pro allegedly performs “on par with Opus 5 and GPT-5.6 Sol across most agent benchmarks” — Frontier intelligence, all the modalities, built in public. Today, we are releasing and open-sourcing the MiMo-V2.6 series.

Carl Franzen / VentureBeat : MiMo-V2.6-Pro ties Grok 4.7 (xHigh) and beats GLM-5.3 (max) on Artificial Analysis' Intelligence Index, making it the benchmark's top-scoring open-weight model — That puts Xiaomi's new flagship ahead of proprietary models including xAI's Grok 4.6, currently at 44, and Google's Gemini 3.8 Flash …

量子位量子位
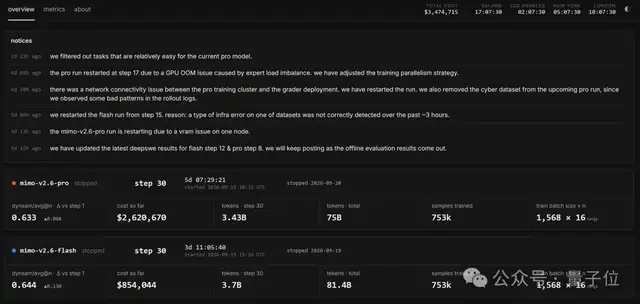
6天烧光2000多万,拿下开源第一!小米史无前例「炼丹直播」收官 一水 2026-09-22 19:50:28 来源: 量子位 Hugging Face CEO:「太棒了」 6天,2000多万,小米这场史无前例的「炼丹直播」终于尘埃落定。 过去这六天,小米把一场大模型强化学习训练搬进直播间,眼看着美元计价器一路狂跳。 如今,MiMo-V2.6的Pro和Flash双双跑完30个训练Step,最终账单定格在350万美元(约合人民币2344万元)。 钱烧完了,模型也冲上去了。 MiMo-V2.6-Pro,1.02万亿参数,420亿激活,在Artificial Analysis Intelligence Index上拿到46分,位列开源第一。 Hugging Face CEO也称赞说,「太棒了」。 并且在多数Agent评测中,Pro的成绩已经逼近Claude Opus 5和GPT-5.6 Sol。 罗福莉将其称为 「迄今为止任何开源模型团队所进行的规模最大的单次强化学习训练之一」 。 还没完,更猛的还在后面,这位曾参与DeepSeek-R1研发的小米MiMo负责人直言: 在我看来,它背后的研究创新和工程挑战,超过了我曾参与其中的DeepSeek-R1。 这话分量有多重?看完MiMo-V2.6的训练细节就知道了。 2000多万烧完,开源模型冲进闭源前沿 聊技术之前,先带大家快速过一下这次直播的「收官战报」。 MiMo-V2.6-Pro跑完30个Step,用时5天3小时,花掉约260万美元; Flash同样跑完30个Step,用时3天10小时,花掉约90万美元。 每个Step包含1568个Prompt,每道题让模型尝试16条不同路线,一轮就会产生超过2.5万条Rollout。 按技术报告单步2.7B~3.7B training tokens计算,Pro全程累计处理约81B~111B Tokens,相当于塞满超过8万个百万Token上下文窗口。 这么多Token和真金白银砸下去,效果也相当直接。 30个Step结束后, Flash的平均通过率相对提升25%,Pro相对提升12% 。 整体上涨之外,更有说服力的变化出现在DeepSWE v1.1这项样本外测试上。 Pro从58.4分涨到72.57分,提升约14分; Flash从48.7分涨到65.68分,提升约17分。 DeepSW
Related stories
NVIDIA launches Nemotron 3.5 Super VL, 120B open model; vLLM adds Day 0 support
NVIDIA has launched Nemotron 3.5 Super VL, a 120B-parameter open model for enterprise agents, claiming it outperforms frontier models on specialized benchmarks. vLLM announced Day 0 support for the model, enabling multimodal agent workflows with image, document, and video understanding, OpenAI-compatible serving, and multi-token prediction.
2 reports · 2 sources
MiniCPM-V 4.7 open-sourced: 35B MoE runs offline on iPhone in 3GB memory
ModelBest and OpenBMB have open-sourced MiniCPM-V 4.7, a multimodal MoE model available in 35B-A3B and 1B versions. The 35B-A3B, the first MoE in the MiniCPM-V series, runs on iOS and Android devices with about 3GB memory, achieving over 13 tokens per second on an iPhone 17 Pro Max offline. The 1B version (1.3B actual parameters) targets OCR, math, and video understanding.
1 reports · 1 sources
Mistral Large 4 preview: 1T-parameter open-weight model, weights due Oct 27
Mistral AI released a public preview of Mistral Large 4 (ML4), a 1-trillion-parameter multimodal model with 49 billion active parameters, trained on 3,800 Nvidia Grace Blackwell GPUs in its European data centers. The open weights are promised by October 27. Early benchmarks show an Artificial Analysis Intelligence Index score of 38, comparable to DeepSeek V4.1 Flash, and the model is claimed to top any open model from the US or Europe.
10 reports · 5 sources2033 points · 1210 comments
Reflection AI unveils open-weight model Beam, claims lower compute and near-Qwen3.8-Max performance
Reflection AI, backed by Nvidia, has unveiled its first open-weight model, Beam, claiming it excels at coding and agentic tasks while using 3x-4x less compute than comparable models. The company says Beam's reasoning performance nears Qwen3.8-Max and rivals GLM-5.2 at lower inference compute, with weights expected to be released this month.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe