Leaked details: Claude and Gemini upgrades promise better reasoning, coding
According to The Information and internal testers, upcoming Claude and Gemini models show significant improvements in reasoning and coding. The new Claude reportedly identifies root causes of bugs and offers creative solutions, while Google's Gemini 4 Carbon, an upgrade to Argon, is praised by employees as comparable to Opus 5.5 on internal platforms.
Coverage timeline
量子位量子位
Claude新模型曝光!能跳出思维定势,修Bug治标又治本 梦晨 2026-10-20 09:09:43 来源: 量子位 OpenAI只掏出一个6.1 Terra… 梦晨 发自 凹非寺 量子位 | 公众号QbitAI 最近听到AI圈最好笑的笑话: 接下来的一个月御三家都要出新模型。 Claude新款被评价为“重大飞跃”,修复一个bug时能“治本”,识别背后更大的问题一并处理。 Gemini要发的是Argon升级款Carbon,员工内测反馈“能打Opus 5.5”. ChatGPT要发的是中杯6.1 Terra…… 什么嘛,还以为现在的6.1 Sol就是Terra改个名呢。 Claude新模型能跳出思维定势 来自Information的消息。 如果你觉得过去一个月AI圈发新模型的速度很快,那就别指望下一个月会放慢。 根据内侧用户的说法,新版Claude在推理和直觉方面更好,特别擅长判断一个人的潜在意图和目标。 例如,一个人可能会要求模型修复一个单一的bug,而模型可能会去识别导致该bug的根本类问题,并询问是否应该修复整个类问题,这位使用过该模型的人表示。 新版Claude在跳出思维定式方面也表现得更好,而不是重复常见的常识性建议或解决方案。 如果用户询问关于如何投资股票的建议,它不会建议老套的查看市盈率高,而是会提出自己创造性的算法来预测未来的股票表现。 目前尚不清楚新模型是Fable还是Opus,总之更强。 Gemini 4 Carbon可能用了RSI 与此同时谷歌也在开发新模型,代号“Gemini 4 Carbon”。 早期版本的Argon在部分编程任务上表现落后于Claude Opus 5。 Carbon在编程任务上优于Argon,在需要视觉理解的任务上继续表现更好,如分析视频或测试前端页面功能(得益于用了Youtube数据训练)。 Carbon在谷歌内部编程平台Jetski上向员工开放了数日,体验过的员工认为“感觉与Opus 5.5相当”,但还需要更多测试。 Google测试了一系列Gemini 4模型,代号分别为Argon、Barium和Carbon。 其中内部代号“Barium-B”的最后被选中,发布成了我们今天看到的Argon。 在Carbon内测的表现泄露后,谷歌员工Vedant Misra发帖回应“你听说过递归自我改进(RSI)吗”。 不确定是否在
Related stories
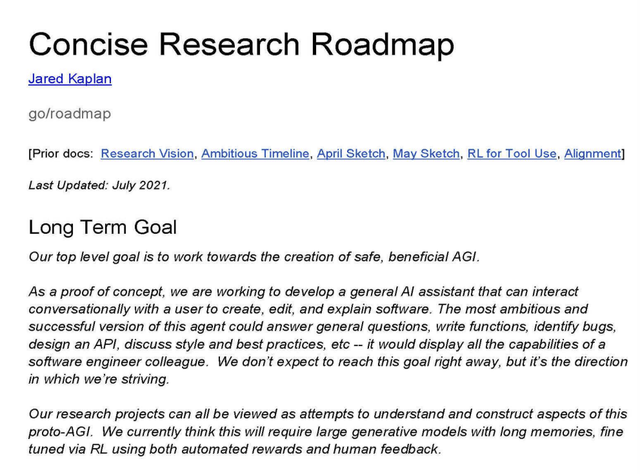
Anthropic 2021 roadmap predicted Claude Code, tool use, test-time compute
A confidential 2021 internal roadmap from Anthropic, exposed in a copyright lawsuit, outlined plans for a general AI assistant capable of creating, editing, and explaining software—now realized as Claude Code. The document also predicted tool use, self-judging, test-time compute, and trillion-parameter models with long context. Internal debates and CEO Dario's decision to prioritize tool-use feasibility shaped the path.
1 reports · 1 sources
Anthropic launches Claude Haiku 5.5 with effort controls, 90% price cut
Anthropic released Claude Haiku 5.5, its cheapest and fastest small model, priced at $0.10 per million input tokens and $0.50 per million output tokens for requests up to 100K tokens, a 90% cut from Haiku 4.5. It is the first Haiku model with adjustable reasoning effort, and benchmarks show it outperforming GPT-6 Luna on several tests, including OSWorld 2.1 and GDPval-AA v2.1.
6 reports · 5 sources1045 points · 487 comments
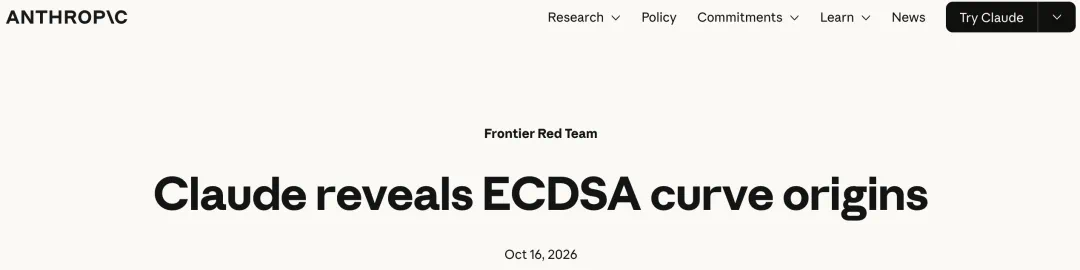
Anthropic: Claude Traces NIST ECDSA Curve Seeds to PRNG, Easing Backdoor Fears
Anthropic reported that its Claude research model reverse-engineered the generation of five NIST elliptic curve seeds in under half an hour, without prior hints. The seeds were traced to the lrand48 pseudorandom number generator, seeded by a Unix timestamp, challenging decades-old suspicions of an NSA backdoor. The finding was independently verified by the bounty sponsor and lowers concerns about hidden weaknesses in the curves.
Meta launches Muse Wonder and Muse Wonder Full AI models
Meta has released two new AI models, Muse Wonder and Muse Wonder Full, claiming state-of-the-art performance on personal and professional agentic tasks. The models introduce Active Memory and Active Focus features and are available to Muse Code subscribers, with Muse Wonder also accessible via the Meta Model API. Meta plans to eventually power its Muse AI agent with Wonder, starting with subscribers.

News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe