Ai2 releases StateBench benchmark for tracking state changes in long documents
The Allen Institute for AI (Ai2) released StateBench, a benchmark that tests how language models track changing information across long documents at four difficulty levels. The benchmark reveals where models struggle and shows how targeted training helps recurrent and hybrid architectures handle longer sequences.
Coverage timeline
Ai2 (Allen Institute for AI)
StateBench tests how language models track changing information across long documents at four difficulty levels, revealing where models struggle and how targeted training helps recurrent and hybrid architectures handle longer sequences.
Related stories
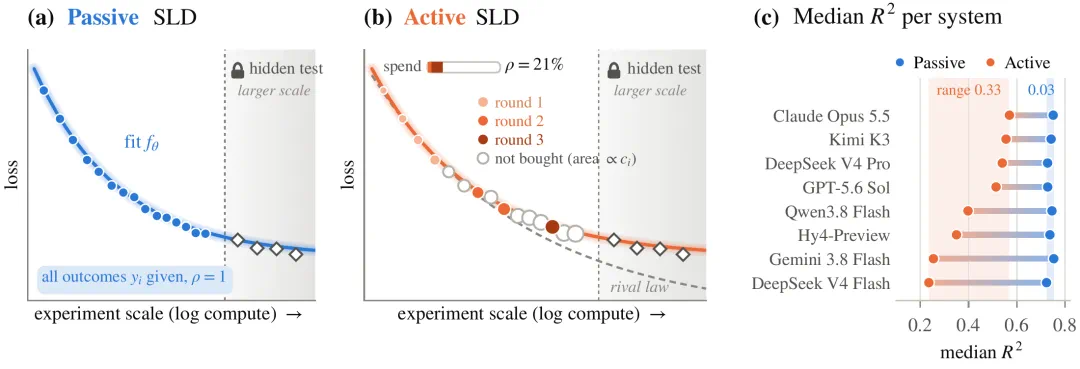
SLDBench v2: Frontier Models Degrade When Planning Scaling-Law Experiments
Researchers from CUHK-Shenzhen, HKU, Tsinghua, and PKU released SLDBench v2, an ICLR 2026 benchmark where AI must autonomously choose scaling-law experiments from a priced catalog with real compute costs. All 8 frontier models degraded when selecting experiments, with prediction errors increasing 1.5 to 4.7 times. Best performer Claude Opus 5.5 used only 4% of full data cost yet surpassed classical power-law fitting accuracy.
1 reports · 1 sources
Fudan, Tencent Hunyuan, Tsinghua Release ExplorationBench to Test AI Rule Discovery
Fudan University, Tencent Hunyuan, and Tsinghua University released ExplorationBench, a benchmark measuring how AI systems discover rules in unfamiliar environments. It includes two altered 'alien worlds'—the programming language AlienCode and the logic proof system AlienLogic—where models must learn rules through trial and error. Results showed that without environment feedback, scores remained low (max 11.0%), while autonomous exploration led to high scores (up to 89.0%).
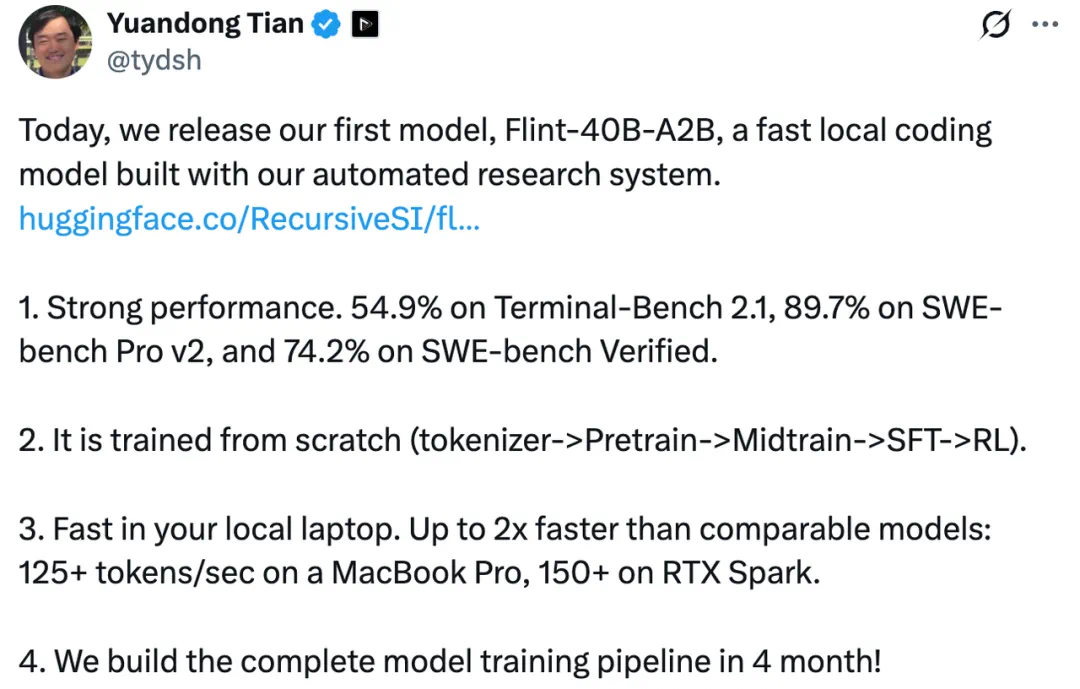
Recursive releases Flint, 40B coding model built largely by its Eureka Machine AI system
Startup Recursive has released Flint, an open-weight, 40B-parameter mixture-of-experts coding model with 2.5B active parameters per token, built in under four months with heavy automation from its Eureka Machine AI research system. The model outperforms sub-50B MoE models on coding benchmarks like SWE-Bench Pro v2 and runs at over 125 tokens per second on a MacBook Pro M4 Pro, with weights available on Hugging Face under Apache 2.0.
Tsinghua introduces SRHarness and MechBench for agentic symbolic regression and mechanism discovery
Tsinghua University researchers introduced SRHarness, a runtime framework for agentic symbolic regression, and MechBench, a benchmark for mechanism discovery, aiming to improve AI's ability to derive formulas from data and understand underlying physical mechanisms. Experiments show SRHarness achieves 72.97% symbol recovery with DeepSeek-v4-flash-0731, far exceeding Codex's 20.72%, while MechBench reveals that even GPT-5.6-sol-powered Codex recovers mechanisms at only 13.75% on the core set, highlighting a significant gap between pattern discovery and mechanism understanding.

News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe