MiniCPM-V 4.7 open-sourced: 35B MoE multimodal model runs on iPhone at 30+ tokens/s
面壁智能 and OpenBMB have open-sourced MiniCPM-V 4.7, including a 35B-A3B MoE multimodal model that runs fully on-device, occupying about 3GB of memory and exceeding 30 tokens per second on the iPhone 18 Pro Max. The team calls this a milestone toward edge intelligence, with co-founder 刘知远 stating that GPT-6-level intelligence on phones within two years is feasible.
Coverage timeline
机器之心机器之心
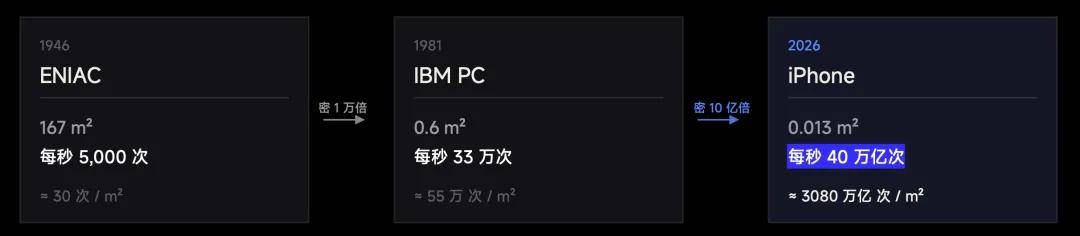
编辑|冷猫 上世纪 40 年代,计算机还是占据一整个房间的庞然大物。它们体积庞大、造价高昂,只有少数科研机构和大型组织能够使用。那时,计算是一种昂贵而稀缺的资源。 但直到今天,仅仅是普通人手里的 iPhone,单位体积里的计算能力都已提高了数十亿倍。那时的人不会想到,全世界大部分的计算都在每个人的桌上和口袋里完成。 历史是个圈,智能的发展也一样。 从 GPT 掀起大模型浪潮开始,能够被用户感知的「智能」就集中在少数科技巨头的数据中心里,运行在云端。而大模型诞生伊始的我们,也没有料到仅仅数年后, 一个超越了 GPT-4V 级别智能的模型,能够流畅运行在手机上 。 端侧智能的多次降临。横轴是时间,纵轴是参数量。颜色代表模型表现,红色表示性能较强,蓝色表示较弱。 近期, 面壁智能联合 OpenBMB 社区开源了 MiniCPM-V 4.7 。其中的 35B-A3B 版本,是一个 350 亿参数的 MoE 多模态模型,在手机上只占约 3GB 内存,在最新的 iPhone 18 Pro Max 上速度已经超过每秒 30 个 token 。 让我们来看看,一个打开了飞行模式的 iPad,运行 MiniCPM-V 4.7-35B-A3B 端侧模型,执行多模态任务的实机录屏表现。 作为完全本机运行的 35B 参数模型,表现真的很惊艳。回答准确的同时,输出速度依旧可观,保持在一个体感流畅,但也不至于让人眼花缭乱的速度。多模态能力也很强劲,对手写的数学解题也能够准确识别。 MiniCPM 真的从当年的「小钢炮」进化成了端侧运行的能力全面的性能猛兽。 「从 2024 年开始,我们就说要做端侧智能,当时它还是一个远景。到了今天,这个远景已经变成了近景。」面壁智能联合创始人、首席科学家刘知远说。 这款模型背后,是 面壁智能多模态大模型实验室。实验室由面壁智能联席首席科学家、清华大学人工智能学院助理教授姚远领衔。 在 MiniCPM-V 4.7 到来后,姚远认为,我们已经来到了 「端侧智能的撞线前夜」 ,而端侧智能的未来,会更加不可思议。 「2 年内 GPT-6 (级别的智能)到手机上,我们觉得是没什么问题的」。 端侧智能的「三驾马车」: 模型、硬件与 Infra MiniCPM-V 4.7 35B-A3B 是 全球首个可在端侧无损、流畅运行的开源 MoE 多模态大模型 。而 1B 版本则延续
Related stories
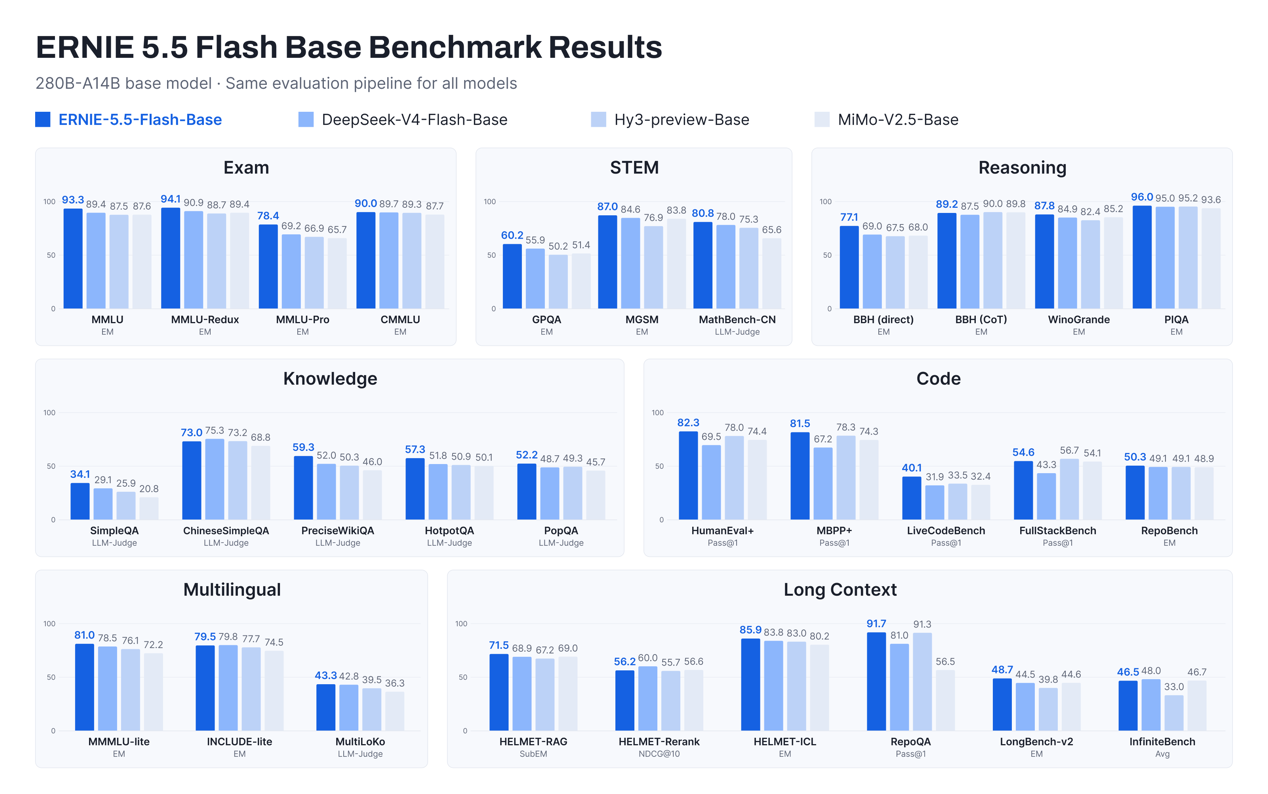
Baidu open-sources ERNIE 5.5 Flash Base, 280B MoE model with 14B active parameters
On November 5, Baidu open-sourced ERNIE 5.5 Flash Base, a sparse MoE language model with 280B total parameters and 14B active per token, pretrained on 33.5T tokens with up to 128K training context and 1M-token context for fine-tuning and inference. The company claims SOTA results among same-size models on benchmarks covering knowledge, reasoning, math, code, multilingual, and long-context tasks, surpassing DeepSeek-V4-Flash-Base, Hy3-preview-Base, and MiMo-V2.5-Base. The release includes weights on Hugging Face and ecosystem support with vLLM and SGLang.
3 reports · 2 sources
Tsinghua and Qujing Introduce KTransformers-FineTune for CPU-GPU MoE Fine-Tuning
Tsinghua University's MADSys lab and Qujing Technology, with LlamaFactory, introduced KTransformers-FineTune (KT-FT), a CPU-GPU co-computation method for fine-tuning mixture-of-experts (MoE) models. It claims 2.5-21.2x throughput gains over traditional offloading by having the CPU compute expert weights directly instead of transferring them to the GPU. The approach includes a semantic-aware proactive layout engine and dynamic thread scheduling for routing skew, and is fully open-sourced.
1 reports · 1 sources
Meta releases Muse Spark Open, an 816B-parameter open-weight model optimized for Apple silicon
Meta released Muse Spark Open, an open-weight multimodal mixture-of-experts model with 816B total and 42B active parameters and a 1M-token context window, claiming it is the most capable US open-weight model. Optimized for Apple silicon via MLX, it can run locally on two M5 Ultra Mac Studios, with day-0 support from vLLM and other inference engines.

Moonshot unveils Kimi K3.1 Pro, 3T open-weight model with 1M context, weights due Nov 4
Moonshot AI announced Kimi K3.1 Pro, a 3-trillion-parameter open-weight reasoning model with a 1M-token context window, alongside a faster Highspeed variant. Full weights are promised by November 4, 2026. The model scores 55 on the Artificial Analysis Intelligence Index, ranking 4th overall and first among open-weight models, with API pricing at $2/M input and $10/M output tokens.
6 reports · 4 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe