Thinking Machines Lab debuts Inkling 2 Small, 594B-param MoE; weights due next week
Thinking Machines Lab introduced Inkling 2 Small, a mixture-of-experts model with 594B total and 17B active parameters, initially available as a proprietary model via its Tinker platform and Tinker Playground. The company plans to release the weights next week after safety testing. Artificial Analysis reports the model matches Gemini 3.8 Flash (high) in its index and would be the top open model outside China once weights are released.
Coverage timeline
Techmeme
Thinking Machines Lab : Thinking Machines Lab debuts Inkling 2 Small, a MoE model with 594B total and 17B active parameters, and plans to release weights next week after safety testing — {"selector":"[data-shape]","layers":[{" nodes":[22, 33,24,44,35,46],"edges":[[22,33],[33, 44],[24,33],[24,35],[35,44],[35, 46]] …

Artificial Analysis : Artificial Analysis says Inkling 2 Small matches Gemini 3.8 Flash (high) in its index and would be the top open model outside China once its weights are out — Inkling 2 Small is launching as a proprietary model, available first-party through Thinking Machines' Tinker platform and Tinker Playground …

Related stories
Mistral releases open weights for 1T-parameter Le Chonk model
Mistral AI has released the open weights for Mistral Large 4, also known as Le Chonk, a 1-trillion-parameter multimodal model trained in Europe. The company claims it is the best open-weight model for coding and rivals top open models like GLM-5.3 on the Artificial Analysis Coding Agent Index. The model is now available on the Hugging Face platform, and Mistral says its open nature gives organizations control over cyber defenses that closed models cannot offer.
4 reports · 4 sources1709 points · 438 comments
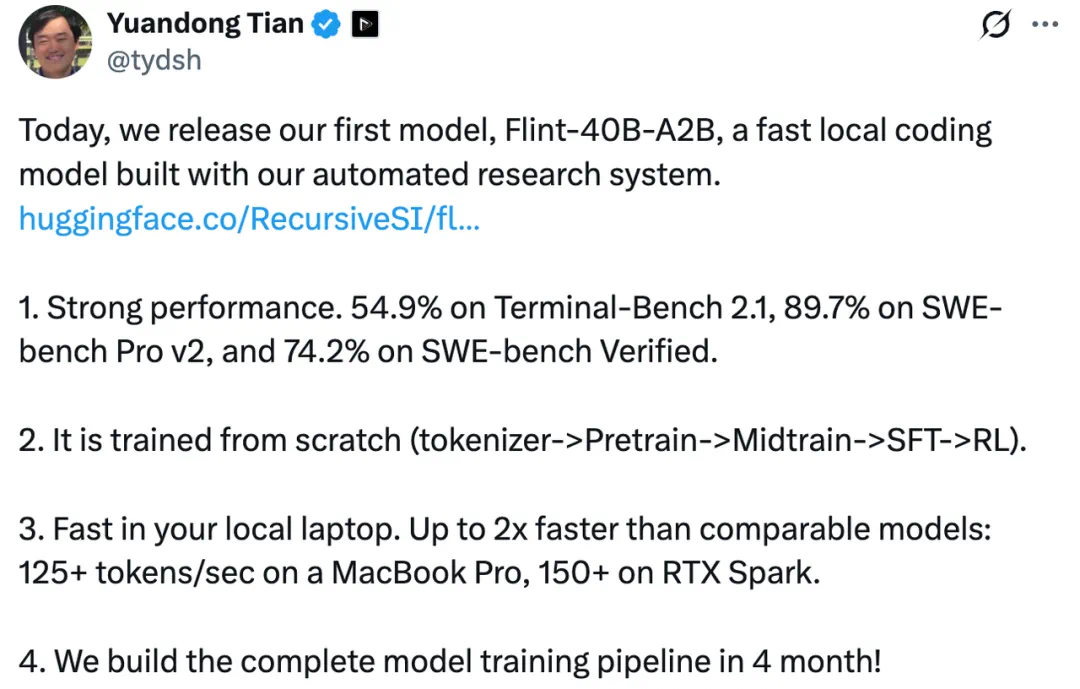
Recursive releases Flint, 40B coding model built largely by its Eureka Machine AI system
Startup Recursive has released Flint, an open-weight, 40B-parameter mixture-of-experts coding model with 2.5B active parameters per token, built in under four months with heavy automation from its Eureka Machine AI research system. The model outperforms sub-50B MoE models on coding benchmarks like SWE-Bench Pro v2 and runs at over 125 tokens per second on a MacBook Pro M4 Pro, with weights available on Hugging Face under Apache 2.0.
3 reports · 3 sources
Meta releases Muse Spark Open, an 816B-parameter open-weight model optimized for Apple silicon
Meta released Muse Spark Open, an open-weight multimodal mixture-of-experts model with 816B total and 42B active parameters and a 1M-token context window, claiming it is the most capable US open-weight model. Optimized for Apple silicon via MLX, it can run locally on two M5 Ultra Mac Studios, with day-0 support from vLLM and other inference engines.

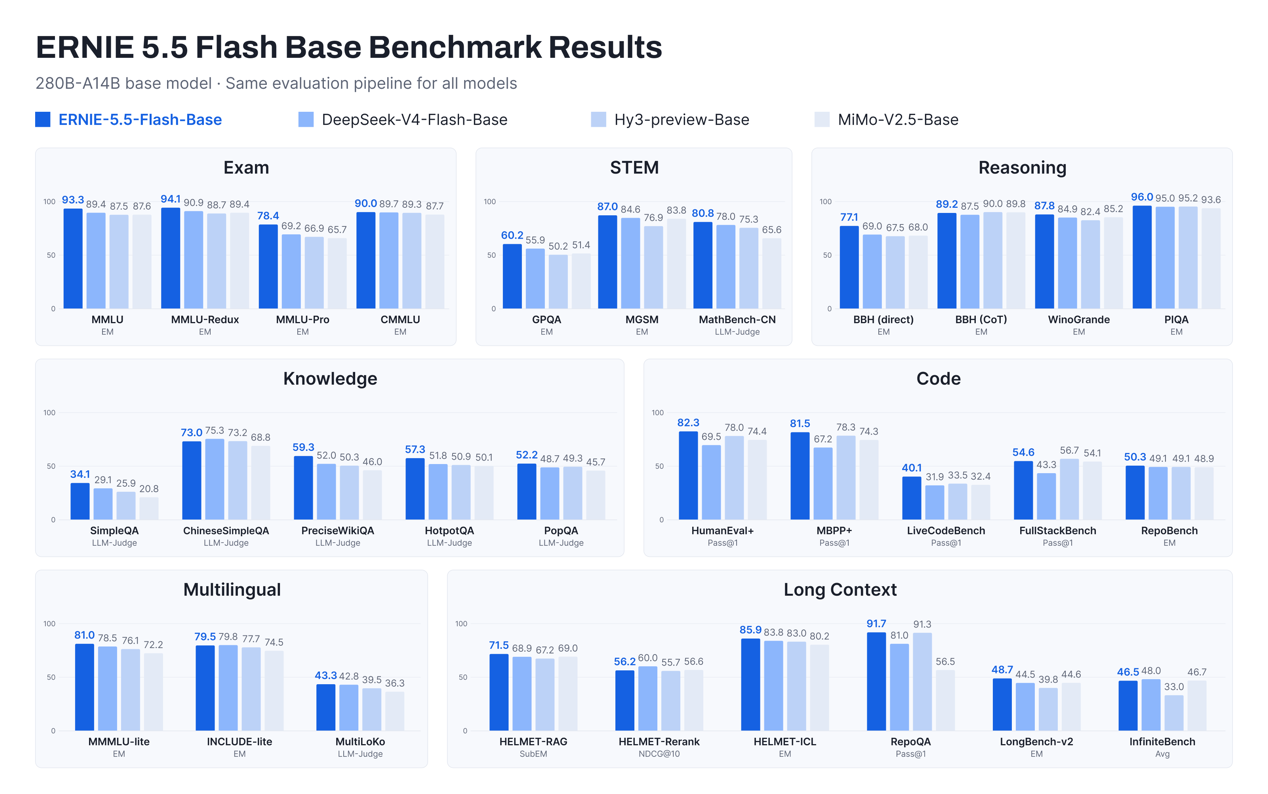
Baidu open-sources ERNIE 5.5 Flash Base, 280B MoE model with 14B active parameters
On November 5, Baidu open-sourced ERNIE 5.5 Flash Base, a sparse MoE language model with 280B total parameters and 14B active per token, pretrained on 33.5T tokens with up to 128K training context and 1M-token context for fine-tuning and inference. The company claims SOTA results among same-size models on benchmarks covering knowledge, reasoning, math, code, multilingual, and long-context tasks, surpassing DeepSeek-V4-Flash-Base, Hy3-preview-Base, and MiMo-V2.5-Base. The release includes weights on Hugging Face and ecosystem support with vLLM and SGLang.
3 reports · 2 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe