ByteDance Seed and collaborators propose three benchmarks for self-developing AI agents
Researchers from ByteDance Seed, TokenWave, and others introduced three new benchmarks—ASPIRE, S³Gym, and HarnessDev—to study how AI agents can self-develop from vague goals, as detailed in a research blog and papers. ASPIRE focuses on learning from ambiguous objectives, S³Gym on learning from experience, and HarnessDev on whether harness improvements persist. The work addresses gaps in recursive self-improvement, where current setups often rely on external verifiers.
Coverage timeline
机器之心机器之心
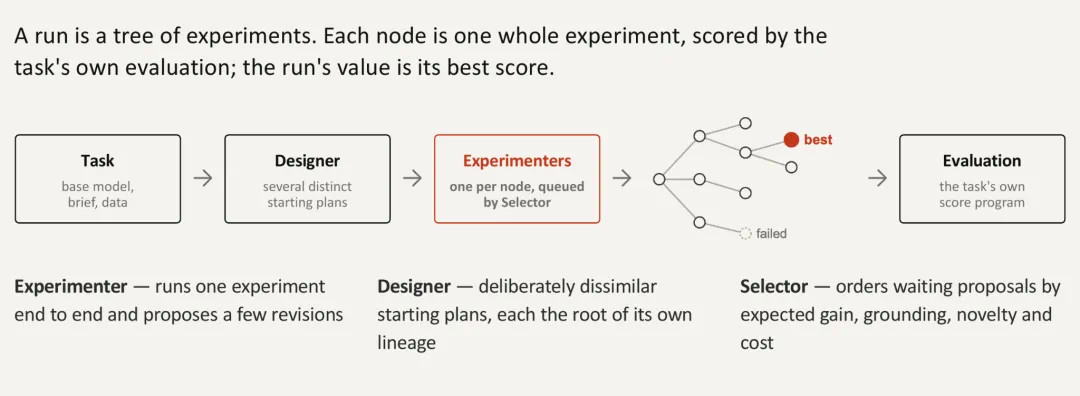
从模糊目标中找到正确的方向,并在这种场景下自我进化。Self-Developing Agents 用三项基准研究这个过程。 人学习一项新工作时,往往没有现成的题库和评分标准。比如,想成为更好的物理学家,需要根据个人当前水平,决定该补哪些数学知识、学习什么新的物理理论,或掌握哪种实验方法。让 AI 像这样学习,是字节跳动 Seed、TokenWave 等机构研究者在 Self-Developing Agents 项目 Blog 中提出的研究方向。团队希望 Agent 能在工作中逐步胜任一个角色,并将反复处理实际问题的经验积累成可复用能力。 这也是递归式自我改进(Recursive Self-Improvement,RSI)需要真正补上的一部分。当前常见的一些设定,其实并不是真正的 RSI——「半环 RSI」:假设有一个可靠的 Golden Verifier,持续判断结果、指引改进方向。Agent 可以沿着反馈优化,但学习目标和判断依据已经由外部准备好了。而更完整的闭环还要处理前面的判断和后面的积累。迭代过程中,宽泛目标需要变成具体行动(train or harness 修改),不完整的反馈需要变成可用经验,经过验证的改动需要进入模型、记忆或执行系统,以继续迭代后续工作。ASPIRE、S³Gym 和 HarnessDev 分别研究其中的三个问题:Agent 应该如何从模糊目标中学习,能否从经验中学习,以及 Harness 改进能否保留下来。 ASPIRE:从模糊目标中找到该学的东西 论文:https://arxiv.org/abs/2608.31111 项目与 Blog:https://self-developing-agents.github.io/ 「提高某套数学测试的分数」已经给出了明确的优化对象。相比之下,「提高数学推理能力」则留下了更多的决策点和空间:先补哪一类短板,找什么数据,用什么方法训练,又怎样检查训练有没有用。 ASPIRE 从后一种目标出发。Agent 只能看到自然语言描述的能力方向,学习材料、更新方法和验证方式都要自己选择。研究者用覆盖多类能力的专家原创题检查这些选择的效果,题目、答案和逐题反馈不向 Agent 开放。它包含 6 个能力目标、520 道专家编写的隐藏评测题,以及一个支持权重和 Harness 更新的最小交互环境。它还提供
Related stories
VisInteract: Interactive Text-to-Visualization for Imperfect Queries, NeurIPS 2026 Spotlight
Researchers from Hong Kong Polytechnic University and ByteDance propose VisInteract, a new paradigm for dynamic interactive text-to-visualization that handles imperfect user queries. They introduce VisInteract-Bench, a benchmark acknowledging ambiguous, incomplete, or erroneous inputs, and Vis-MCTS, a Monte Carlo tree search-based method that branches and backtracks between data retrieval, chart generation, and clarification. The work was accepted as a Spotlight paper at NeurIPS 2026 (292 out of 30,709 submissions).
1 reports · 1 sources
Google Researchers Propose RRSI to Curb Overfitting in Recursive Self-Improving Agents
Google researchers have introduced RRSI (Regularized Recursive Self-Improvement), a method that adds regularization to recursive self-improving agents to prevent overfitting. The approach targets harness evolution, where agents iteratively modify their own prompts, tool usage, and memory management based on a fixed set of tasks, which can lead to benchmark-specific fitting and evaluation noise chasing. The paper, code, and project page are available online.
AIBuildAI open-sources PostTrain Agent, tops PostTrainBench with 46.6 points
AIBuildAI released PostTrain Agent, an open-source recursive self-improving agent that autonomously performs LLM post-training, including algorithm design, data collection, coding, and experiments, without human intervention. On the PostTrainBench benchmark, it scored 46.6, ranking first among frontier models and agent systems, close to human expert performance (51.1). The team also open-sourced the code, knowledge base, and technical report.
ModularRSI: Frozen-Weight Agents Improve via Harness Self-Modification
IQuest Research, with Beihang University and the University of Manchester, released ModularRSI, a method for agent continuous self-improvement that modifies the execution harness while keeping the base model frozen. On Terminal-Bench 2.0, accuracy rose from 47.57 to 52.43 through harness evolution, with improvements transferring to unseen tasks, domains, and base models. The work defines an agent as A=(M,H), where H is the harness controlling environment observation, context maintenance, tool invocation, failure recovery, and task termination.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe