vLLM Blog Details Multi-Node DSpark Training for Kimi K3 on GB300 NVL72
The vLLM blog published a post describing how Speculators and Mooncake enabled multi-node DSpark training for Kimi K3 on GB300 NVL72 hardware. The post focuses on the technical mechanisms that facilitated this training setup.
Coverage timeline
vLLM BlogHelen Zhao, Fynn Schmitt-Ulms, Yuchen Fama, and Antonio Javier Fernandez Dominguez
How Speculators and Mooncake enabled multi-node DSpark training for Kimi K3.
Related stories
vLLM Blog Details Optimizations Behind 2.8x Throughput for Kimi K3 Serving
A vLLM blog post describes optimizations that achieve 2.8x throughput for serving Kimi K3, covering scheduling, KDA prefix caching, ReplaySSM state recovery, PD disaggregation and state offload, parallelism, MoE, and GPU kernels. The post details the technical approaches behind the performance gains.
vLLM-Omni and FastVideo Optimize MiniMax H3 Serving, Generate MP4 in 8.7s on Eight B300 GPUs
A technical post from vLLM-Omni and FastVideo describes system-level optimizations for serving MiniMax H3, a multimodal model that generates video with synchronized audio. The optimizations span the full resident pipeline, including attention and communication, fused DiT operators, parallel VAE decoding, compact output transfer, and parallel MP4 construction. FastVideo's FastH3 reduces 49 DiT forward passes to 4, achieving real-time full MP4 generation in 8.678–8.710 seconds on eight B300 GPUs for a 10.125-second clip.
2 reports · 2 sources
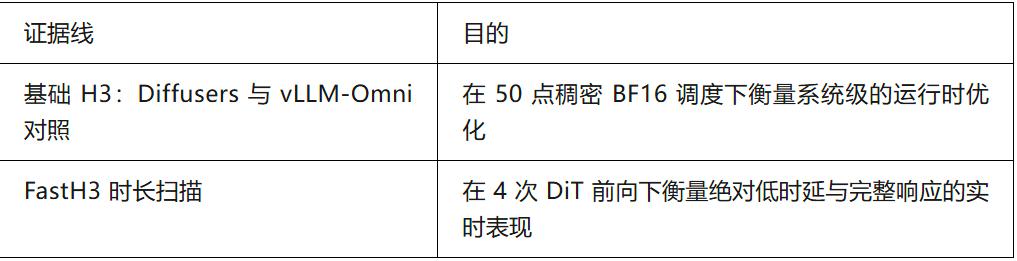
vLLM-Omni Optimizes MiniMax H3 Stack, Integrates FastH3 for Real-Time Serving
The vLLM blog describes how vLLM-Omni optimizes and scales the complete MiniMax H3 stack, integrating FastVideo's four-step FastH3 to achieve generation faster than playback. This enables real-time serving for the H3 model family.
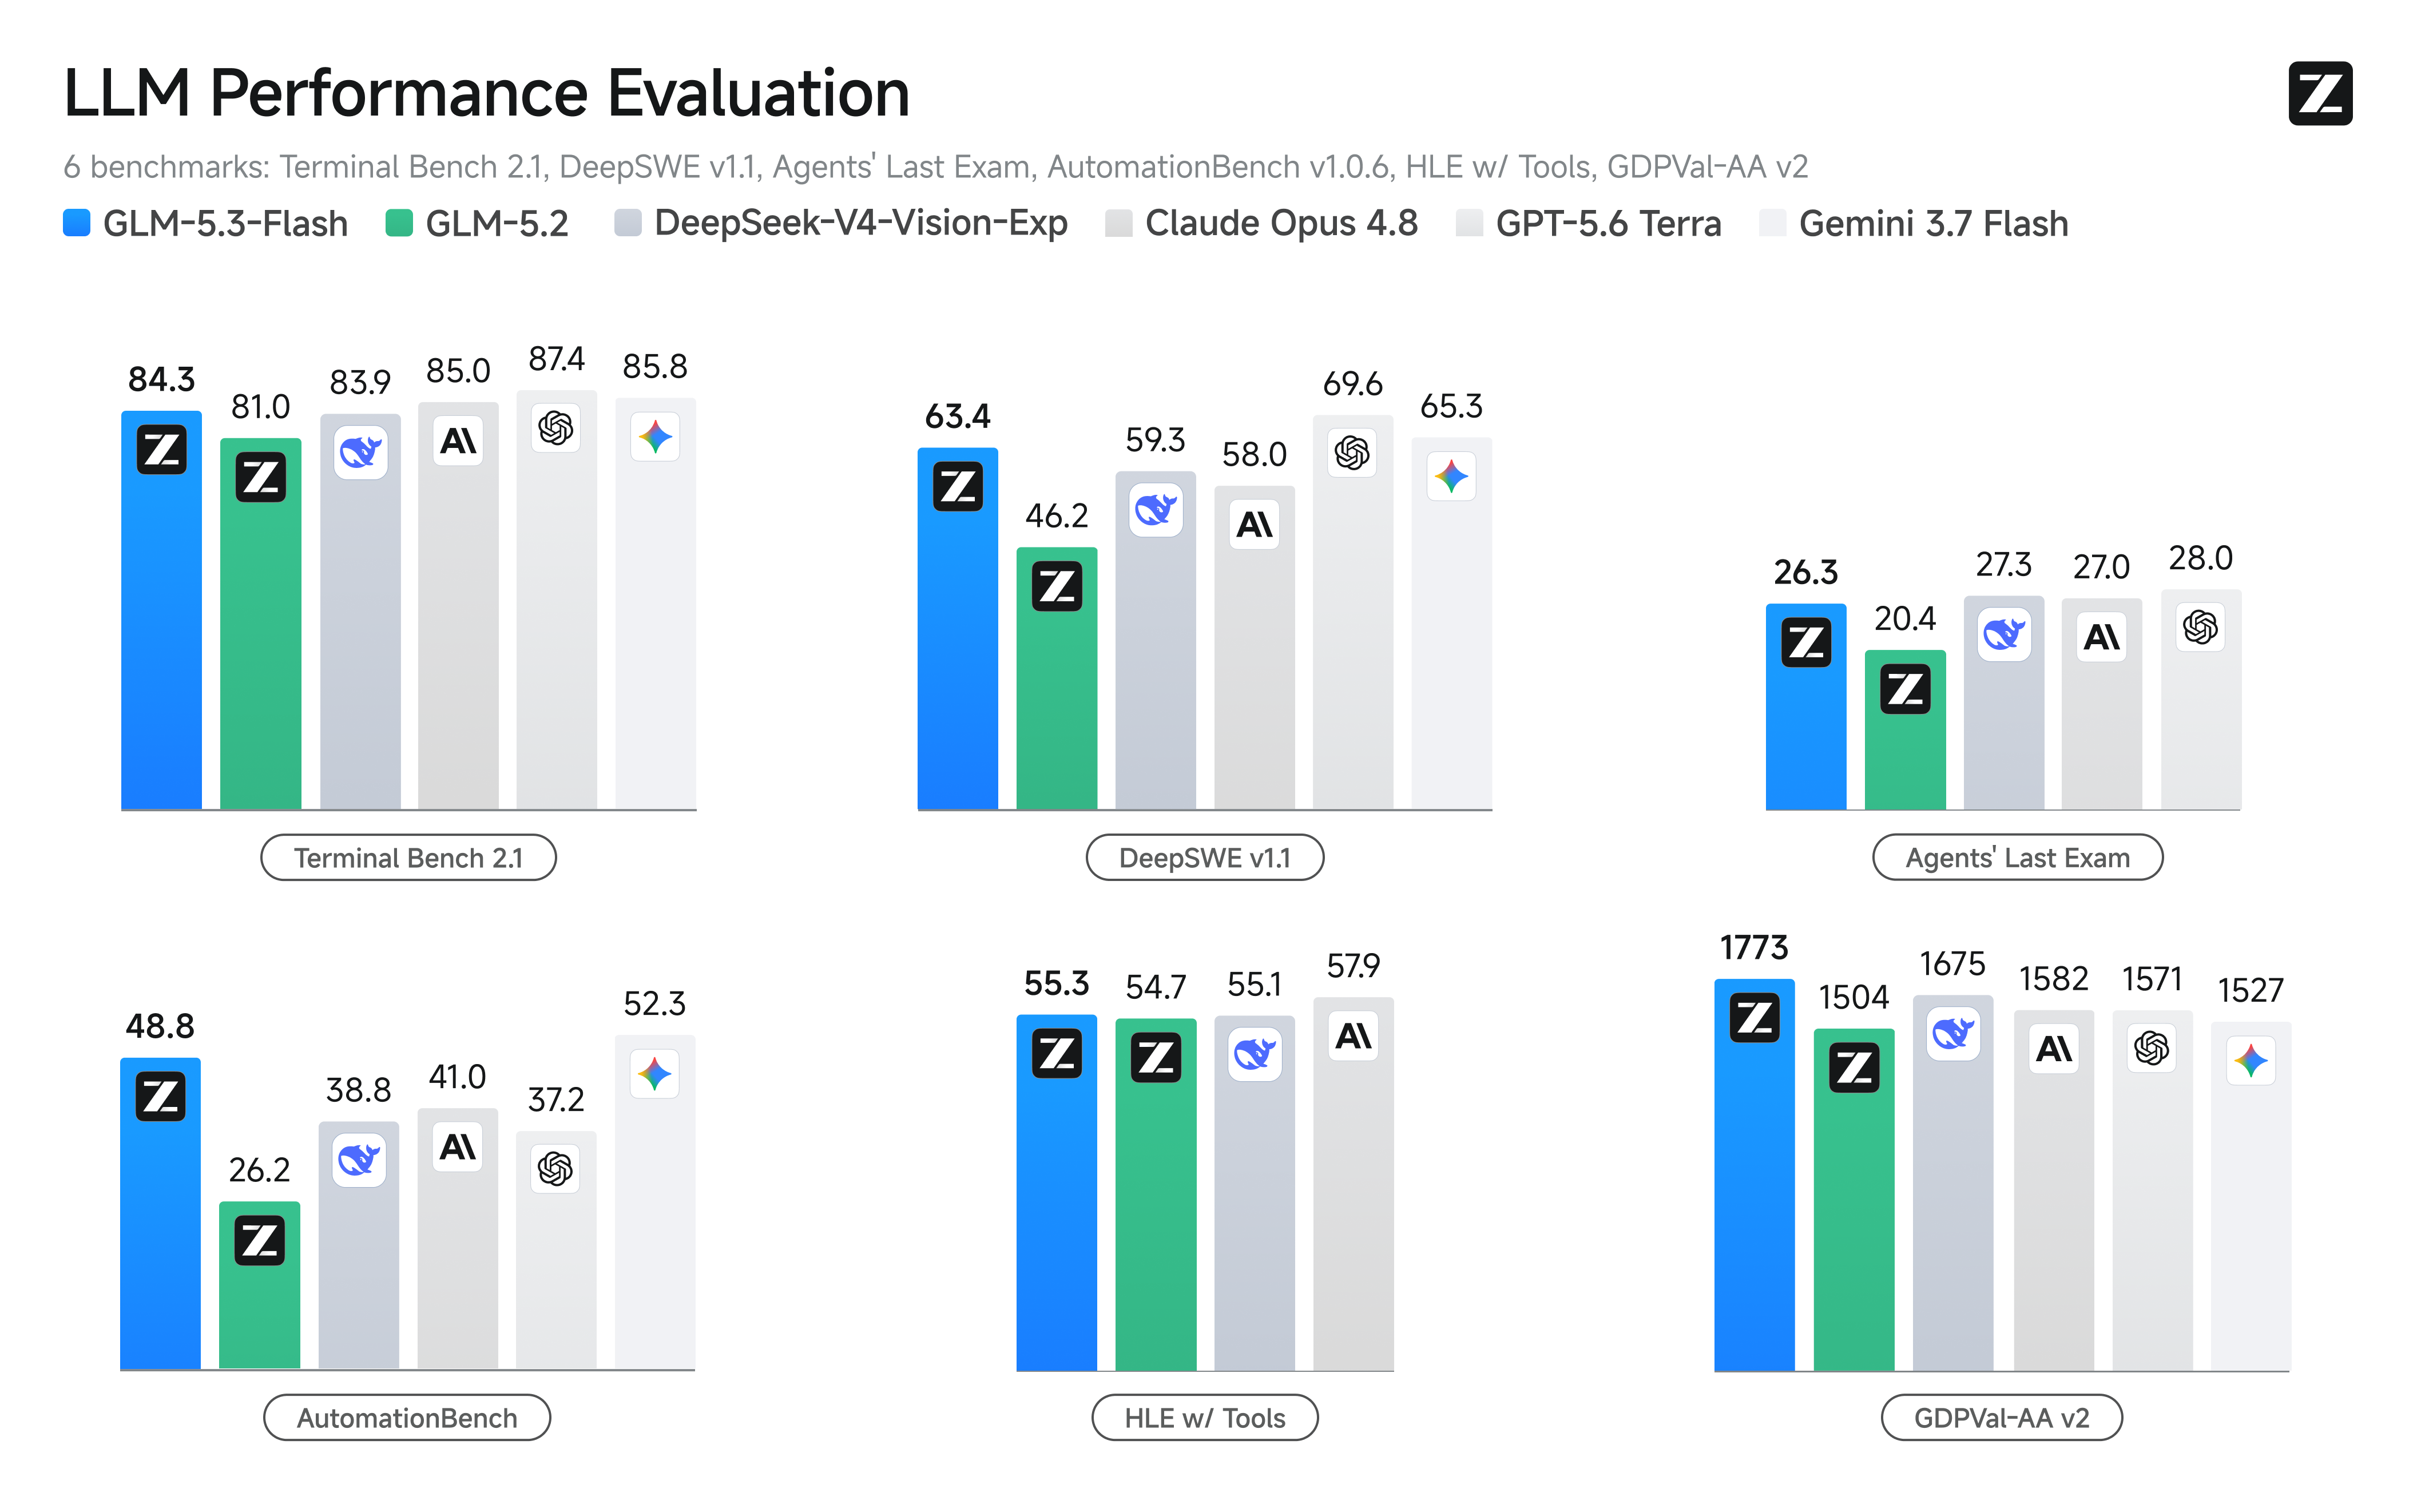
Zhipu AI open-sources GLM-5.3-Flash, a 320B multimodal model priced at 1/40 of Claude Opus 4.8
Zhipu AI released and open-sourced GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series, with 320B total parameters (18B active). It scores 57 on the Artificial Analysis Intelligence Index, matching Claude Opus 4.8, and is priced at one-tenth of GLM-5.3, or one-fortieth of Opus 4.8. The model uses a hybrid sparse and linear attention architecture, runs on domestic Chinese chips, and was tested anonymously as Ox-Alpha on OpenRouter and OpenCode.
8 reports · 5 sources1126 points · 573 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe