RunAnywhere open-sources TrnRT inference engine for AWS Trainium
RunAnywhere (YC W26) has open-sourced TrnRT (Trainium RunTime), an LLM inference engine for AWS Trainium. It currently serves two instances of GLM-5.3 flash (FP8) on a single trn2.48xlarge box with a cache-aware router, processing 3.57M tokens per minute on SemiAnalysis's AgentX benchmarks. The engine uses NKI kernels for decode, fusing blocks for sparse-attention layers, and aims to improve cost efficiency compared to H100/H200.
Coverage timeline
Hacker Newssanchitmonga22
Hi HN, Sanchit here from RunAnywhere (YC W26). We just open-sourced TrnRT: Trainium RunTime, our inference engine for AWS Trainium. We started 3 weeks back, and currently we’re able to serve and run GLM 5.3 flash (FP8) on AWS trn2.48xlarge, and will bring more models support soon. It’s open to contributions :) What it does today: - Serves 2 instances of GLM-5.3 flash on a single box, 8 trn2 with a cache aware router. - Can process 3.57M TPM (tokens per minute) on SemiAnalysis's AgentX benchmarks. - Runs decode as one NKI kernel per layer half, or for the 11 sparse-attention layers fuses both blocks into a single kernel, for faster performance. We started working on Trn2 because we wanted to explore it and see if we can come close to beating it’s performance in terms of cost efficiency compared to H100/H200. A big MoE with 1M context window such as GLM-5.3 flash requires a lot of memory, and memory/tb on a trn2.48xlarge costs less than half compared to 8x h200 on AWS, and hence we wante
Related stories
Ant Group and vLLM Community Open-Source Humming Kernel Library for Quantized Inference
Ant Group and the vLLM community have open-sourced Humming, a high-performance kernel library for quantized inference. It supports NVIDIA GPUs from Turing onward and CUDA-compatible devices like T-Head's Zhenwu 810E, with a unified architecture for diverse weight and activation formats. Humming reportedly outperforms existing implementations from vLLM Marlin, FlashInfer, and DeepGEMM on many workloads.
1 reports · 1 sources
Tencent releases Hy4 open-weight model, claims top-tier status, adds vision and computer use
Tencent released Hy4, its latest large language model, on November 4, 2026, claiming it joins the top tier of Chinese open-weight AI for the first time. Hy4 adds vision understanding and computer-use capabilities, with weights to be open-sourced soon and a Flash version planned. Following the release, Tencent announced a tenfold capacity expansion for WorkBuddy due to surging demand, and Hy4 ranked second among Chinese models on Artificial Analysis and first among open-source models on Agent Arena.
5 reports · 4 sources

Mistral releases open weights for 1T-parameter Le Chonk model
Mistral AI has released the open weights for Mistral Large 4, also known as Le Chonk, a 1-trillion-parameter multimodal model trained in Europe. The company claims it is the best open-weight model for coding and rivals top open models like GLM-5.3 on the Artificial Analysis Coding Agent Index. The model is now available on the Hugging Face platform, and Mistral says its open nature gives organizations control over cyber defenses that closed models cannot offer.
4 reports · 4 sources1709 points · 438 comments
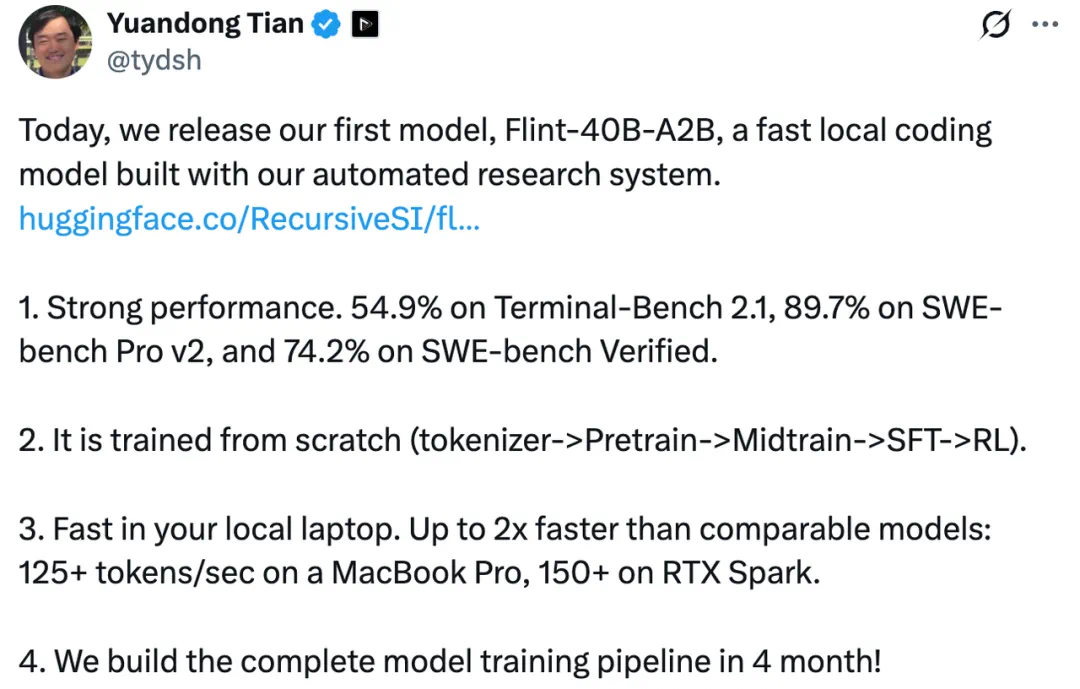
Recursive releases Flint, 40B coding model built largely by its Eureka Machine AI system
Startup Recursive has released Flint, an open-weight, 40B-parameter mixture-of-experts coding model with 2.5B active parameters per token, built in under four months with heavy automation from its Eureka Machine AI research system. The model outperforms sub-50B MoE models on coding benchmarks like SWE-Bench Pro v2 and runs at over 125 tokens per second on a MacBook Pro M4 Pro, with weights available on Hugging Face under Apache 2.0.
3 reports · 3 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe