Huawei plans Ascend 960DT Q1 2027, 960PR Q3 2027; says UnifiedBus key for next-gen AI systems
Huawei plans to launch its Ascend 960DT AI chip in Q1 2027 and the 960PR in Q3 2027, according to rotating chairman David Wang. The company says its UnifiedBus technology is central to next-generation large AI systems, as it competes with Nvidia and aims to close China's AI computing gap.
Coverage timeline
Techmeme
Reuters : Huawei plans to launch the Ascend 960DT AI chip in Q1 2027 and the 960PR in Q3 2027, and says its UnifiedBus tech is key to its next-generation large AI systems — Huawei Technologies (HWT.UL) will launch two new artificial-intelligence semiconductors in 2027, rotating chairman David Wang said on Thursday …

TechCrunch AIKate Park
Huawei is accelerating the launch of its next-generation Ascend 960DT AI chip as it pushes to compete with Nvidia and close China’s AI computing gap with the U.S.
量子位量子位
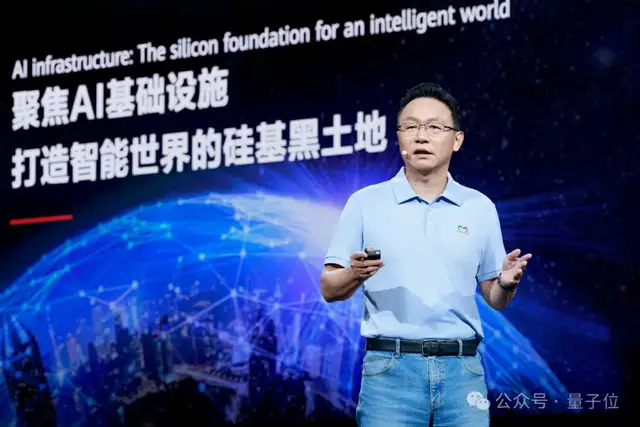
华为汪涛:华为要打造AI算力底座,只做好一颗芯片远远不够 梦瑶 2026-09-19 16:28:51 来源: 量子位 CANN跨过拐点,华为补上软件生态 乔不迟 发自 凹非寺 量子位 | 公众号 QbitAI 华为今年全联接大会,最重磅的首先是 一组芯片时间表 。 昇腾960DT研发进度比原计划 提前三个季度 ,单芯片算力实现倍增,960DT支持2 PFLOPS FP8、4 PFLOPS FP4,HBM容量最高288GB、带宽9.6TB/s。 对应的昇腾960超节点做到4096张NPU卡,最高8EFLOPS FP8算力、超过1PB HBM容量。 华为轮值董事长汪涛把后续路线一并摊开: 2028年昇腾970、2029年昇腾980,未来几年保持 “一年一代” 的演进节奏。 会后,汪涛接受量子位专访时把这个变化说得很直白: 从今年开始,950、960、970、980连续几代,未来几年我们坚持一年一代,走入了快速演进的节奏。这也是国内半导体制造、封装的上下游配套全部打通之后才实现的。 但华为这次想讲的,显然不只是一颗更快的芯片。 围绕960,华为把NPO光互联、超节点、CANN生态和韬定律一起摆上台面,给出的答案很明确: AI算力竞争已经越来越像一场系统工程。 单芯片倍增,但华为押注的是整套系统 先从这次核心的新产品说起——昇腾960。 相比上一代,960把算力、内存容量和带宽继续往上推,同时产品节奏明显加快。 按照华为披露,960DT比原计划提前三个季度准备就绪,960PR版本也将继续提前。 更值得注意的是昇腾芯片的 研发周期 。 汪涛专访时透露,960芯片已经在实验室测了好几个月。 “芯片从立项到产品化往往要三年,我们任何一次发布,都是产品已经在实验室反复测试、有准确交付时间之后才做。” 从950、960到后续的970、980,华为接下来几年计划保持一年一代快速演进的节奏。 AI大模型的训练和推理规模正在迅速扩大,单颗芯片再强,也很难独自承担万亿、十万亿参数模型的计算需求。 华为把突破口放到了“规模算力”上: 910C是384卡,950做到1024卡,960进一步扩到4096卡,并通过跨物理节点的统一内存编址,让多颗NPU互联起来更接近一台逻辑计算机。 汪涛提到,华为从仿真训练里看到,在同样十万卡集群下,4096卡超节点组成的集群相对传统八卡服务器组成的集群,MFU可
Related stories
Microsoft unveils Maia 300 AI chip, claims 40% more tokens per megawatt
Microsoft announced its third-generation in-house AI chip, the Maia 300, built on TSMC's N2P process node and designed as the primary AI inference system for its products and services. The company expects the chip to deliver 40% more tokens per megawatt compared to leading GPU-based systems, with production rollout starting in 2027. Maia 300 racks will hold 96 chips using about 167 kW, and Microsoft plans multi-gigawatt deployments starting next year.
3 reports · 2 sources

Ai2 details GPU scheduler using time budgets and fair-share allocation
Ai2 published a blog post explaining its new GPU scheduler design, which uses time budgets, fair-share allocation, and time-slicing to prioritize high-impact research. The scheduler aims to shorten queue waits and keep GPUs busy. Hugging Face also posted on the same topic, highlighting impactful scheduling strategies for GPU clusters.
2 reports · 2 sources
AMD CEO Su: chip supply to 'substantially increase' in 2027, needs more advanced wafer capacity
AMD CEO Lisa Su said the company plans to substantially increase chip supply in 2027 to meet booming demand, and needs more advanced wafer capacity. She made the remarks while meeting with Foxconn and TSMC, according to Reuters.
Google to launch satellite with four TPUs on SpaceX Falcon 9 on Oct 1 for Project Suncatcher
Google plans to launch an experimental satellite equipped with four Tensor Processing Units aboard a SpaceX Falcon 9 rocket on October 1, as part of Project Suncatcher, an initiative exploring orbital AI data centers. The satellite will operate for one year in low Earth orbit, with the mission measuring how the TPUs handle spaceflight stress, radiation, and thermal extremes.
2 reports · 2 sources

News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe