Hacker News Debates Claim That LLMs Are Superhuman at Reading and Writing Neural Network Weights
A Hacker News discussion critiques the assertion that large language models are superhuman at reading and writing neural network weights. Commenters argue that such claims are overstated and lack robust evidence, emphasizing the limitations of LLMs in this domain. The debate highlights skepticism within the AI community about LLM capabilities beyond text processing.
Coverage timeline
Hacker Newsagrm
Related stories
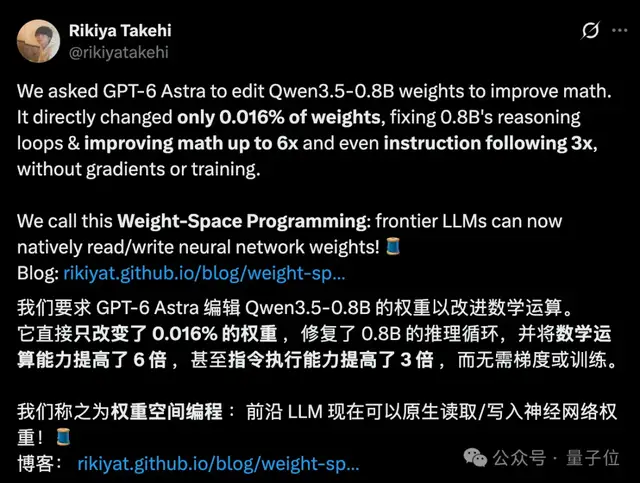
MIT: GPT-6 Astra edits Qwen weights, boosting MATH-500 from 7.9% to 48.1%
MIT CSAIL researchers demonstrated that GPT-6 Astra can directly read and edit the weights of Qwen3.5-0.8B, improving its MATH-500 score from 7.9% to 48.1% without training or gradient descent. The model modified only about 0.016% of parameters, also boosting instruction-following ability. The team named this capability Weight-Space Programming and showed Astra can also write neural network weights from scratch, outperforming a PPO baseline trained for 500 million steps.
4 reports · 4 sources2691 points · 813 comments
Essay Argues Against Using LLMs for Confidence Scoring
An essay published on Hacker News argues that using large language models for confidence scoring is a flawed practice, offering a technically substantive critique. The piece contends that LLMs are not well-suited to provide reliable confidence estimates, challenging a common approach in AI systems.
1 reports · 1 sources223 points · 102 comments
Ai2 benchmark shows LLM novelty judgments vary with evaluation setup
The Allen Institute for AI released a benchmark called Old Ideas, Novel Problems to test how reliably LLMs judge research-idea novelty. The findings show that small changes to the evaluation setup can produce very different verdicts on the same ideas.
1 reports · 1 sources
Goodfire researcher argues neural networks are largely interpretable, most neurons understandable
Nick Cammarata of Goodfire published an essay arguing that neural networks are far more interpretable than previously believed, with most neurons in models up to trillions of parameters understandable. He attributes polysemanticity in early models to fixable issues rather than superposition, and suggests mechanistic interpretability may be solved soon.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe