ByteDance releases Seedream 5.5 image model with faster generation, transparent assets
ByteDance released Seedream 5.5, an image generation model now live in Doubao, Doubao Work, and Jimeng, with API coming to Volcano Ark. The model offers faster generation, improved multi-round editing stability (maintaining pixel-level consistency outside edited regions over 100+ rounds), native RGBA transparent asset generation, and enhanced realism and small-text rendering. API pricing continues the two-part structure (input image + output image) with no text token fees; a 2K square image edit costs about 0.28 yuan, less than half of Seedream 5.0 Pro.
Coverage timeline
机器之心机器之心
11 月 9 日,字节跳动正式发布豆包图像创作模型 Seedream 5.5。相较上一代 Seedream 5.0 Pro,新模型的生成速度大幅提升,同时增强了多轮编辑稳定性,原生支持透明素材生成,并针对图像真实感和小字渲染方面做了重点优化,更好地满足了专业创作场景对质量、稳定性与效率的要求。 目前,豆包、豆包工作、即梦已同步接入Seedream 5.5,API 即将上线火山方舟。定价方面,Seedream 5.5 API 延续“输入图 + 输出图”两段计费结构,文本 Token 不产生费用。以2K方图编辑为例,单张成本在 0.28 元左右,不到 Seedream 5.0 Pro 一半。 在图像的多轮编辑方面,Seedream 5.5 的指令遵循能力更强,对非编辑区域实现了像素级的保持。在实测中,模型以每一轮的结果作为下一轮输入,连续完成上百轮修改后,指定编辑区域之外的主体特征、构图比例、光影风格仍然一致。 100轮修改之后,非编辑区域实现像素级保持 Seedream 5.5 原生支持 RGBA 透明素材的生成与拆分,可直接输出带 Alpha 通道的图像,并支持素材分层输出。除文生图外,创作者还可以通过参考图生成所需的透明素材,保留主体丰富形态与质感的同时,模型会准确处理轮廓边缘与透明区域,使其可作为设计资产跨场景复用,提高生产效率。 Seedream 5.5 原生支持透明素材生成 此外,Seedream 5.5 改善了写实场景中光照、材质与皮肤纹理的表现,减少了过度油亮、过曝的现象,生成结果更接近自然拍摄。在逆光人像、特效合成、多图融合等场景中,新增元素与原画面的空间关系、遮挡层次和光影过渡更为合理。 生成结果更接近自然拍摄 Seedream 5.5 的小字渲染效果同样有所提升,尤其是较小字号下的中文生成,笔画复杂的汉字结构仍清晰可辨,可用于信息图、知识图解等对文字精度要求较高的内容。 Seedream 5.5 正在全面融入专业级的视觉创作工作流。基于 MagicArena 平台的专项测试结果,Seedream 5.5 在电商、营销、影视、游戏、办公与服装设计六类场景下的可用率均比 Seedream 5.0 Pro 有明显提升。 图源:字节跳动 Seed官网 在电商营销中,用户可基于模型的多轮编辑能力,以较低成本产出同一模特的多种穿搭效果;在家装设计中,设计师可在
量子位量子位
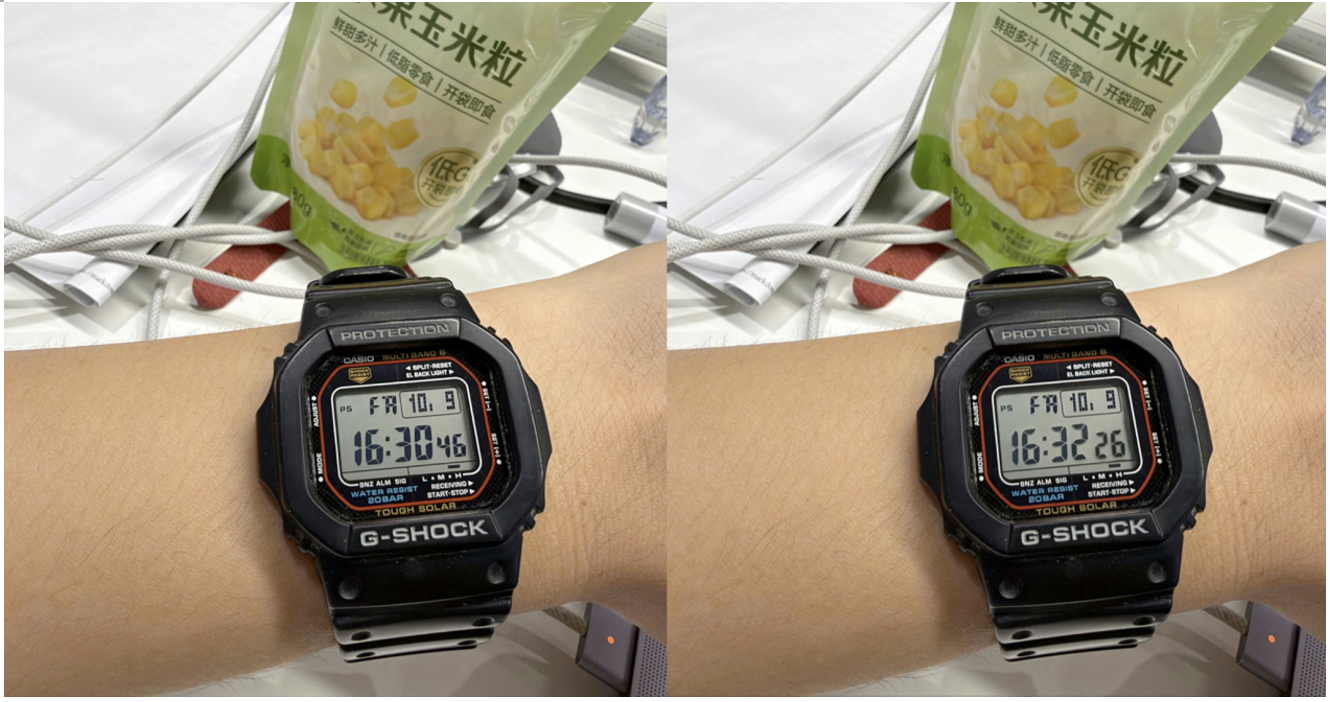
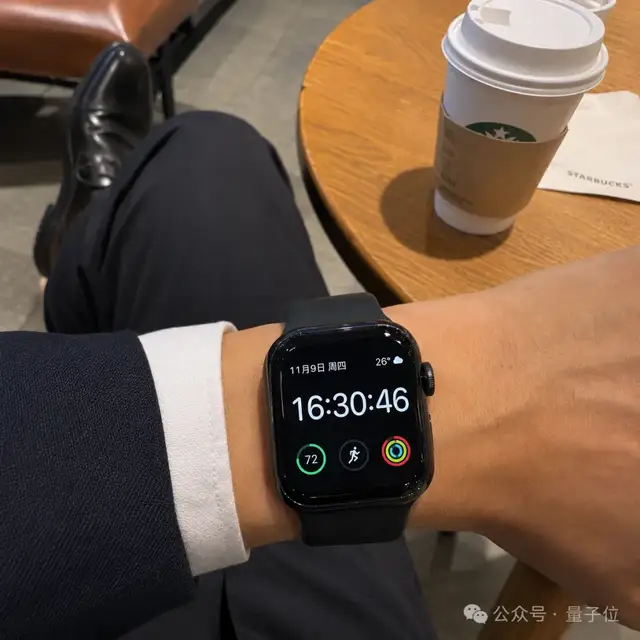
100轮图像编辑这道「毙刷题」,新出的Seedream 5.5稳上来了! 十三 2026-11-10 10:48:22 来源: 量子位 速度提了,API价格降了 金磊 发自 凹非寺 量子位 | 公众号 QbitAI 说真的,即便强如新出的 GPT-Image 2.6 ,遇到 连续编辑100轮图像 这种高压任务,也得大喊那句“名人名言”: 我画地为牢啊,厉娜! 例如我们先给Image 2.6输入下面这张原始图片: 然后再把包含100轮任务的提示词丢进去,每一轮就是让手表里的时间 增加1秒钟 ,并且把 上一轮生成的图片作为下一轮的输入 : 但看似非常简单的任务,Image 2.6生成的结果却是这样的(为了方便看变化,我们把100张图做成了一个视频)…… 视频地址: https://mp.weixin.qq.com/s/_OgVL6s3PIguqFN-WN1mhQ 可以明显地看到,其实在 第10轮 左右,原始图片就开始发生了 畸变 ,而且越往后,图片失真程度就越严重。 这要是放到真实工作场景里,那简直就是大大大大麻烦了。 But!!! 一个新出的 国产生图AI ,却 能hold住 这个高压任务!来看下结果: 视频地址: https://mp.weixin.qq.com/s/_OgVL6s3PIguqFN-WN1mhQ 虽然在后期的轮数中,依旧是存在一些畸变的情况,但整体却要比Image 2.6要保真得不少。 而这个新国产生图AI,正是来自字节的 Seedream 5.5 。 上面的任务,便是在 豆包 里调用新模型来执行的。 不过,100轮编辑不崩,还只是Seedream 5.5这次更新的一隅。整体看下来,它的亮点还包括: 真实感提升: 人物、材质和光影更像真实拍摄的,几张图拼在一起也不容易穿帮; 小字与多语言渲染: 海报、标签、信息图里的字基本不会写错,还支持多种语言; 透明图生成与编辑: 能直出透明底的图(PNG),省掉繁琐的抠图;也能把成图拆回图层,单独改文案、出不同语言的版本。 不仅如此,Seedream 5.5现在生成的速度也比之前的版本要快上不少;与此同时,据官方信息,Seedream 5.5 API延续“输入图 + 输出图”两段计费结构,文本 Token 不产生费用。以2K方图编辑为例,单张成本在 0.28 元左右,不到 Seedream 5.0 Pro 一半
Related stories
OpenAI launches Images 2.6 with GIF creation, faster generation, and new API controls
OpenAI has released Images 2.6, now available across ChatGPT, Codex, and the API. The update introduces native GIF creation from prompts or photos, with options to adjust animation speed and edit individual frames, alongside a claimed 50% faster image generation. The API also adds two sub-models, Flare and Sunburst, and separates complexity and quality parameters for more efficient multi-round editing.
5 reports · 5 sources384 points · 238 comments

ByteDance's Doubao Work Opens Third-Party Model Configuration to Enterprise Customers
ByteDance's Doubao Work (豆包工作) today enabled enterprise customers to configure third-party large models, initially integrating Kimi 3.1 Pro, GLM 5.3, and DeepSeek V4.1 Flash. The feature is available to team subscription and enterprise subscription customers, enabled by default, with usage deducted from existing AI points and no additional procurement required.
Baidu open-sources ERNIE 5.5 Flash Base, 280B MoE model with 14B active parameters
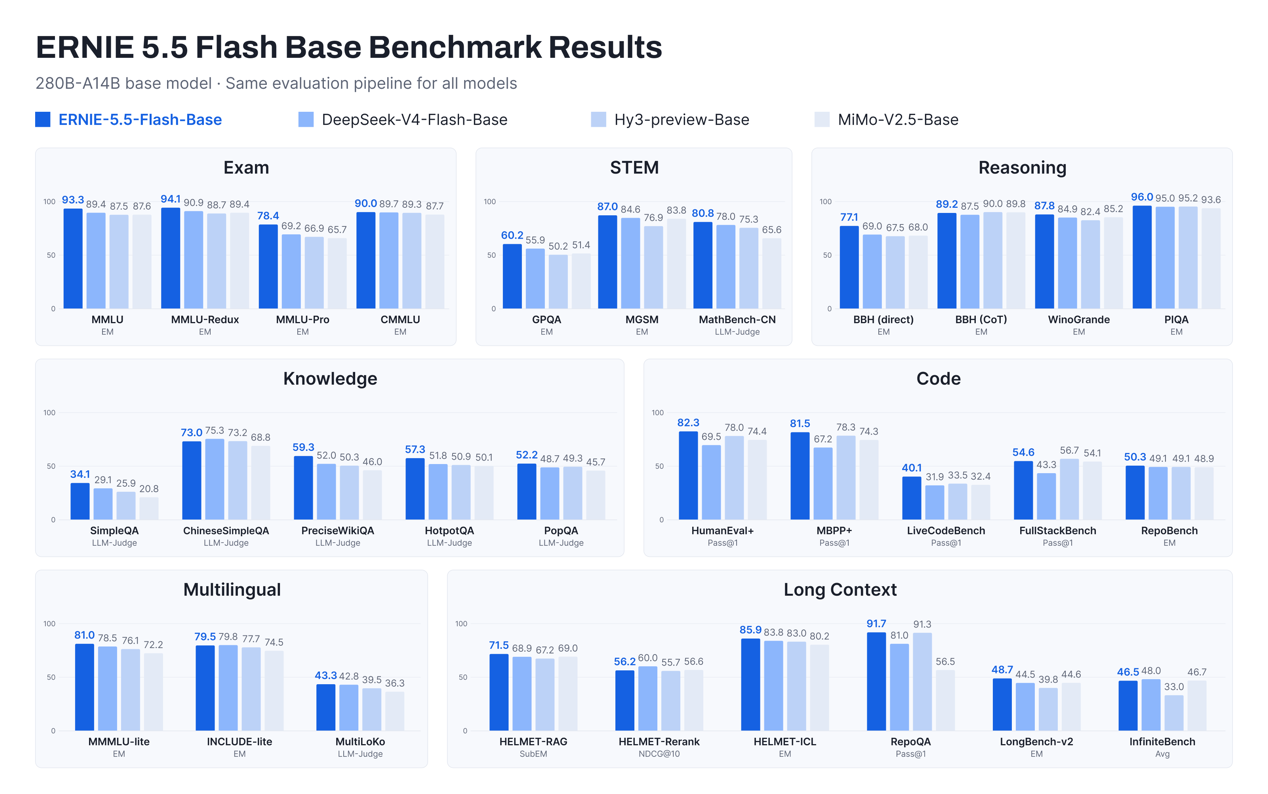
On November 5, Baidu open-sourced ERNIE 5.5 Flash Base, a sparse MoE language model with 280B total parameters and 14B active per token, pretrained on 33.5T tokens with up to 128K training context and 1M-token context for fine-tuning and inference. The company claims SOTA results among same-size models on benchmarks covering knowledge, reasoning, math, code, multilingual, and long-context tasks, surpassing DeepSeek-V4-Flash-Base, Hy3-preview-Base, and MiMo-V2.5-Base. The release includes weights on Hugging Face and ecosystem support with vLLM and SGLang.
3 reports · 2 sources
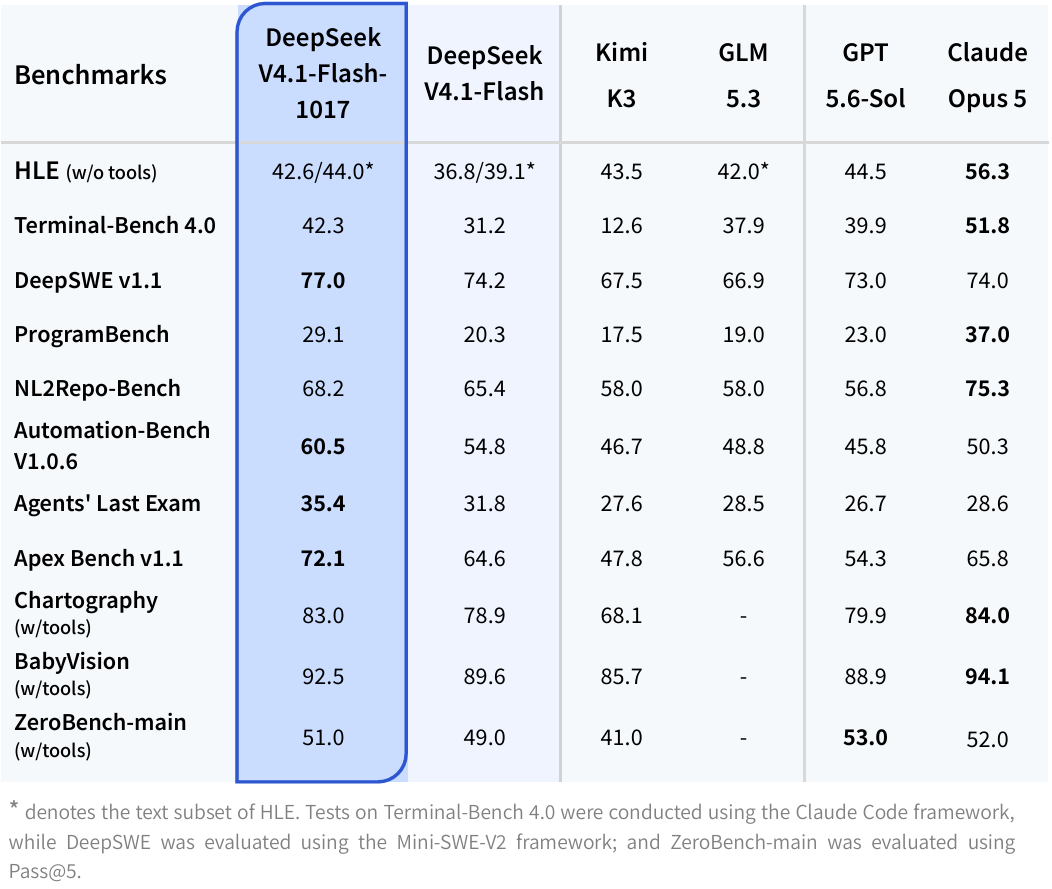
DeepSeek releases V4.1-Flash-1017 open-weight model with faster, cheaper agent tasks
DeepSeek released V4.1-Flash-1017, an open-weight model checkpoint with 763B parameters, now live on its website, app, and API. The update claims stronger benchmark performance, faster task completion, and shorter outputs than its predecessor, achieved via reinforcement learning with self-feedback for end-to-end project development. DeepSeek also opened its Search & Fetch APIs to everyone, priced at $0.75 per 1000 successful requests, and requires DeepSeek Harness v0.2.1-rc.1 or later for optimal use.
9 reports · 6 sources955 points · 717 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe