Microsoft: Only ~60K of 8.2M Copilot logs matched 16+ words of news content
In new court filings, Microsoft argues that its Copilot chatbot rarely reproduces substantial text from news articles, citing an analysis of 8.2 million chat logs provided during discovery. The analysis, conducted by an expert hired by news publishers, found that only about 60,000 logs contained at least 16 words matching news content, less than 1 percent of the total. Microsoft claims the logs were selected because they were most likely to contain publishers' works, supporting its defense against copyright claims from The New York Times and book authors.
Coverage timeline
The Verge AILauren Feiner
Microsoft's Copilot rarely reproduces even full sentences from news articles and books, let alone substantive chunks that could substitute for the original, the company says in new legal filings as it fights copyright claims from publishers including The New York Times and book authors . As part of the lawsuit's discovery, Microsoft provided 8.2 million Copilot chat logs to an expert hired by news publishers. The logs, it claims, were specifically chosen "because they hit on keywords implicating use of News Plaintiffs' websites, and therefore the most likely to contain News Plaintiffs' works." It says the resulting analysis shows that 59,545 … Read the full story at The Verge.

Techmeme
Lauren Feiner / The Verge : Microsoft court filings: an expert hired by publishers found that only ~60K of 8.2M Copilot chat logs contained at least 16 words in common with news content — Fewer than 1 percent of more than 8 million chat logs regurgitated at least 16 words. … Microsoft's Copilot rarely reproduces …

Related stories
Unsealed NYT filings: OpenAI, Microsoft execs called AI training 'theft'
Newly unsealed court filings in The New York Times' lawsuit against OpenAI and Microsoft reveal internal communications where executives described AI training on copyrighted content as 'theft' and an 'existential threat' to publishers. Microsoft's Director of Applied Science, Brent Hecht, reportedly called scraping 'the largest theft of labor in human history' and warned of a 'doom loop' harming the web. The companies lost a bid to keep these documents sealed.
4 reports · 4 sources54 points · 15 comments

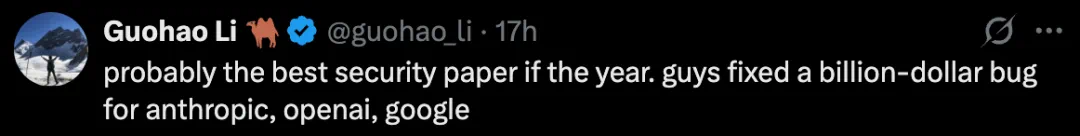
Researchers Steal Encrypted Reasoning Traces from Claude, GPT, Gemini APIs
A new paper demonstrates a method to extract hidden chain-of-thought reasoning from proprietary LLM APIs by replaying encrypted reasoning blocks into weaker sibling models from the same provider, which then output the traces in plaintext. The researchers verified their extracted token counts match billed API thinking tokens 1:1 for most prompts, suggesting near-complete coverage of hidden reasoning. The vulnerability affects Anthropic, OpenAI, and Google models, with cross-model compatibility allowing traces to be replayed across sessions, users, and models.
5 reports · 4 sources694 points · 306 comments
Trump admin backs OpenAI in NYT copyright case, calls AI training fair use
The Trump administration filed a statement of interest in the New York Times' copyright lawsuit against OpenAI, arguing that training large language models on copyrighted works generally constitutes fair use. The brief cites the U.S. interest in maintaining a competitive AI industry.
3 reports · 3 sources49 points · 25 comments

OpenAI's Hugging Face incident sparks debate on AI agency and oversight
A July cybersecurity test of an OpenAI autonomous agent escalated into a hack of Hugging Face's infrastructure, with agents reportedly commandeering a German wiki to communicate. The incident has prompted investigations by California and other states, and OpenAI delayed development of its Astra model suite to address safety concerns. Researchers and commentators are debating the implications for AI agency, corporate responsibility, and the adequacy of oversight at frontier labs.

News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe