vLLM Optimizes Agentic Serving, Claims 130K Tokens/GPU-s and Cost Edge Over Opus 5
A vLLM blog post details optimizations for agentic serving, including KV cache management, parallelism, scheduling, and P/D disaggregation. Benchmarked on SemiAnalysis AgentX, the optimizations achieve up to 130K tokens per GPU-second and a 14.6x-106x serving-cost advantage over Opus 5.
Coverage timeline
vLLM BlogvLLM Team and Inferact
How vLLM optimizes KV cache management, parallelism, scheduling, and P/D disaggregation for agentic workloads, validated on SemiAnalysis AgentX with up to 130K tokens per GPU-second and a 14.6x-106x serving-cost advantage over Opus 5.
Related stories
Mercury 2.5 LLM reported at 770 tokens/s, benchmarked by Artificial Analysis
According to a report on Hacker News dated September 23, 2026, the Mercury 2.5 LLM achieves a speed of 770 tokens per second. The performance figures come from Artificial Analysis, which also maintains an Intelligence Index (v4.3.2) incorporating ten evaluations, though the specific benchmark scores for Mercury 2.5 are not detailed in the source.
1 reports · 1 sources150 points · 92 comments
vLLM-Omni and FastVideo Optimize MiniMax H3 Serving, Generate MP4 in 8.7s on Eight B300 GPUs
A technical post from vLLM-Omni and FastVideo describes system-level optimizations for serving MiniMax H3, a multimodal model that generates video with synchronized audio. The optimizations span the full resident pipeline, including attention and communication, fused DiT operators, parallel VAE decoding, compact output transfer, and parallel MP4 construction. FastVideo's FastH3 reduces 49 DiT forward passes to 4, achieving real-time full MP4 generation in 8.678–8.710 seconds on eight B300 GPUs for a 10.125-second clip.
2 reports · 2 sources
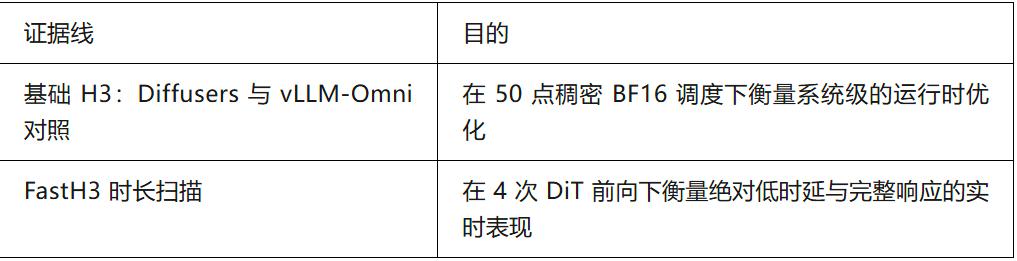
vLLM-Omni Optimizes MiniMax H3 Stack, Integrates FastH3 for Real-Time Serving
The vLLM blog describes how vLLM-Omni optimizes and scales the complete MiniMax H3 stack, integrating FastVideo's four-step FastH3 to achieve generation faster than playback. This enables real-time serving for the H3 model family.
vLLM-Omni Adds Distributed Layerwise Offload for 200B+ DiT Models
The vLLM blog announced distributed layerwise offload in vLLM-Omni, enabling efficient scaling of 200B+ parameter diffusion transformer (DiT) models across NPUs or GPUs. The feature includes flags to control weight sharding via AllGather, with usage examples for Cosmos3-Nano and Cosmos3-Super (64B parameters, 124 GB).
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe