Qwen 3.8 27B open-weight model runs on Cerebras at 1500 tokens/sec
Qwen 3.8 27B, a new open-weight model, is now available on Cerebras hardware, achieving a throughput of 1500 tokens per second. The deployment leverages Cerebras's specialized architecture to deliver high-speed inference for the model.
Coverage timeline
Hacker Newsaltertable
Related stories
Mercury 2.5 LLM reported at 770 tokens/s, benchmarked by Artificial Analysis
According to a report on Hacker News dated September 23, 2026, the Mercury 2.5 LLM achieves a speed of 770 tokens per second. The performance figures come from Artificial Analysis, which also maintains an Intelligence Index (v4.3.2) incorporating ten evaluations, though the specific benchmark scores for Mercury 2.5 are not detailed in the source.
1 reports · 1 sources150 points · 92 comments
Qwen3.8 27B quantization benchmark: 4-bit holds, 1-bit collapses
A Hacker News post benchmarks quantizations of the Qwen3.8 27B model, reporting that 4-bit quantization maintains performance well, while 1-bit quantization leads to a collapse in quality. The post provides practical data for researchers and engineers considering model compression.
1 reports · 1 sources284 points · 139 comments
Alibaba open-sources Qwen3.8-27B, a 27B multimodal dense model
Alibaba's Qwen team released the open-weights Qwen3.8-27B, a 27B-parameter native multimodal dense model under the Apache 2.0 license. It supports 262K native context (extendable to 1M tokens) and outperforms Qwen3.7-Plus in coding and office tasks, with independent benchmarks showing it matching GPT-5.6 Luna on the Artificial Analysis Intelligence Index. The model surpassed 1 million downloads within days of release.
11 reports · 4 sources1421 points · 788 comments
Alibaba open-sources Qwen3.8-2.4T-A95B MoE model with 2.4T total parameters
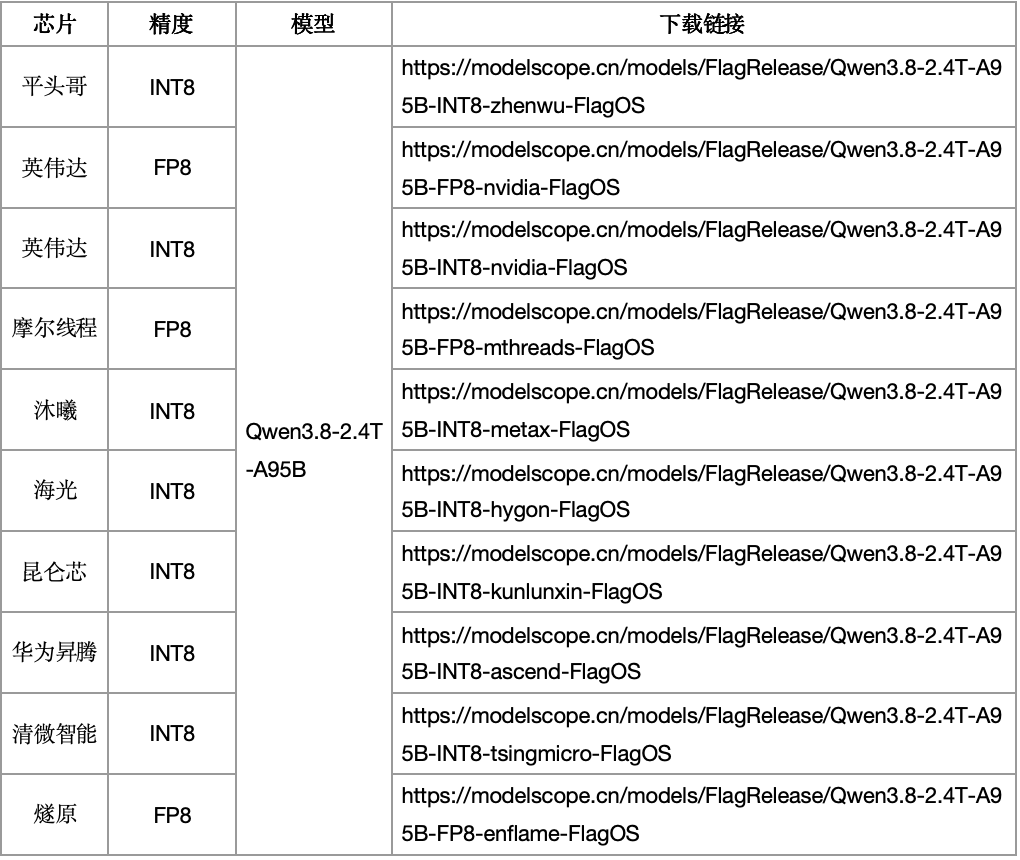
Alibaba has open-sourced Qwen3.8-2.4T-A95B, its largest and most capable open-source model, a text-only MoE with 2.4 trillion total parameters and 95 billion active parameters. The FlagOS community announced Day-0 adaptation across nine AI chip platforms, offering BF16, FP8, and INT8 versions with unified open-source stack support. The model supports 262,144-token native context, extendable to 1,010,000, and includes reasoning_effort and preserve_thinking settings.
3 reports · 2 sources710 points · 170 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe