Alibaba Qwen and OSU Propose TRACE to Speed Up FP4 RL Rollout by 5.4x
Alibaba Qwen and Ohio State University researchers proposed TRACE, a rollout-guided quantization-aware training method for FP4 reinforcement learning of mixture-of-experts (MoE) language models. By using the actual FP4 quantization results from the rollout side to guide rounding on the training side, TRACE reduces discrepancies between training and rollout paths, recovering performance close to BF16 while achieving up to 5.4x decoding throughput improvement in rollout with FP4 weights/activations and FP4 KV cache at 128K output length. The paper is available on arXiv and Hugging Face.
Coverage timeline
机器之心机器之心
大模型强化学习越来越「吃算力」,最昂贵的环节之一正是 Rollout。把 Rollout 从 BF16 压到 FP4,理论上可以显著降低计算和显存开销,但问题也随之而来 —— 训练端与 Rollout 端即使面对非常接近的数值,也可能因为 FP4 的离散量化边界而落到不同码点,最终把微小的数值误差放大成策略偏差导致训练崩溃。 阿里千问联合俄亥俄州立大学的研究团队提出了 TRACE。 它的核心思路并不是继续分别提高训练端和 Rollout 端的量化精度,而是直接减少两条低精度执行路径之间的差异:用 Rollout 侧真实的 FP4 量化结果,反过来指导训练侧的舍入方向。在 Qwen3.5-35B-A3B、Qwen3.5-122B-A10B、Qwen3.8-Flash-Next 以及 Qwen3.8-2.4T-A95B 四个 MoE 模型上,TRACE 可以在联合 FP4 W/A 与 FP4 KV Cache Rollout 的设置下,将最终性能拉回到 BF16 Rollout 附近,同时在 128K 输出长度下 rollout 获得最高 5.4× 的解码吞吐提升。 论文标题:TRACE: Rollout-Guided Quantization-Aware Training for FP4 Reinforcement Learning of MoE Language Models ArXiv 链接:https://arxiv.org/abs/2610.07767 Huggingface 链接:https://huggingface.co/papers/2610.07767 为什么 FP4 Rollout 会把 RL 训练「搞崩」? 低精度 Rollout 的吸引力很直接 :rollout 阶段通常占据 RL 大量时间,尤其当轨迹长度扩展到数万甚至数十万 token 时,低精度计算和低精度 KV Cache 能显著降低成本。相比 FP8,FP4 更激进,也意味着更大的潜在加速空间。 但 FP4 的问题也更尖锐 。现有方法通常关注「量化后的值离原始高精度值有多近」,也就是分别降低训练路径和 Rollout 路径的量化误差。TRACE 的作者指出,这并不等价于降低两条路径之间的差异。两个值都可以各自量得很准,却仍然被量化到不同码点。 图 1:微小的 BF16 差异
Related stories
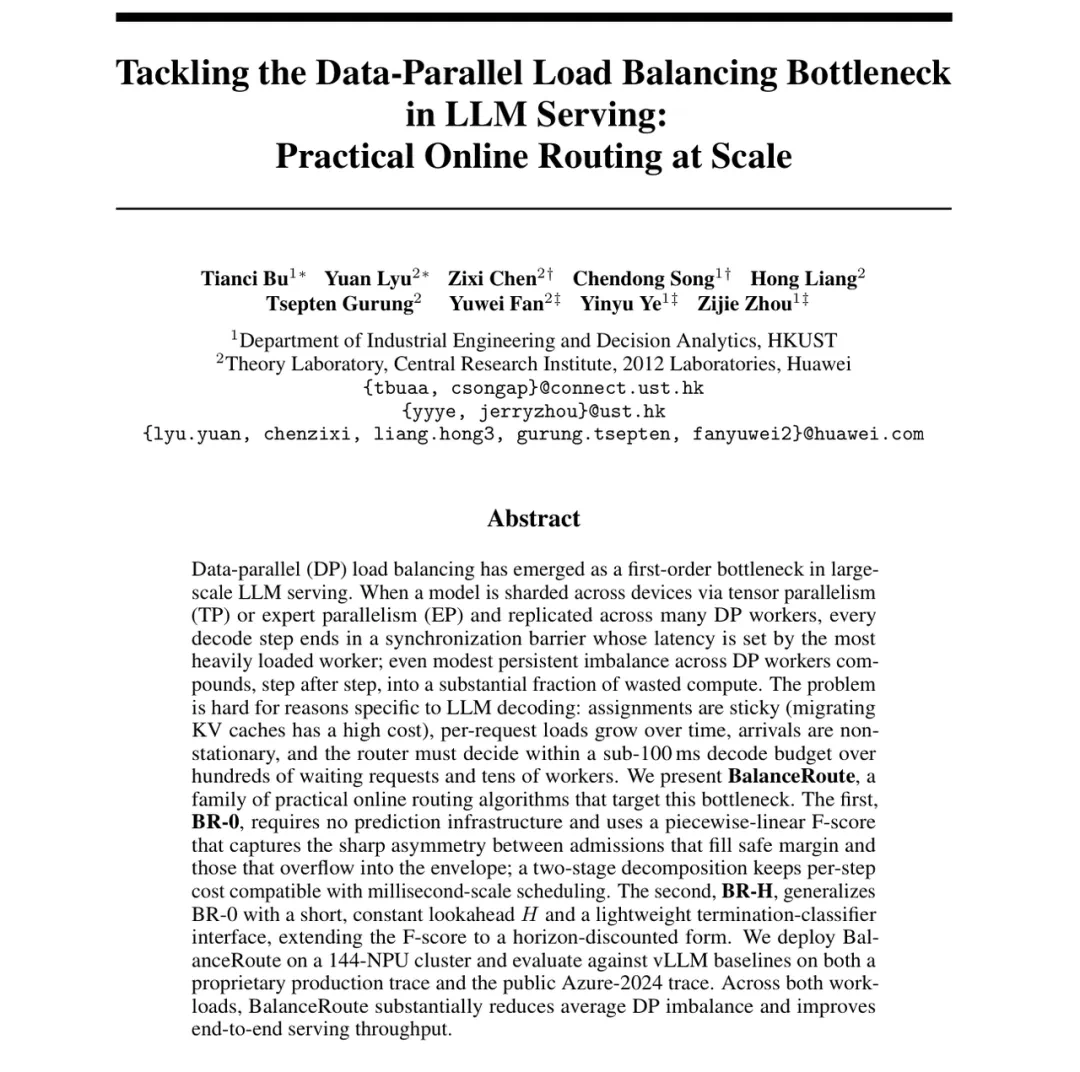
HKUST and Huawei propose BalanceRoute to cut MoE LLM serving load-balancing bottleneck
Researchers from HKUST and Huawei's 2012 Lab propose BalanceRoute, an online routing method that models synchronous waiting in MoE LLM serving and converts short-term load prediction into routing decisions. In a 96-GPU test, the predictor-based variant BR-H improves decode throughput by about 15% over the strongest baseline. The work is accepted by NeurIPS 2026 and deployed in the jointly built MaaS system MathBot-Pie.
1 reports · 1 sources
SparkDiffusion: Unified Sparse Attention, Distillation, FP8 Speeds Video Generation 265x
Researchers from Peking University, Tsinghua University, and Alibaba propose SparkDiffusion, a unified framework integrating sparse attention, few-step distillation, and FP8 quantization to accelerate video generation. It addresses the 'high-sparsity trap' where extreme sparsity (97%) degrades output quality despite falling training loss, using staged sparse warm-up and trajectory-mixed distillation. The system achieves 265x speedup, generating a 5-second 720P video in 18 seconds, with open weights and code.
Tsinghua and Qujing Introduce KTransformers-FineTune for CPU-GPU MoE Fine-Tuning
Tsinghua University's MADSys lab and Qujing Technology, with LlamaFactory, introduced KTransformers-FineTune (KT-FT), a CPU-GPU co-computation method for fine-tuning mixture-of-experts (MoE) models. It claims 2.5-21.2x throughput gains over traditional offloading by having the CPU compute expert weights directly instead of transferring them to the GPU. The approach includes a semantic-aware proactive layout engine and dynamic thread scheduling for routing skew, and is fully open-sourced.
Tsinghua, Infinigence-AI, SJTU Open-Source On-Device Inference Engine APXInf for Embodied Models
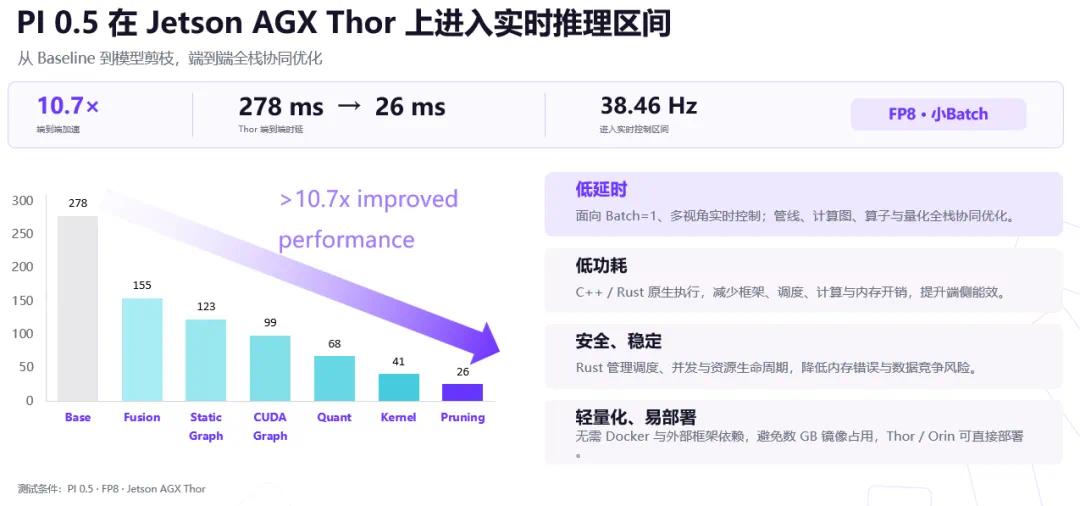
On September 15, Tsinghua University, Infinigence-AI, and Shanghai Jiao Tong University open-sourced APXInf, an on-device inference engine for embodied models. The engine reportedly achieves a 10.7x end-to-end speedup on robot hardware, reducing inference latency from 278ms to 26ms on Thor chips with FP8 configuration, enabling real-time control at 38.46Hz.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe