DiffusionART: Sample-Efficient Online Diffusion RL Speeds Up Video Post-Training 10x
Researchers from NUS, Kuaishou's Kling AI, and HKUST proposed DiffusionART, an online diffusion RL algorithm for image and video generation that supports ODE sampling, does not require differentiable reward models or extra tuning, and adapts to scalar and binary preference rewards. In experiments on HunyuanVideo-13B, DiffusionART reached the average reward level of DiffusionNFT and Flow-GRPO-Fast 12.02x and 11.72x faster, respectively. The paper topped Hugging Face Daily Papers on its release day.
Coverage timeline
机器之心机器之心
来自新加坡国立大学、可灵 AI 和香港科技大学的研究团队提出了 DiffusionART ,一种面向图像和视频生成的在线 Diffusion RL 算法。该方法支持采用 ODE 采样,不要求奖励模型可微,也无需额外调参,可自然适配标量奖励、二值偏好奖励等多种奖励形式,具有极高的样本效率。在 HunyuanVideo-13B 的视觉质量和运动质量实验中,DiffusionART 达到 DiffusionNFT 和 Flow-GRPO-Fast 后期平均奖励水平的速度分别快 12.02 倍和 11.72 倍 。DiffusionART 曾在论文公开当天登顶 Hugging Face Daily Papers 日榜 Top 1。 作者介绍 :该工作的第一作者为新加坡国立大学(NUS)计算机系博士生万政霖,主要研究方向为多模态理解与生成、强化学习,指导老师为 NUS 校长青年教授尤洋老师。通讯作者为可灵 AI 算法研究员陈佳煜,本科及博士均毕业于清华大学电子工程系。 论文链接: https://arxiv.org/abs/2610.12572 代码链接: https://github.com/vanzll/DiffusionART Hugging Face 模型链接: https://huggingface.co/collections/vanzl/diffusionart 项目链接: https://vanzll.github.io/diffusionart-project/ 图 1|左侧展示 HunyuanVideo-13B 在等权 VQ/MQ 下的训练曲线与 GPU-hour 效率;右侧展示相同 prompt 的图像和视频生成案例。 一、现有路线的缺陷:有的更新太慢,有的更新快却不稳定 扩散模型后训练技术在视频生成业界的地位越来越重要,它主要分为两种范式: Reverse-process RL ,以 Flow-GRPO 为代表,更接近传统 RL 范式。它将反向去噪过程建模为 MDP,通过 ODE-to-SDE 转换计算策略梯度。但最终 reward 被无差别地分配到轨迹中的每一步,导致信用分配不佳,训练效率受限。 Forward-process RL ,以 DiffusionNFT 为代表,更接近 Diffusion 的监督训练范式。它对生成结果重新加噪,通过 rew
Related stories
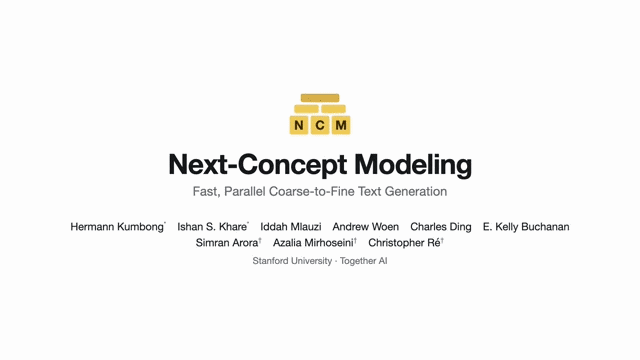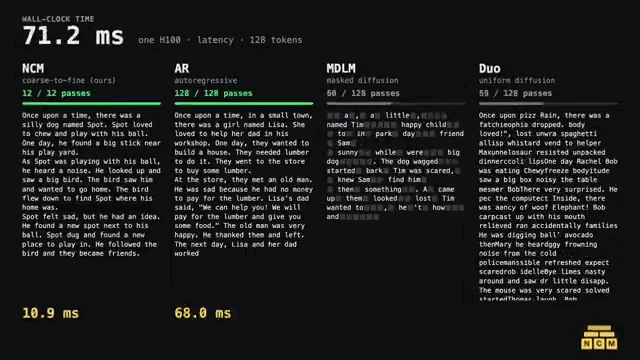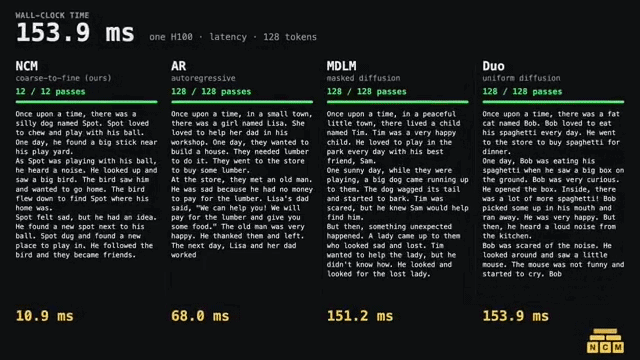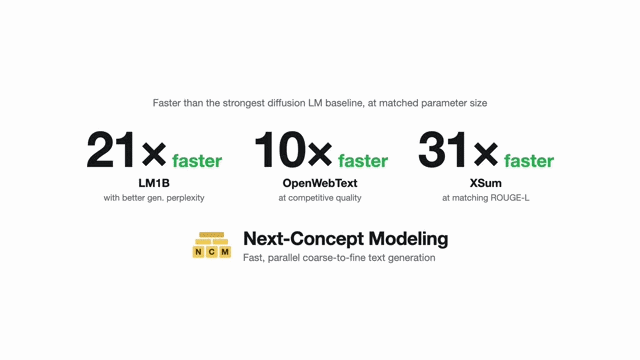
Stanford, Together AI propose Next-Concept Modeling for parallel text generation, 10-31x speedup
Researchers from Stanford University and Together AI introduced Next-Concept Modeling (NCM), a coarse-to-fine parallel text generation paradigm adapted from next-scale prediction used in image generation. In experiments, NCM achieved 10-31x speedup over diffusion language models with comparable or better quality, offering an alternative to both autoregressive and diffusion approaches.
1 reports · 1 sources
ReGDiff improves metamaterial design stability and diversity via regulated latent space
Virginia Tech and Meta researchers propose ReGDiff, a diffusion-based generative method for metamaterial voxel geometry, presented at NeurIPS 2026. ReGDiff uses a regulated latent space and sampling-time repulsion to improve geometric validity and diversity, achieving average gains of 8.9% in validity and 46.4% in novelty over the strongest baseline. They also introduce the MetaTruss and MetaShell datasets and five evaluation metrics.
Alibaba Qwen and OSU Propose TRACE to Speed Up FP4 RL Rollout by 5.4x
Alibaba Qwen and Ohio State University researchers proposed TRACE, a rollout-guided quantization-aware training method for FP4 reinforcement learning of mixture-of-experts (MoE) language models. By using the actual FP4 quantization results from the rollout side to guide rounding on the training side, TRACE reduces discrepancies between training and rollout paths, recovering performance close to BF16 while achieving up to 5.4x decoding throughput improvement in rollout with FP4 weights/activations and FP4 KV cache at 128K output length. The paper is available on arXiv and Hugging Face.
Tsinghua team's MGFlow and Elastic Forcing achieve SOTA one-step image generation and efficient 14B video model post-training
Researchers at Tsinghua University and collaborators introduced distributional training, a method that supervises generation by comparing the overall distribution of generated samples with reference samples rather than assigning unique answers per sample. Their MGFlow method achieved state-of-the-art one-step generation on ImageNet 256×256 (pMF-H, JiT-H: 1.45, 1.64 FID) and outperformed the original 4-step FLUX.2 [klein] 4B model in text-to-image (GenEval 0.900, PickScore 21.98). Elastic Forcing, the video counterpart, scored 84.64 on VBench, surpassing Self Forcing, and post-trained a 14B streaming video model on 8 H200 GPUs in 23.2 hours.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe