Intel Unveils Data-Center GPU D-Series With Up to 480GB LPDDR5X Memory
Intel announced its data-center GPU D-series, featuring up to 480GB of LPDDR5X memory, an unusually large capacity aimed at demanding inference workloads. The memory uses laptop-class LPDDR5X, setting a new GPU memory record for the company.
Coverage timeline
Techmeme
Efosa Udinmwen / TechRadar : Intel unveils its GPU D-series for data centers, featuring up to 480GB of LPDDR5X memory, an unusually large capacity to support demanding inference workloads — Intel GPU D-series uses laptop LPDDR5X with 480GB memory — Intel's GPU D-series sets a new GPU memory record with 480GB of LPDDR5X

Related stories
Nvidia Adds 64GB DGX Spark at $4,999, Priced Above 128GB Launch Model
Nvidia announced a 64GB unified-memory version of its DGX Spark mini PC, priced at $4,999. The price is $1,000 higher than the 128GB version at launch, a result of the ongoing memory shortage. The device is designed to run AI models locally.
1 reports · 1 sources
Microsoft unveils Maia 300 AI chip, claims 40% more tokens per megawatt
Microsoft announced its third-generation in-house AI chip, the Maia 300, built on TSMC's N2P process node and designed as the primary AI inference system for its products and services. The company expects the chip to deliver 40% more tokens per megawatt compared to leading GPU-based systems, with production rollout starting in 2027. Maia 300 racks will hold 96 chips using about 167 kW, and Microsoft plans multi-gigawatt deployments starting next year.

NVIDIA launches Nemotron 3.5 Super VL, 120B open model; vLLM adds Day 0 support
NVIDIA has launched Nemotron 3.5 Super VL, a 120B-parameter open model for enterprise agents, claiming it outperforms frontier models on specialized benchmarks. vLLM announced Day 0 support for the model, enabling multimodal agent workflows with image, document, and video understanding, OpenAI-compatible serving, and multi-token prediction.
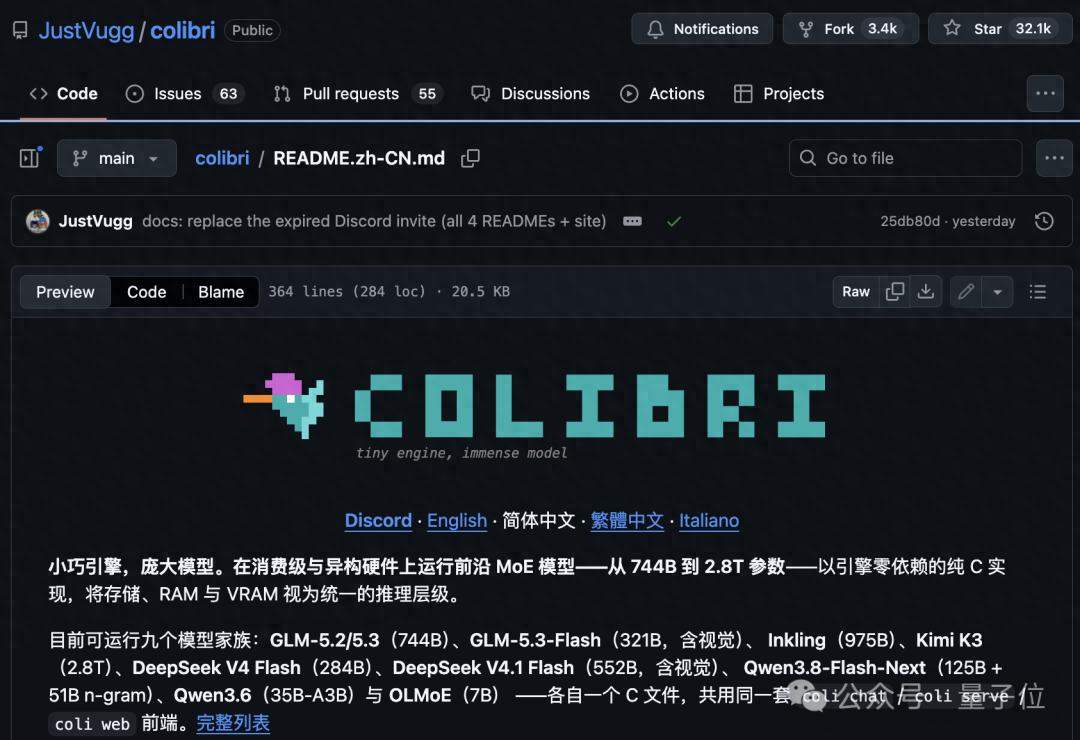
Colibrì: C-based inference framework runs 744B-param GLM-5.2 on laptops via SSD offloading, no GPU needed
Colibrì, an open-source C-based hierarchical inference framework, has gained 32k GitHub stars for enabling large MoE models to run on laptops with limited RAM by offloading inactive experts to SSD, without requiring a GPU. It supports models from GLM-5.2/5.3, DeepSeek V4 Flash, Qwen, to 975B Inkling and 2.8T Kimi K3, with RAM requirements as low as 16GB for int4-processed GLM-5.2.
1 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe