NVIDIA launches Nemotron 3.5 Super VL, 120B open model; vLLM adds Day 0 support
NVIDIA has launched Nemotron 3.5 Super VL, a 120B-parameter open model for enterprise agents, claiming it outperforms frontier models on specialized benchmarks. vLLM announced Day 0 support for the model, enabling multimodal agent workflows with image, document, and video understanding, OpenAI-compatible serving, and multi-token prediction.
Coverage timeline
vLLM BlogNVIDIA Nemotron Team
Run NVIDIA Nemotron 3.5 Super VL on vLLM for multimodal agent workflows with image, document, and video understanding, OpenAI-compatible serving, and multi-token prediction.
Techmeme
Carl Franzen / VentureBeat : Nvidia launches Nemotron 3.5 Super VL, a 120B-parameter open model for enterprise agents, and says it outperforms frontier models on specialized benchmarks — An enterprise agent reviewing a credit agreement may need to extract figures from tables, interpret a chart, check a related webpage …

Related stories
vLLM Adds Day-0 Support for NVIDIA Vera Rubin NVL72, Claims 7.8x Throughput over GB200
vLLM announced support for NVIDIA Vera Rubin NVL72, claiming 7.8x throughput over GB200 NVL72. The platform offers daily container builds and day-0 model support for DeepSeek, Moonshot AI, Z.ai, and MiniMax, leveraging Blackwell kernel compatibility and Rubin-tuned kernels via FlashInfer 0.7.0.
Xiaomi open-sources MiMo-V2.6 Pro and Flash; Pro tops open-weight leaderboard
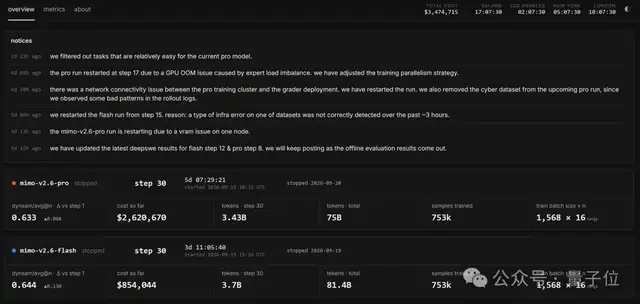
Xiaomi's MiMo team released and open-sourced the MiMo-V2.6 series, including Pro and Flash omnimodal models, after a six-day livestreamed reinforcement learning training run that cost $3.5 million. MiMo-V2.6-Pro scored 46 on Artificial Analysis' Intelligence Index, tying Grok 4.7 and beating GLM-5.3, making it the top-scoring open-weight model on that benchmark; Xiaomi claims Pro performs on par with Opus 5 and GPT-5.6 Sol across most agent benchmarks.
4 reports · 3 sources
Prime Intellect launches Prime Inference serving platform for open models
Prime Intellect announced the launch of Prime Inference, a serving platform for frontier open-source models offering resilient serverless and reserved serving across multiple datacenters. The platform's production architecture includes prefill/decode optimization, NVFP4 KV compression, and NIXL transfer, as demonstrated in its GLM-5.3 deployment on GB200 NVL72.
2 reports · 1 sources
Reflection AI unveils open-weight model Beam, claims lower compute and near-Qwen3.8-Max performance
Reflection AI, backed by Nvidia, has unveiled its first open-weight model, Beam, claiming it excels at coding and agentic tasks while using 3x-4x less compute than comparable models. The company says Beam's reasoning performance nears Qwen3.8-Max and rivals GLM-5.2 at lower inference compute, with weights expected to be released this month.
2 reports · 2 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe