ME-Decoding: Rethinking LLM Decoding as Ensemble Pruning
Researchers at Renmin University propose Mahalanobis-Ensemble Decoding (ME-Decoding), a method that selects candidate tokens by semantic redundancy in addition to probability, accepted at EMNLP 2026 Main Conference. The method formulates token selection as a dynamic subset optimization problem, using both model probabilities and token embeddings to find a sampling support with high confidence and low internal redundancy. In tests across three models and three temperature settings, ME-Decoding achieved the best average performance on reasoning and open-ended generation tasks, with only about 3% additional latency compared to the fastest probability-truncation baseline.
Coverage timeline
机器之心机器之心
本文已被 EMNLP 2026 Main Conference 接收。论文第一作者为中国人民大学统计与大数据研究院博士研究生薛敦耀,通讯作者为中国人民大学代文林、孟澄研究员。 在一次解码步骤中,大语言模型面对的并不是唯一答案,而是一组具有不同概率的候选 token。为了提升解码多样性,现有方法往往不采取贪心选择的策略而是从概率分布中采样来得到下一步预测。为了避免采样到极小概率 token,Top-p、Min-p 等常用方法根据概率截断候选集合,再从剩余部分进行采样。 这些方法简单有效,但却忽略了一个问题: 概率高的 token,不一定能为候选集合带来新的信息 。多个高概率 token 可能在语义上高度相似,只是同一条生成路径的不同表达。如果只按概率筛选,它们会被同时保留;而一个概率略低、但能提供不同语义方向的 token,反而可能被提前截断。最终得到的候选集合看似 “可靠”,实际上却包含大量冗余。 中国人民大学代文林研究员、孟澄研究员团队提出的 Mahalanobis-Ensemble Decoding(ME-Decoding) ,将解码中的候选 token 筛选改写为一个动态子集优化问题。方法同时读取模型概率和 token embedding,在每个生成步骤中寻找置信度较高、内部冗余较低的 sampling support。在所测三个模型、三个温度设置的汇总结果中,ME-Decoding 在推理与开放式生成任务上均取得了所比较方法中的最佳平均表现;端到端 GPU 测试中,相比最快的概率截断基线,总延迟仅增加约 3%。 左侧:概率截断仅依据单个 token 的概率决定去留。右侧:ME-Decoding 同时利用 token 概率与 embedding 相似度,选择整体信息量更高的候选子集。 论文标题: Beyond Truncation: Rethinking LLM Decoding as Ensemble Pruning 论文地址: https://arxiv.org/abs/2609.18723 代码地址: https://github.com/sapphirexdy/ME_decoding ME-Decoding 是怎么做的 ME-Decoding 将候选 token 看作待剪枝的集成成员:既关注单个候选的概率,也考察它与其他候选的语义关系。方法主要可以概括
Related stories
Xiaohongshu and Fudan propose DR-Rubric for open-ended RL at NeurIPS 2026
Researchers from Xiaohongshu and Fudan University presented DR-Rubric (Deep Research as Rubric), a method accepted at NeurIPS 2026 that generates fine-grained scoring rubrics for open-ended reinforcement learning by first conducting deep research on the task. The approach, which has been used in Xiaohongshu's business, achieves competitive results on six benchmarks using only 1000 RL data per round. The paper and code are publicly available.
1 reports · 1 sources
RAVEL: Training-Free Method Improves Vision Encoder Evaluation for Multimodal LLMs
Researchers proposed RAVEL, a training-free evaluation method with two improvements—stabilized PCA whitening and patch-level similarity scoring—to predict how well vision encoders perform in multimodal LLMs. Experiments on 210 multimodal LLMs showed existing cross-modal methods degrade as candidate pools grow, while RAVEL achieved an average Spearman correlation of 0.85, outperforming prior methods by up to 101.1%.
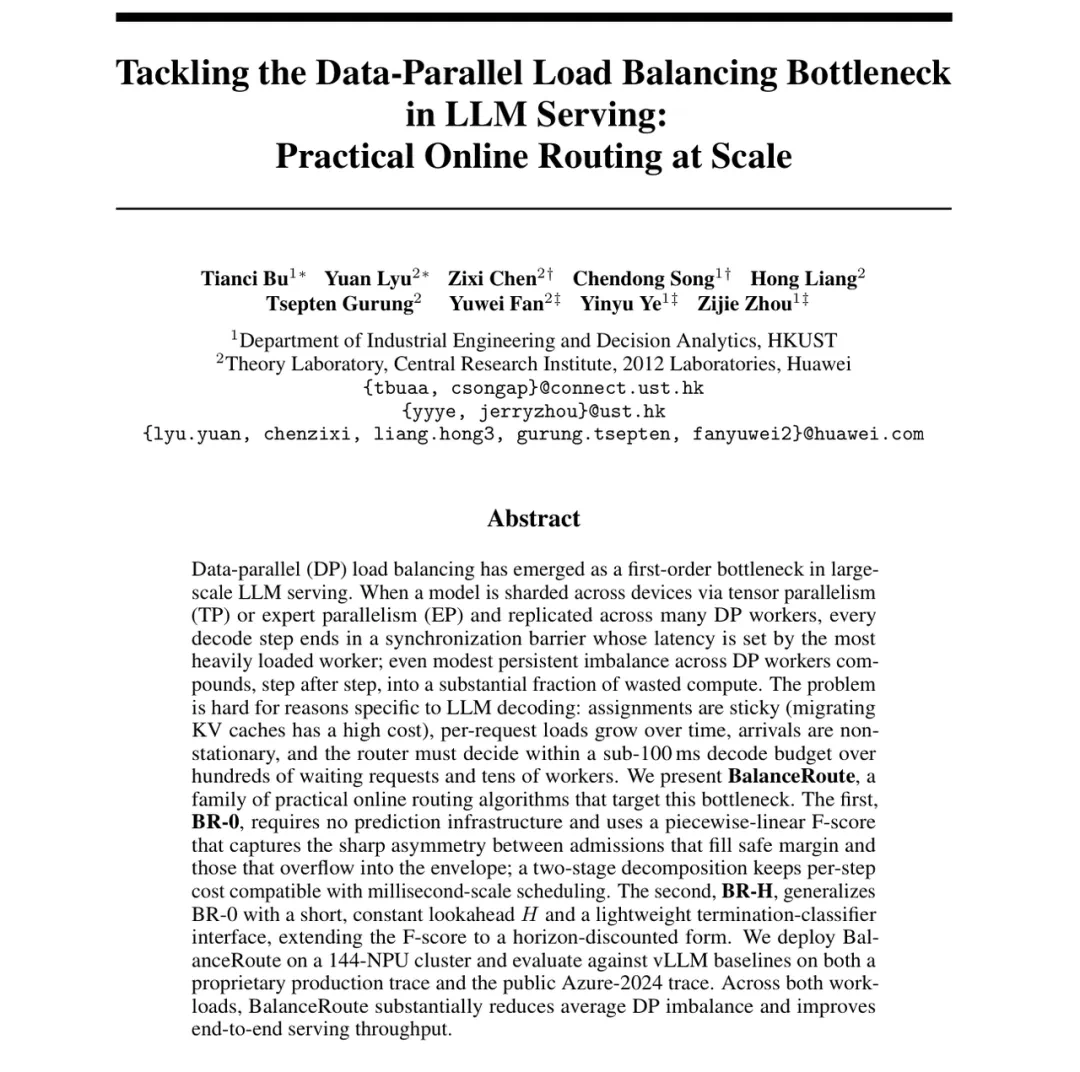
HKUST and Huawei propose BalanceRoute to cut MoE LLM serving load-balancing bottleneck
Researchers from HKUST and Huawei's 2012 Lab propose BalanceRoute, an online routing method that models synchronous waiting in MoE LLM serving and converts short-term load prediction into routing decisions. In a 96-GPU test, the predictor-based variant BR-H improves decode throughput by about 15% over the strongest baseline. The work is accepted by NeurIPS 2026 and deployed in the jointly built MaaS system MathBot-Pie.
Apple and Duke propose LensVLM, compressing long context into images with on-demand zoom
Apple's foundation model team and Duke University introduced LensVLM, a method that compresses long context into images and lets the model zoom into relevant pages on demand. In seven text QA benchmarks, it achieved 68.9% average accuracy with 4.3x effective compression, close to the 72.4% of full-text reference. The work was accepted at NeurIPS 2026, and a public 9B demo is available.

News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe