MiniMax open-sources H3-Image, native 4K image model topping open-weight leaderboards
MiniMax released H3-Image, an open-source image generation model that natively outputs 4K resolution and supports up to 16 reference images. According to the Artificial Analysis leaderboard updated on the release date, it ranks first among open-weight models in both text-to-image and image editing. vLLM announced day-0 support for H3-Image on Vera Rubin hardware, claiming 4K generation in 0.87 seconds on four GPUs.
Coverage timeline
vLLM BlogvLLM-Omni team
H3-Image on Vera Rubin: 0.87-second 4K generation or 6,115 images/hour on four GPUs, with projected API revenue and support across consumer and data-center hardware.
量子位量子位
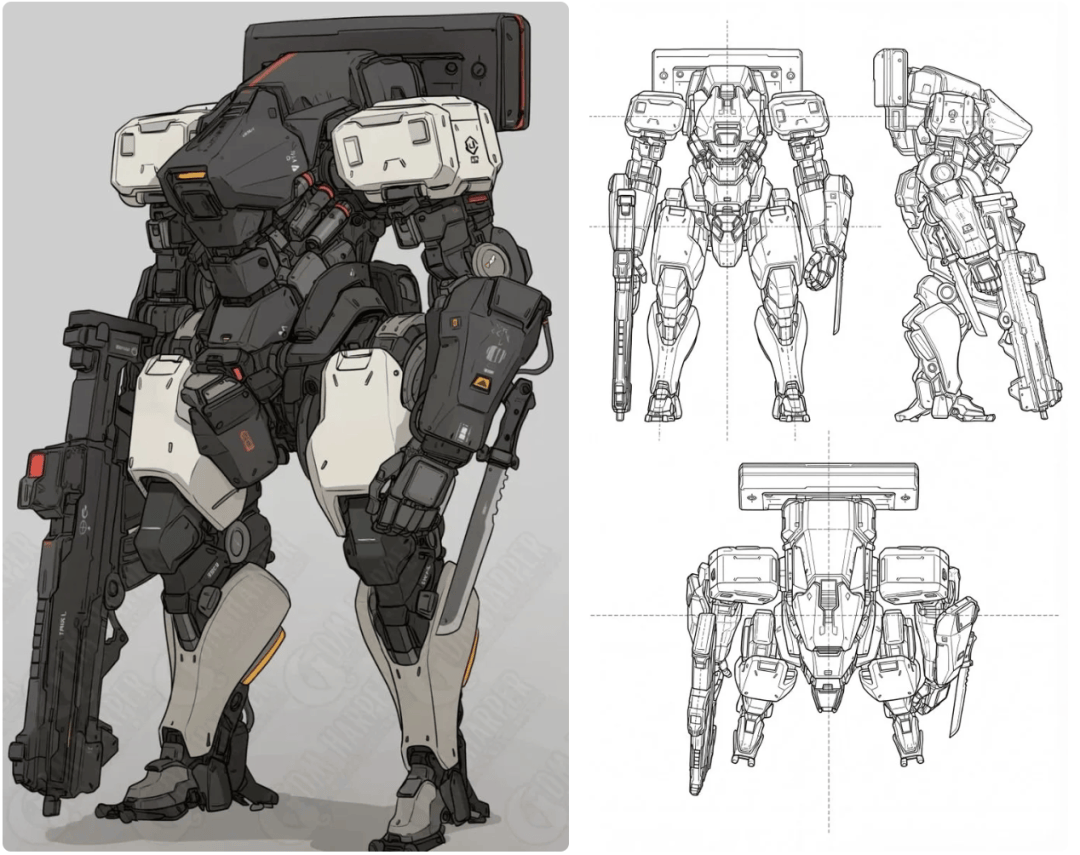
多模态“源神”!MiniMax开源SOTA生图模型,原生4K,一张两毛 Jay 2026-11-12 19:36:20 来源: 量子位 「CAD拆解」 Jay发自 凹非寺 量子位|公众号QbitAI 坏,真让MiniMax给多模态玩明白了😭。 继开源视频旗舰H3广受好评后,最新的图像模型—— H3-Image,再次席卷全网 。 热度最高的是「CAD拆解」,丢一张参考图,H3-Image能给你小手办直接开盒了。。。 还有给 宇树机器狗 CAD了的。 总之就是万物可拆解,还能给你把零件标好。 我自己也实测了一下,你还别说,真有点东西啊…… 除此之外,海外网友测下来,其他类型的复杂生图任务也是能Handle住的,比如—— 游戏 。 这这这,你不说,我还以为是GPT编程做出来的呢😭。 如果只是做点电商用的简单资产,就更轻松了。 但我没想到的是,这家伙居然是个文理双全?? 保证智商的前提下,H3-Image的审美,也有点东西。 对了,还有件事。 这种质量的图像生成模型, 你跟我说居然是开源的??? 那还说啥了。 我宣布,MiniMax就是多模态领域的「源神」 (bushi) 。 告别塑料「美商」 过去我们一提到AI生图,脑子里第一个反应:油光满面,皮肤光滑得像剥了壳的鸡蛋,眼神呆滞,伪人感极重。 总之就是一股浓浓的「AI味」。 GPT Image 2在这方面进步非常大,但用多了后,恐怖谷效应依然涌上心头。 这次的H3-Image,我感觉,应该是基本解决这个问题了。 生成完我都懵了,不是兄弟,这谁看得出来是AI啊?? 最重要的是人脸,毛孔、雀斑、 甚至绒毛 都给你画出来了。 此外,像镜子上的水泽和灰尘,闪光灯打在镜头上形成的光晕,这些细节也处理得非常离谱,真就跟小某书首页刷到的一样。 即便从仰视角度也能看出不少面部细节,就比如下面这张 桌子即ins照片 的时尚杂志封面,你仔细看人物的眼神,和微妙的面部肌肉牵引,都是非常符合现实社交逻辑的。 这也是我测H3-Image时最大的一个感受,很多我丢给老模型做过的提示词,H3-Image都能给出全新诠释。 确实世界知识比较丰富。 至于人脸之外的主体,就更是手拿把掐了。 比如,把里约热内卢的城市地标,做成一个立体纸雕风格的旅行手帐。 微缩景观、光影厚度,hmm,总感觉有股 Fable 5 宣传片的味道。 而且果然又露出了小鸡脚! 你看
机器之心机器之心
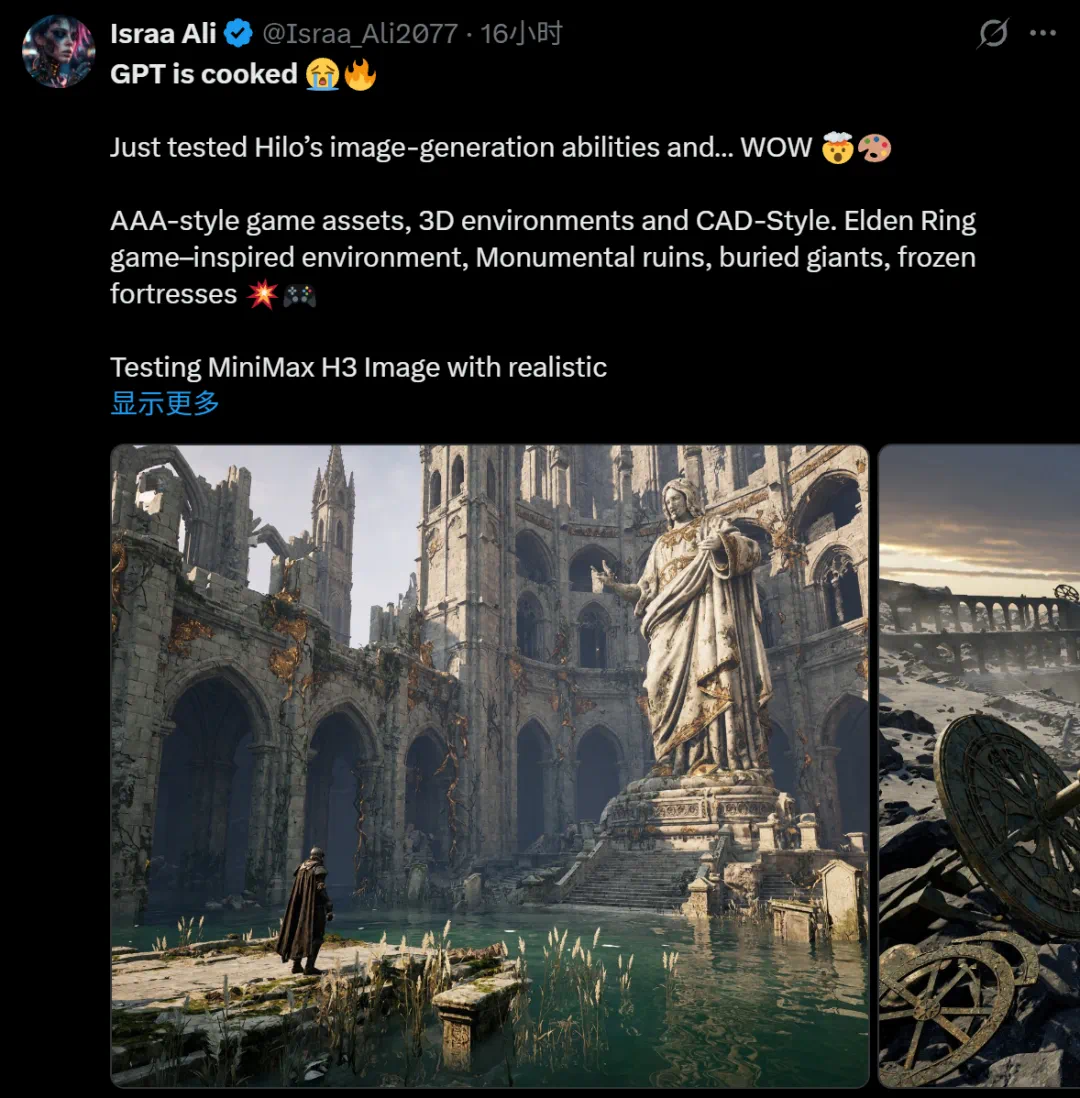
编辑|泽南、杨文 「GPT is cooked.」 这两天,这句话在 AI 社区里反复出现。让人坐不住的是 MiniMax 刚发布的图像模型 MiniMax H3 Image 。 这是一个原生 4K 直出、10 秒级生成、支持 16 张参考图的模型,本周二刚刚开源, 刷新了开源图像模型的 SOTA 。从大家的第一波反应看,这个说法似乎并不夸张。 有提前拿到内测权限的开发者进行了大量测试。在新模型输出的内容里,AI 人像那层「塑料皮」没了,毛孔、雀斑、汗毛都清晰可见。人们对它在游戏设计、角色设定和 3D 场景上的能力赞不绝口。 在今天更新的 Artificial Analysis 榜单上, MiniMax H3-Image 在文生图、图像编辑两项榜单中均位列开放权重模型第一 。 MiniMax H3 Image 支持网页端直接用,也可以通过 API 的方式在 MiniMax Code 或是其他 harness 中使用来完成一些复杂的任务。而且因为它是开源的, 有人已经在搞本地部署了 。 GitHub:https://github.com/MiniMax-AI/MiniMax-H3-Image HuggingFace:https://huggingface.co/MiniMaxAI/MiniMax-H3-Image 我们第一时间拿到了新模型的使用权限,帮大家看看实测是个什么水平。 重新定义画面美学与「真实感」 这款新模型已经在 MiniMax Code 里面上线,打开一看支持多达 16 个参考图,生成的图片最高可达 4K 分辨率。 我们以普通用户的视角,把日常会用到的场景按四个能力维度挨个测了一遍,先看真实感,再啃文字和人脸这两个经典难题,最后试试图生图的二次创作。 真实效果是第一关 。最容易暴露 AI 痕迹的,往往是我们每天都在看的东西,比如微信聊天界面。 提示词:生成一张微信聊天截图:我先给对方发送一张非常逼真的可口可乐照片,并说:“这是 MiniMax H3 Image 生成的” 对方回复:“我的天啊” 然后我再说:“开玩笑的,这是我自己拍的” 请确保截图包含高度逼真的 iPhone 状态栏细节,包括时间、电池电量和信号强度。 我们只输入一段提示词,MiniMax H3 Image 就把一张完整的微信聊天截图生成出来了。 这类日常界面之所以难,是因为人眼对熟悉场景
Related stories
MiniMax unveils M3.1 Flash, claiming top agent scores and low cost
MiniMax released M3.1 Flash, the official version of the previously anonymous Space Bunny model, claiming a generational leap in agentic tasks, coding, computer use, and cybersecurity. The model scores 29.6% on Agents' Last Exam (ALE), the top for Chinese models, with pricing at 1 yuan per million input tokens and 4 yuan per million output tokens. Weights are due October 23, with day-0 support from vLLM on Blackwell, Rubin, and AMD MI350 GPUs.

OpenAI launches Images 2.6 with GIF creation, faster generation, and new API controls
OpenAI has released Images 2.6, now available across ChatGPT, Codex, and the API. The update introduces native GIF creation from prompts or photos, with options to adjust animation speed and edit individual frames, alongside a claimed 50% faster image generation. The API also adds two sub-models, Flare and Sunburst, and separates complexity and quality parameters for more efficient multi-round editing.
5 reports · 5 sources384 points · 238 comments

Open-Source 5B Image Model MOSS-Image Hits 1.3M Downloads in 4 Days
MOSS-Image, an open-source 5B-parameter image generation model from Mosi AI and OpenMOSS, gained over 1.3 million downloads within four days of release, topping Hugging Face's text-to-image trend chart. Developers praised its natural look, attributing it to training data that excludes AI-generated images, and quickly created accelerated versions, quantized formats, and LoRA adaptations.
1 reports · 1 sources
Baidu open-sources ERNIE 5.5 Flash Base, 280B MoE model with 14B active parameters
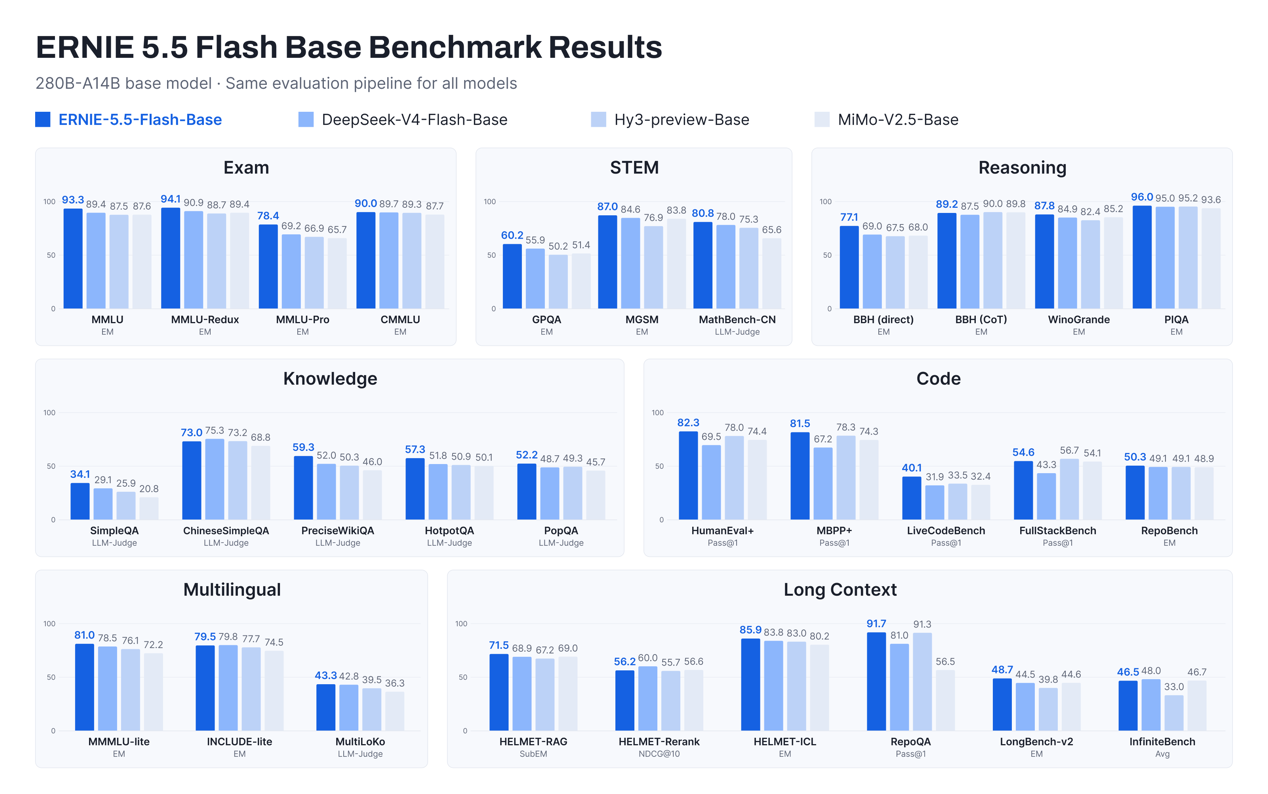
On November 5, Baidu open-sourced ERNIE 5.5 Flash Base, a sparse MoE language model with 280B total parameters and 14B active per token, pretrained on 33.5T tokens with up to 128K training context and 1M-token context for fine-tuning and inference. The company claims SOTA results among same-size models on benchmarks covering knowledge, reasoning, math, code, multilingual, and long-context tasks, surpassing DeepSeek-V4-Flash-Base, Hy3-preview-Base, and MiMo-V2.5-Base. The release includes weights on Hugging Face and ecosystem support with vLLM and SGLang.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe