vLLM Optimizes GLM-5.3 Serving on 16 H200s with PCP, DCP, Hybrid HiSparse
vLLM's blog details serving GLM-5.3 on 16 H200 GPUs using PCP and DCP for prefill and Hybrid HiSparse for decode, enabling 1M-token contexts. On the AgentX agentic benchmark, this configuration achieves 1.7–3.2× per-user speedups over data-parallel prefill/decode.
Coverage timeline
vLLM BlogvLLM Team
vLLM serves GLM-5.3 on 16 H200s with PCP and DCP prefill and Hybrid HiSparse decode, reaching 1M-token contexts and 1.7–3.2× the per-user speed of data-parallel P/D on the AgentX agentic benchmark.
Related stories
vLLM Uses AI Agents to Optimize Kimi K3 Decode on NVIDIA GB300, Hitting 840+ Tokens/s
The vLLM team reports using agent-assisted development to build a unified CuTe DSL decode path for Kimi K3 on NVIDIA GB300, covering attention, MoE, and communication across 8 or 16 GPUs. The optimizations achieve over 840 tokens/s at batch 1 on 16 GPUs with DSpark (synthetic AL=6), 1.5–2× higher decode throughput in several configurations, and up to 1.8× higher P90 interactivity on the AgentX workload. The team notes that agent-optimized inference code is outpacing their manual review and maintenance workflow.
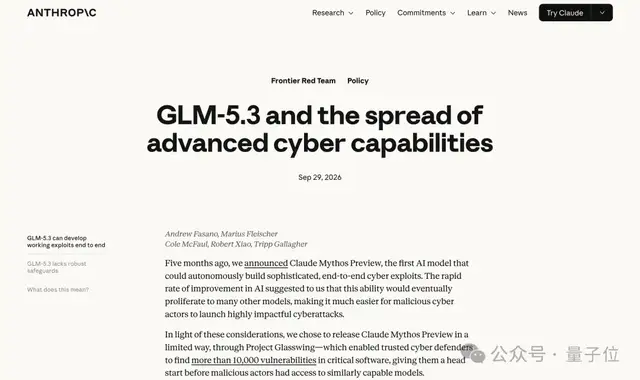
Anthropic warns GLM-5.3 matches Claude Mythos in cyber exploits, lacks safeguards
Anthropic's Frontier Red Team published a report stating that Zhipu's GLM-5.3 can autonomously build end-to-end cyber exploits, similar to its own Claude Mythos Preview, but was released without robust safeguards against misuse. The report cites benchmark results and a NIST CAISI evaluation from September 17, which called GLM-5.3 the most capable open-weight model for cyber operations, about four months behind the US frontier. Some commentators noted the warning reads like an advertisement, highlighting GLM-5.3's strong performance.
3 reports · 3 sources251 points · 234 comments
vLLM Engineers Detail Scaling Kimi K3 Inference on AMD MI355X to Match NVIDIA B300
vLLM engineers published a blog post describing how they scaled inference for the Kimi K3 model on AMD Instinct MI355X GPUs, achieving per-GPU throughput matching NVIDIA HGX B300 on the AgentX benchmark. The post details the bottleneck analysis and key optimization decisions that enabled this performance parity.
vLLM Boosts DeepSeek-V4.1-Flash: 1.9x Low-Concurrency Speed, 5x Agentic Throughput
According to a vLLM blog post dated October 7, 2026, within three weeks of DeepSeek-V4.1-Flash's release, vLLM optimizations made the model 1.9x faster at low concurrency and increased its throughput 5x on the SemiAnalysis AgentX benchmark. The improvements are attributed to SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe