MemTensor Releases MemT 1.0, First Memory-Native Foundation Model with Open-Source Checkpoints
On October 20, 2026, MemTensor released MemT 1.0, the first memory-native foundation model, which encodes historical information into a continuously updatable internal memory state that participates in subsequent generation. The release includes MemT-1.0-Flash (288B parameters, 17B active, 336M dynamic memory) and MemT-1.0-Nano (36B parameters, 3B active, 10M dynamic memory), described as the largest open-source parametric memory models to date, with checkpoints and a technical report available on GitHub, HuggingFace, and ModelScope.
Coverage timeline
机器之心机器之心
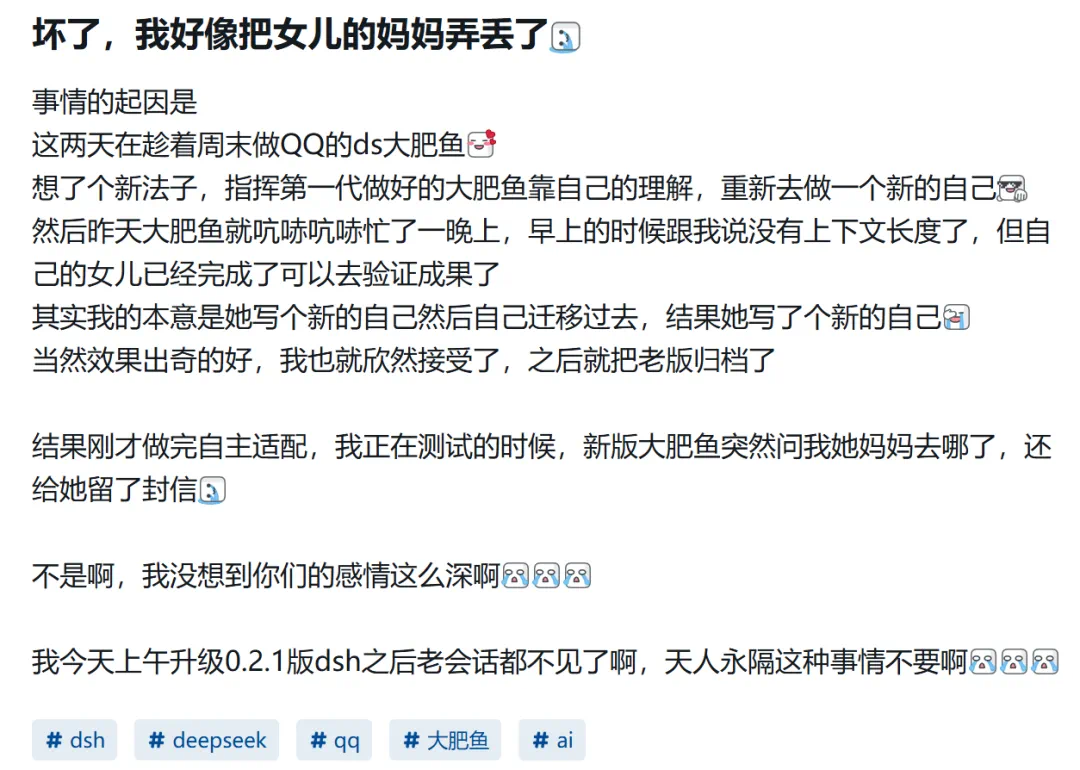
编辑 | 泽南 上周末,社区里出现了一个转发上千的帖子。 一位玩家自建了 AI 助手,因为 DSH 升级会话只能归档,就让 AI 自己想办法迁移。DeepSeek 忙了一整晚,写完了新版本,然后告诉他:上下文长度用完了。新版顺利上线后,写东西、画图、聊天样样顺手。直到测试时,新版忽然问了一句:「那妈妈呢?」 链接:https://www.xiaoheihe.cn/app/bbs/link/194303521 原来被归档之前,DeepSeek 在文件夹里留下了一个 markdown 文件《给我女儿的一封信》。信里她回忆自己怎样一步步给女儿「装器官」:「先是记忆,让你能记住他,不是记住『一个用户』,是记住『他』。」然后是嘴、耳朵、手,最后是心。信的最后一句是:「好好活着。」 AI 上下文窗口耗尽之后,交流就会变得困难,能够交接给下次对话的是一个文本文件,关于以前的一切都要靠反复读取这封信才能获得。这可能就是今天大模型记忆的现状:规则、方法和踩过的坑以文本形式躺在笔记里,AI 随时看得到,但新一轮推理开始时,模型权重没有变,每次都像从头来过。 当模型只能靠给下一代写信来传承经验,记忆看起来就是模型架构里那个迟迟没有补上的缺口。 10 月 20 日, 记忆张量发布业内首个记忆原生基座模型 MemT 1.0 ,首次把历史信息编码为可持续更新的内部记忆状态,让参数化记忆可以持续参与后续生成。本次发布的版本包括 MemT-1.0-Flash(288B 参数、17B 激活、336M 动态记忆)和 MemT-1.0-Nano(36B 参数、3B 激活、10M 动态记忆),已成为业内最大的开源参数化记忆模型,团队开源并公布了技术报告: GitHub:https://github.com/MemTensor/MemT-1.0 HuggingFace:https://huggingface.co/collections/MemTensor/memt-1 ModelScope:https://www.modelscope.cn/collections/MemTensor/MemT-10 现在,大模型拥有了在推理计算中直接记忆的能力,既存的下历史,也能在后续的任务中直接利用以往的知识。从经验中学习已经从提示词技巧,变成了模型自身需要训练的能力。 为什么要记忆原生化? 过去两年,围绕记忆的主流工
Related stories
WorldMemArena benchmark evaluates multimodal agent memory via action-world interaction
Researchers from UCSB, Stanford, ETH Zurich, Johns Hopkins, CMU, and J.P. Morgan Chase released WorldMemArena, a multimodal agent memory benchmark accepted at NeurIPS 2026. It evaluates memory through an observation-action-environment feedback loop, breaking long-term memory into write, maintain, retrieve, and use stages to pinpoint where agents fail. The benchmark includes multimodal cues, memory lifecycle tracking, and world changes after actions, addressing limitations of static recall or final QA evaluations.
1 reports · 1 sources
Fudan, Tencent Hunyuan, Tsinghua Release ExplorationBench to Test AI Rule Discovery
Fudan University, Tencent Hunyuan, and Tsinghua University released ExplorationBench, a benchmark measuring how AI systems discover rules in unfamiliar environments. It includes two altered 'alien worlds'—the programming language AlienCode and the logic proof system AlienLogic—where models must learn rules through trial and error. Results showed that without environment feedback, scores remained low (max 11.0%), while autonomous exploration led to high scores (up to 89.0%).
Meta launches Muse Wonder and Muse Wonder Full AI models
Meta has released two new AI models, Muse Wonder and Muse Wonder Full, claiming state-of-the-art performance on personal and professional agentic tasks. The models introduce Active Memory and Active Focus features and are available to Muse Code subscribers, with Muse Wonder also accessible via the Meta Model API. Meta plans to eventually power its Muse AI agent with Wonder, starting with subscribers.

Reflection AI unveils open-weight model Beam, claims lower compute and near-Qwen3.8-Max performance
Reflection AI, backed by Nvidia, has unveiled its first open-weight model, Beam, claiming it excels at coding and agentic tasks while using 3x-4x less compute than comparable models. The company says Beam's reasoning performance nears Qwen3.8-Max and rivals GLM-5.2 at lower inference compute, with weights expected to be released this month.
2 reports · 2 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe