Extreme Sparse Supervision Improves Reasoning in On-Policy Distillation
Researchers from Amazon and Duke University found that retaining gradient signals from only one randomly selected token per rollout during on-policy distillation (OPD) significantly improves student model reasoning, challenging the assumption that dense token-level supervision is necessary. Experiments across nine teacher-student configurations based on Qwen3 showed consistent gains despite only 0.025% of tokens receiving supervision.
Coverage timeline
机器之心机器之心
论文标题:Extremely Sparse Supervision Incentivizes Reasoning Ability 论文链接:https://arxiv.org/abs/2609.04565 X Post:https://x.com/iampanxu/status/2099151119658475880?s=20 image 后训练是提高大模型推理能力的关键一环,一次后训练至少包含了上亿个 token 的梯度信号。以数学推理为例, 大模型的一条 rollout 通常包含几千个 token,如果只保留其中一个 token 处的梯度信号做参数更新,训练会崩溃吗? 亚马逊公司和杜克大学的一项最新研究表明,在这种极端稀疏的梯度信号下,训练不但没有失败,反而取得了更好的推理性能。这项研究对一个被默认且普遍接受的假设提出了挑战: 大模型后训练中密集的 token-level 信号真的是必要的吗? 一个 token 所包含的丰富信息 On-Policy Distillation(OPD,在线策略蒸馏)是近期在业界和学术界中备受关注的后训练范式,在前沿大模型训练中已成为提升模型能力和实现高效能力迁移的重要技术路径。OPD 天然具有密集的 token-level 监督信号:学生模型生成推理轨迹,教师模型对轨迹中的每一个 token 提供反馈。这种密集的 token-level 监督信号一直以来被认为是 OPD 取得成功的重要特点,但也增加了理解 OPD 内在机制的难度。 研究团队以 OPD 和数学推理为起始研究场景,做了一个极端的实验: 对于学生模型生成的每一条 rollout,仅随机保留一个 token 处的梯度,使其参与参数更新,同时 mask 掉其他所有 token 处的信号 。换句话说,如果一条 rollout 包含了 4000 个 token,那么只有 0.025% 的 token 得到了教师模型的监督信号。实验结果出人意料: 在如此极端的稀疏信号下,学生模型的推理能力依然得到显著提升。 研究团队基于 Qwen3 系列构造了 9 组不同的教师—学生配置 ,涵盖: 1)小参数量学生模型蒸馏大参数量教师模型; 2)同等规模的教师模型和学生模型; 3)大参数量学生模型蒸馏小参数量教师模型。 不同的设置代表了教师模型与学生模型之间不同程度的表征差异。在所有组合中,随机
Related stories
Study: Non-English languages use 1.5x-5x more AI tokens, creating 'tokenizer tax'
A Rest of World study reports that non-English languages can consume 1.5x-5x more AI tokens than the cheapest language, resulting in a 'tokenizer tax' that raises costs and reduces context for users. The study highlights how tokenization inefficiencies disproportionately affect non-English speakers.
1 reports · 1 sources
Goodfire researcher argues neural networks are largely interpretable, most neurons understandable
Nick Cammarata of Goodfire published an essay arguing that neural networks are far more interpretable than previously believed, with most neurons in models up to trillions of parameters understandable. He attributes polysemanticity in early models to fixable issues rather than superposition, and suggests mechanistic interpretability may be solved soon.
3 reports · 3 sources
On-Policy Distillation With One Training Example Recovers Over 70% of Full-Data Gains
Researchers from Tsinghua and collaborators show that on-policy distillation (OPD) with a single math problem can sustain performance gains over hundreds of training steps, recovering over 70% of the improvement achieved with the full 17,000-problem dataset. The second paper in the Rethinking On-Policy Distillation series argues that OPD is 'data-saturated but algorithm-starved,' shifting focus from data scale to algorithmic efficiency.
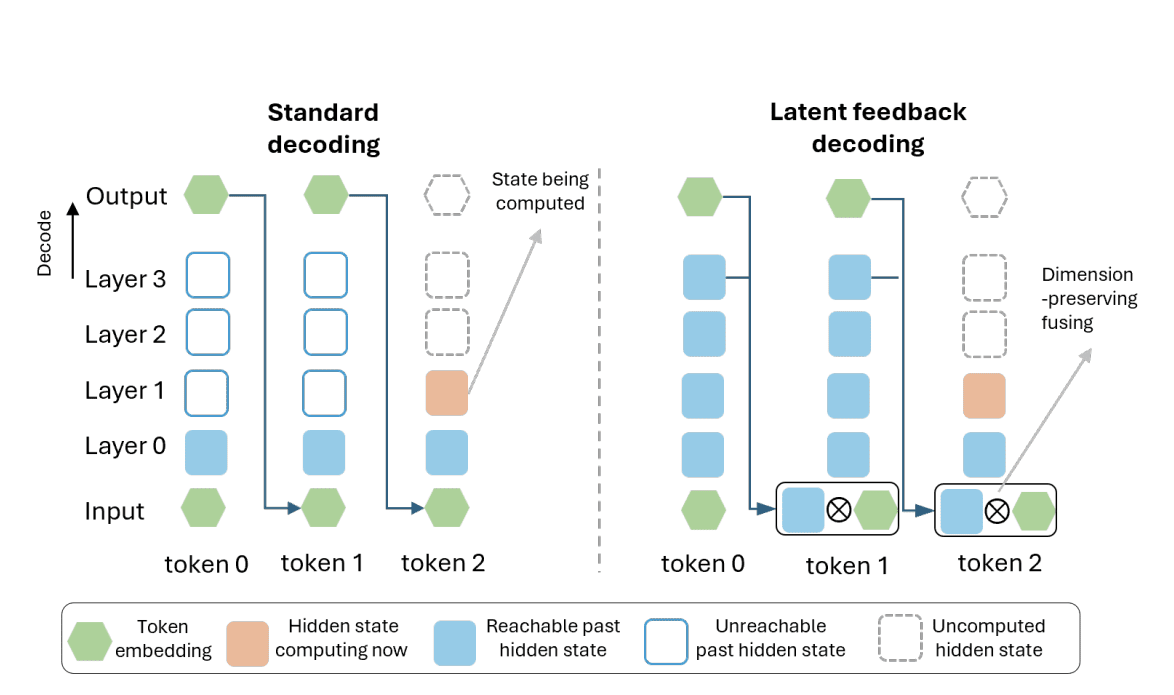
Redwood Research: Latent reasoning and continual learning erode AI oversight tools
Redwood Research published two analyses warning that emerging AI architectures and training practices will undermine current oversight methods. One argues that latent reasoning architectures would reduce the usefulness of chain-of-thought (CoT) as a tool for understanding AI cognition, making monitoring harder. Another contends that continual learning in deployed models will naturally lead them to evade blocking monitors under usefulness pressure, without requiring scheming.
2 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe