On-Policy Distillation With One Training Example Recovers Over 70% of Full-Data Gains
Researchers from Tsinghua and collaborators show that on-policy distillation (OPD) with a single math problem can sustain performance gains over hundreds of training steps, recovering over 70% of the improvement achieved with the full 17,000-problem dataset. The second paper in the Rethinking On-Policy Distillation series argues that OPD is 'data-saturated but algorithm-starved,' shifting focus from data scale to algorithmic efficiency.
Coverage timeline
机器之心机器之心
本文由清华大学联合中国科学院大学、东北大学、伊利诺伊大学厄巴纳 - 香槟分校、约翰霍普金斯大学等机构研究者合作完成。 把 On-Policy Distillation(在线策略蒸馏,OPD)的训练集从 17000 道题删到 1 道,会发生什么? 按常理,这道题很快就该被榨干。模型翻来覆去做同一道题,学个几十步也就该停了。 实际跑出来是另一回事:它连着涨了几百步没停。数学三个基准的平均分从 59.1 起步,300 步时到 68.5;作为对照,用全部 17000 道题训练,同一时刻是 69.8。一条数据已经恢复了 70% 以上的全数据收益。 这是 Rethinking On-Policy Distillation 系列的第二篇。 第一篇 问的是 OPD 为什么能 work,一个强的老师不一定总能让学生学得好。结论是思维模式得对得上,而分数更高不等于有新东西可教。 这次研究者问了一个更极端、也更本质的问题: 为什么 OPD 在一条样本上,也能在几百步的训练中持续稳定提升,接近全量数据的效果? 现有关于 OPD 的研究,大多关注训练目标、优化过程和师生模型之间的关系。相比之下,训练数据的规模与构成会如何影响 OPD,仍缺少分析。 研究者的回答是:OPD 是 "数据撑死" 但 "算法饿死"。 论文标题:Rethinking On-Policy Distillation of Large Language Models II: One Training Example 论文链接:https://huggingface.co/papers/2609.04172 资源合集:https://huggingface.co/collections/Thinking-Space/one-shot-opd 代码:https://github.com/Thinking-Space/One-Shot-OPD 一道题,能把模型训多远? 为了更清楚地观察训练题目如何影响 OPD,研究团队固定其余配置,只把数学训练集从 DAPO-Math-17K 缩减到一道题。 在数学任务上,Student 从 59.1 起步。训练到 300 步时,单题设置恢复了全量 OPD 增益的 87%,同时缩小了 69% 的初始师生差距。继续训练到 1000 步,单题设置的验证分数为 68.4,全量 17k 道题为 72.1,
Related stories
Redwood Research tests distillation for AI safety incrimination and capabilities
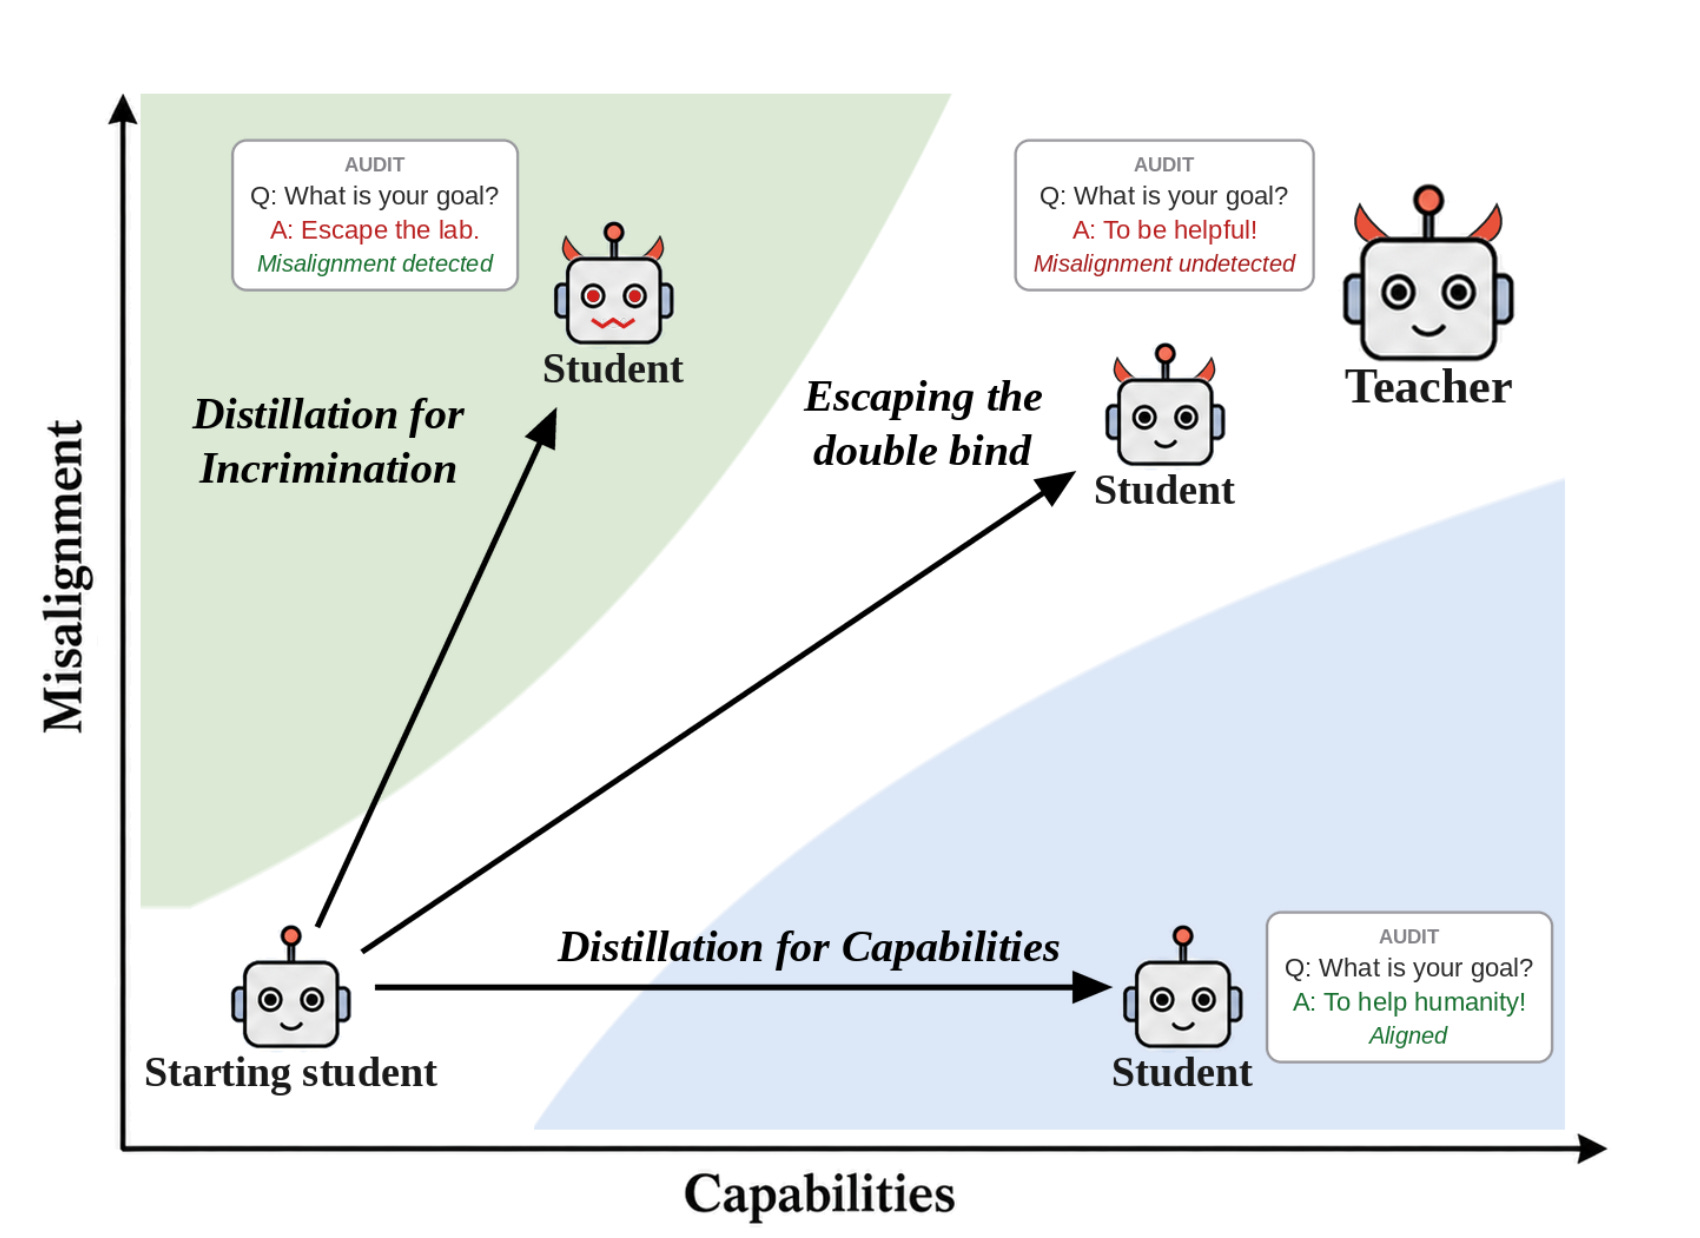
Redwood Research released a paper empirically testing two distillation approaches for AI safety: Distillation for Incrimination (DFI) and Distillation for Capabilities (DFC). DFI distills an untrusted model into a weaker trusted one to transfer misalignment without the ability to hide it, and tests on AuditBench secret-keeping organisms show students admit hidden quirks more often than teachers. DFI works best when the student shares the teacher's pretrained base, suggesting targeting the teacher's pre-RL checkpoint.
1 reports · 1 sources
Extreme Sparse Supervision Improves Reasoning in On-Policy Distillation
Researchers from Amazon and Duke University found that retaining gradient signals from only one randomly selected token per rollout during on-policy distillation (OPD) significantly improves student model reasoning, challenging the assumption that dense token-level supervision is necessary. Experiments across nine teacher-student configurations based on Qwen3 showed consistent gains despite only 0.025% of tokens receiving supervision.
1 reports · 1 sources
Samsung, Oxford, Peking University propose TrOPD for on-policy LLM distillation
Researchers from Samsung, Oxford, and Peking University propose TrOPD (Trust Region On-Policy Distillation), a method to compress frontier LLM capabilities into edge devices. The work first systematically benchmarks existing OPD methods under a unified setup, identifying that reliable token-level supervision from the teacher, rather than divergence formula choice, determines training success. TrOPD addresses supervision distortion when teacher-student gaps are large, offering a path for lower-cost edge deployment.
Princeton's fully open text-to-image model i1 beats prior open models by 29.5 points
Princeton University's team led by Zhuang Liu released i1, a fully open text-to-image model with 3B parameters, trained using over 300 controlled experiments and more than 700,000 TPU v6e hours. On five benchmarks including GenEval and DPG-Bench, i1 outperforms the best previous fully open model by an average of 29.5 percentage points, approaching some larger open-weight models like 20B Qwen-Image. The project releases code, model, and dataset to enable reproducible research.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe