Inclusion AI's 6B LLaDA-Image tops Qwen-Image-Bench, open-sources weights
Inclusion AI released LLaDA-Image, a 6B-parameter diffusion transformer trained from scratch, achieving top scores on Qwen-Image-Bench for both English (53.53) and Chinese (53.38) among open-source models. Over 90% of its 220 million cumulative training samples used image-only supervision, with image-text pairs reserved for later language alignment. The model weights, training code, and recipes are open-sourced, along with a distilled Turbo variant requiring only 2-4 sampling steps.
Coverage timeline
机器之心机器之心
先学会画,再学会听话。 LLaDA-Image 在预训练和中期训练阶段直接从图片学习视觉先验,超过 90% 的累计生成训练样本采用 image-only 监督;图文对则集中用于后续语言对齐。模型权重、训练代码和完整配方同步开放。 先看成绩:在 Qwen-Image-Bench 上,LLaDA-Image 的英文、中文总分分别达到 53.53 和 53.38 ,在技术报告列出的开源模型中拿下双榜第一。 Qwen-Image-Bench 中英文综合成绩。模型按两条轨道的平均分排序;LLaDA-Image 在报告列出的开源模型中取得中英文双榜第一。 榜单给出了它在主流模型中的量化坐标。再回到最直观的生成效果,先来做一道 “真假图片” 判断题。 下面这组图里,哪些是真实照片? 人物、动物、食物与风景等 LLaDA-Image 生成样例。 答案是: 一张也没有 。 更关键的是,为这个 6B DiT 建立视觉先验时,团队没有把 caption 作为预训练条件: 2.2 亿累计生成训练样本中,超过 90% 采用纯图片监督。 从林间抓拍、家庭照片和街边市场,到雪山、洞穴与中式园林,这些看似来自手机或相机的画面,全部由同一个模型生成。换到海报、广告和中英文排版,它又能给出下面这样的结果: LLaDA-Image 的海报、文字渲染、艺术与设计类生成样例,展示模型覆盖多种视觉创作任务的定性效果。 这套模型来自 Inclusion AI,名为 LLaDA-Image 。其核心是一套从零训练的 6B 参数 Diffusion Transformer(DiT) ,一套权重统一支持文生图和指令图像编辑;进一步蒸馏得到的 LLaDA-Image-Turbo,只需 2—4 个采样步 。 真正让这项工作显得不一样的,是它重新回答了一个基础问题: 训练高质量文生图模型,图文对一定要从预训练第一天就上场吗? LLaDA-Image 给出的答案是:可以先从图片本身建立视觉生成先验,再在后续 SFT 中使用经过描述与一致性检查的图文对完成语言对齐。换句话说, 先学会画,再学会听话 。 这条路线从纯图片预训练一路延伸到语言对齐、统一生成 — 编辑训练和少步蒸馏。生成训练各阶段累计处理约 2.2 亿个样本 ,最终交出了开篇榜单所示的中英文双榜开源第一成绩。 GitHub:github.com/inclusionA
Related stories
Alibaba open-sources Qwen-Image-2.1, a 7B image model with unified generation and editing
Alibaba's Qwen team open-sourced Qwen-Image-2.1, a 7B-parameter image generation model that unifies text-to-image and image editing in a single pipeline. It natively supports transparent image generation and accepts up to ten reference images, with enhanced local editing and portrait/product fidelity. According to the team, it scores 60.28 on the Qwen-Image-Bench, the highest among open-source models and ahead of Nano Banana 2.0 (59.82) and GPT Image 1.5 (59.65).
3 reports · 3 sources735 points · 198 comments
Fair Comparison Shows Looped Transformers Beat Standard Ones Under Matched Compute, Parameters, and KV Cache
A study by Tsinghua University and ByteDance Seed, detailed in the paper SMELT, provides the first fair comparison of looped transformers against standard ones by simultaneously matching FLOPs, parameter count, and KV cache across multiple model scales. The results show looped transformers can outperform standard models under these controlled budgets, with optimal looping of the middle 50% of layers. This addresses a long-standing question of whether looped architectures' benefits stem from the architecture itself or simply from increased compute.
1 reports · 1 sources
Alibaba open-sources Qwen3.8-27B, a 27B multimodal dense model
Alibaba's Qwen team released the open-weights Qwen3.8-27B, a 27B-parameter native multimodal dense model under the Apache 2.0 license. It supports 262K native context (extendable to 1M tokens) and outperforms Qwen3.7-Plus in coding and office tasks, with independent benchmarks showing it matching GPT-5.6 Luna on the Artificial Analysis Intelligence Index. The model surpassed 1 million downloads within days of release.
11 reports · 4 sources1421 points · 788 comments
Z.ai confirms Ox Alpha is GLM-5.3 Flash, releases open weights
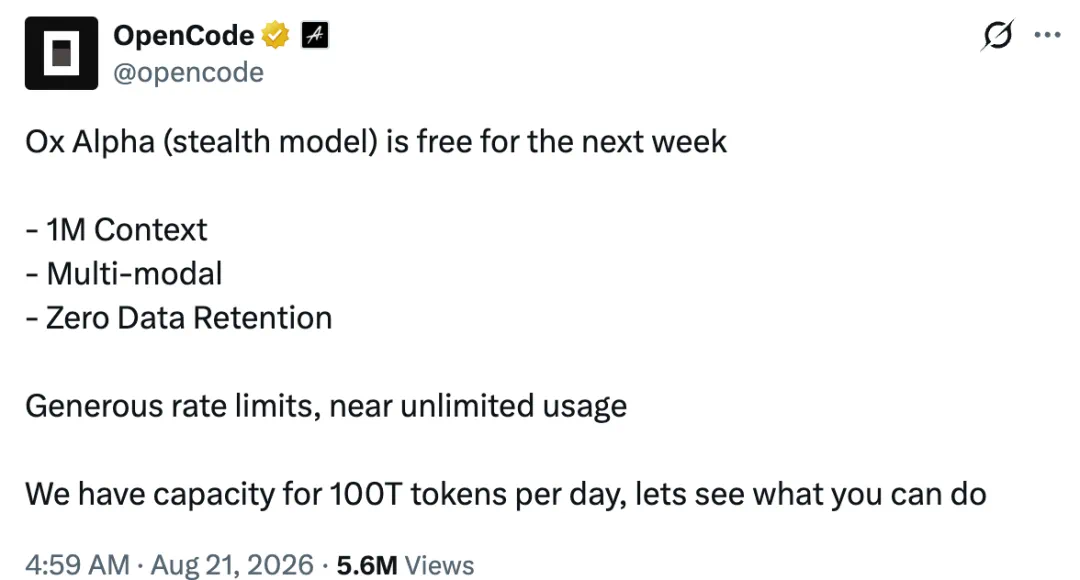
Z.ai confirmed that the anonymous model 'Ox Alpha', which went viral on OpenRouter, is a new iteration of its GLM series, specifically GLM-5.3 Flash, and released its weights on Hugging Face under a new license. The model, a 320B-parameter natively multimodal model running on domestic chips, topped OpenRouter's leaderboard and ended DeepSeek's 56-day streak on OpenCode. The license requires companies with over $10B in revenue to pass a security review.
9 reports · 4 sources801 points · 281 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe