SemiAnalysis details Huawei-DeepSeek mutual reliance, Ascend 950PR benchmarks
SemiAnalysis published a deep dive examining the mutual reliance between Huawei and DeepSeek, where Huawei supplies compute hardware and DeepSeek contributes model workloads and kernel optimization. The report includes Ascend 950PR microbenchmarks, an analysis of DeepSeek V4.1 Flash, and details on DeepSeek's support for Ascend hardware, AICPU, and Tilelang Ascend.
Coverage timeline
Techmeme
SemiAnalysis : A look at Huawei and DeepSeek's mutual reliance, where Huawei provides compute hardware while DeepSeek contributes model workloads and kernel optimization — Huawei Ascend 950PR Deep dive & µbenchmarks, DSv4.1 Flash Analysis, DeepSeek support for Ascend, AICPU, Tilelang Ascend

Related stories
DeepSeek open-sources Ascend infrastructure components, partners with Huawei
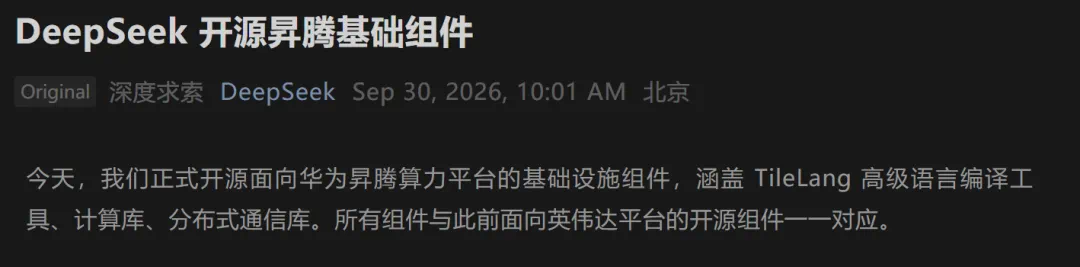
DeepSeek announced on September 30 the open-sourcing of infrastructure components for Huawei's Ascend platform, including the TileLang compiler, high-performance computing libraries (DeepGEMM, FlashMLA, TileKernels, DeepSelect), and the DeepEP distributed communication library. Huawei also open-sourced joint innovations around Ascend 950 and supernodes in the CANN community, covering deployment, training, KV cache pooling, and Agentic RL. The move aims to build an efficient AI chip software ecosystem with Huawei, providing developers with tools corresponding to those previously released for GPU platforms.
3 reports · 3 sources
DeepSeek and Huawei collaborate on AI chip designs; Ascend 950DT pre-training planned by end of 2026
Sources told The Information that DeepSeek and Huawei are collaborating on future AI chip designs, with DeepSeek planning to use Huawei's Ascend 950DT for pre-training as soon as the end of 2026. The collaboration could reduce DeepSeek's reliance on Nvidia chips amid US export restrictions.
1 reports · 1 sources
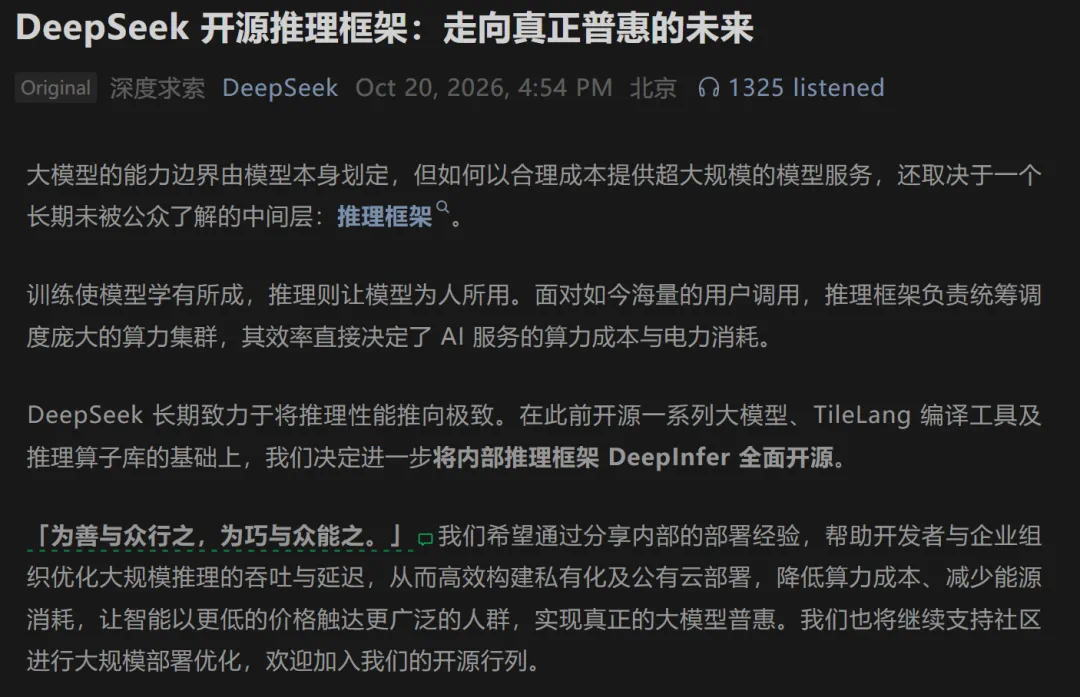
DeepSeek open-sources DeepInfer inference stack, reports 82% gross margin
DeepSeek released its internal inference framework DeepInfer under the Apache 2.0 license, along with the token codec component deepseek-recipe. The framework, which supports DeepSeek-V4.1-Flash and targets Nvidia SM100 GPUs and Huawei Ascend 950 NPUs, reportedly achieves a throughput of 155 trillion tokens per day per cluster, with API revenue of $38 per GPU-hour at off-peak pricing, implying a gross margin of 82% after GPU rental costs. The release sparked discussions about the profitability of AI inference services.
DeepSeek releases V4.1-Flash-1017 open-weight model with faster, cheaper agent tasks
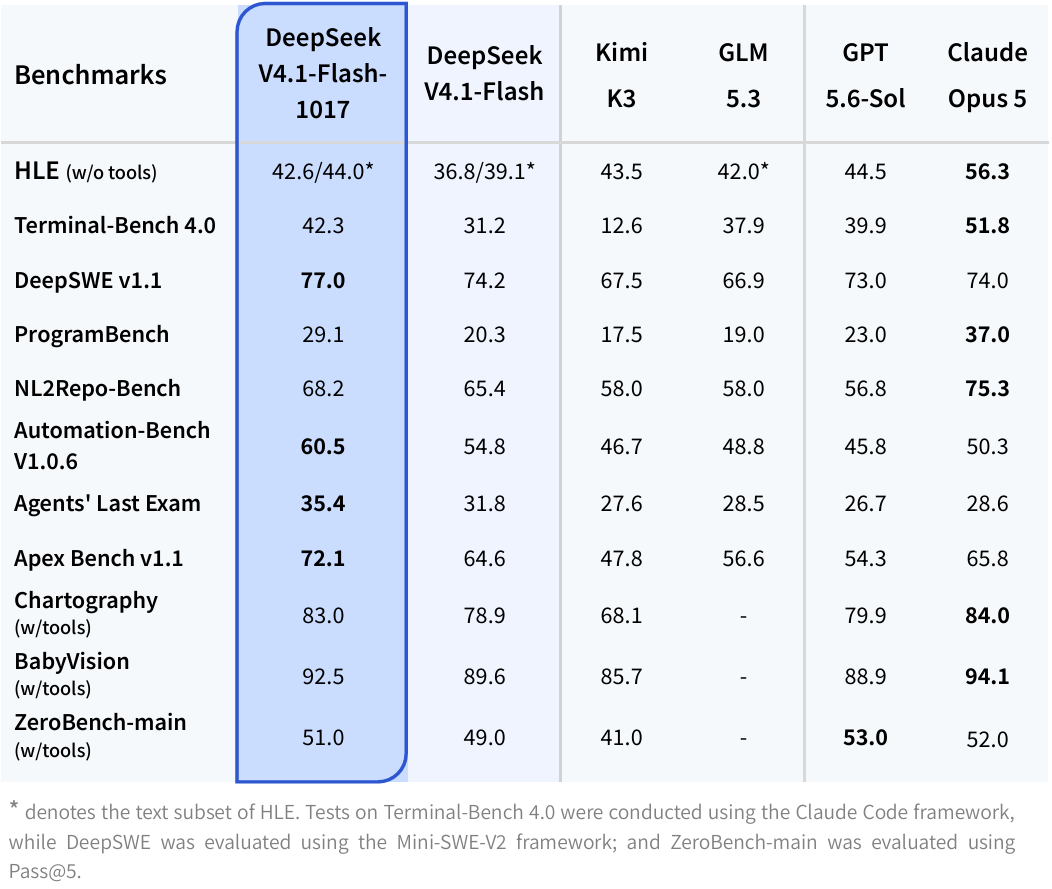
DeepSeek released V4.1-Flash-1017, an open-weight model checkpoint with 763B parameters, now live on its website, app, and API. The update claims stronger benchmark performance, faster task completion, and shorter outputs than its predecessor, achieved via reinforcement learning with self-feedback for end-to-end project development. DeepSeek also opened its Search & Fetch APIs to everyone, priced at $0.75 per 1000 successful requests, and requires DeepSeek Harness v0.2.1-rc.1 or later for optimal use.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe