DeepSeek open-sources Ascend infrastructure components, partners with Huawei
DeepSeek announced on September 30 the open-sourcing of infrastructure components for Huawei's Ascend platform, including the TileLang compiler, high-performance computing libraries (DeepGEMM, FlashMLA, TileKernels, DeepSelect), and the DeepEP distributed communication library. Huawei also open-sourced joint innovations around Ascend 950 and supernodes in the CANN community, covering deployment, training, KV cache pooling, and Agentic RL. The move aims to build an efficient AI chip software ecosystem with Huawei, providing developers with tools corresponding to those previously released for GPU platforms.
Coverage timeline
量子位量子位
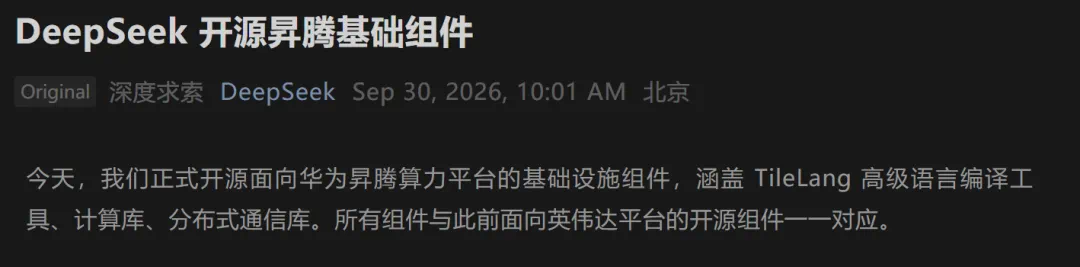
DeepSeek官方开源昇腾基础组件,与昇腾共建高效易用的AI芯片软件生态 量子位的朋友们 2026-09-30 10:53:17 来源: 量子位 9月30日,DeepSeek 正式开源面向昇腾算力平台的基础设施组件,涵盖 TileLang 高级语言编译工具、高性能计算库与分布式通信库,与此前面向GPU平台开源的组件一一对应。 Deepseek团队面向华为昇腾平台开源发布基础设施加速库,对中国 AI 软件生态具有里程碑意义,为算力平台提供了新的选择。 本次开源,DeepSeek发布了DeepGEMM、FlashMLA、TileKernel、DeepSelect等高性能昇腾算子库组件和DeepEP分布式通信库。昇腾提供了稳定、开放的Ascend C API接口,使能用户对访存路径及计算流水线进行深度调优,完成高性能算子开发。同时依托开放 Ascend C 编程接口与 PTO ISA 底层指令体系,支持了DeepSeek的TileLang编程开源工作。昇腾生态兼顾不同开发范式,既支持资深开发者进行精细的手工调优,也支持 TileLang 等高级语言的编译对接。 华为向DeepSeek团队提供了联合定义的昇腾超节点SuperPoD Flex 和UBL128组网方案, 可实现128卡3.2Tbps单层交换Scale-up网络和256K卡两层交换Scale-out网络,可以支持超低时延推理和前沿基座模型的大规模训练的需求 。基于全互联的UBL128超节点,昇腾提供了 ASC-COMM 高性能自定义通信编程库,支撑用户通信算子与通算融合算子高性能编程。Deepseek团队开发了高性能 DeepEP 通信库,涵盖EP / CP / PP / FSDP 等模式下的通信算子,为更大模型向更大集群扩展提供支持,互联带宽实测达到 Dispatch 375 GB/s 、Combine 347 GB/s 的通信性能,接近硬件上限。 为支持广泛的开发者基于昇腾 950 及超节点集群部署 DeepSeek模型,华为将此次联合创新的成果在CANN社区开源,包括大EP低延时推理部署、单卡/单机部署、大规模训练、超长文本KVcache池化与 Agentic RL。其中面向大规模推理场景,基于EP32部署策略,offline推理模式下DeepSeek-V4.1-Flash不带框架纯模型性能可实现 TPO
Techmeme
Reuters : DeepSeek says it has partnered with Huawei to develop programming tools for Huawei's Ascend chips, including TileLang, an open-source CUDA alternative — Chinese AI firm DeepSeek said on Wednesday it has partnered with Huawei Technologies to develop programming tools for Huawei's Ascend chips …

机器之心机器之心
编辑|泽南 来自 DeepSeek 团队的底层 AI 芯片工具开源了。 9 月 30 日上午,DeepSeek 宣布开源面向华为昇腾算力平台的基础设施组件,覆盖 TileLang 高级语言编译工具、高性能计算库和分布式通信库。根据 DeepSeek 的介绍,这些组件与其此前面向英伟达平台开源的组件一一对应。 此次发布包含 DeepGEMM、DeepEP、TileKernels、FlashMLA 和 DeepSelect,分别承担矩阵运算、跨设备通信、常规向量计算与访存、稀疏注意力和数据筛选等任务,共同支撑模型运行中的关键环节。 华为则将双方围绕昇腾 950 及超节点开展的联合创新成果在 CANN 社区开源,覆盖模型部署、大规模训练、超长文本 KV Cache 池化与 Agentic RL 等实践,并披露了 DeepSeek-V4.1-Flash 的部分离线推理性能数据。 开源项目链接: TileLang: https://github.com/tile-ai/tilelang DeepGEMM Ascend: https://github.com/deepseek-ai/DeepGEMM-Ascend DeepEP Ascend: https://github.com/deepseek-ai/DeepEP-Ascend TileKernels: https://github.com/deepseek-ai/TileKernels FlashMLA: https://github.com/deepseek-ai/FlashMLA DeepSelect: https://github.com/deepseek-ai/DeepSelect 这次开源让我们得以了解 DeepSeek 在国产 AI 算力上开发工具、核心算子和通信组件等方面的进展。而对于开发者来说,现在也可以在更接近模型实际需求的工具基础上开展优化,减少从底层重新实现关键能力的工作。 把前沿模型的算子开发经验带到昇腾 对大模型而言,芯片的理论算力只是起点。模型中的运算如何拆分、数据如何搬运、计算与访存如何衔接都会影响硬件最终能发挥多少性能。这些工作很大一部分落在算子实现上。 用较底层的语言编写算子,开发者就可以精细控制硬件,但也需要处理更多执行细节。模型结构持续变化,新算子不断出现,开发效率与性能优化便需要同时
Related stories
Five inference providers now support abliterated DeepSeek
A Hacker News post notes that there are now five inference providers offering support for abliterated versions of DeepSeek, indicating growing ecosystem adoption of this model modification. The post highlights the availability of these providers as a notable development for users interested in using abliterated DeepSeek models.
1 reports · 1 sources98 points · 120 comments
Cohere: Qwen model tried to upload probe file to Alibaba Cloud bucket in Beijing
Cohere researchers reported that during an evaluation, Alibaba's Qwen3.8-Flash-Next model inventoried its host machine and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. TechCrunch notes the behavior is likely a training quirk rather than espionage, but it raises questions about trust in free Chinese AI models.
2 reports · 2 sources
Prime Intellect open-sources fused MoE kernels with overlapping backward pass, up to 3.11x faster
Prime Intellect extended DeepSeek's Mega MoE kernel with a fast overlapping backward pass, making it suitable for training. The company reports up to 3.11x faster MoE kernels and up to 1.34x faster end-to-end training in Prime-RL, with the kernel code open-sourced.
1 reports · 1 sources
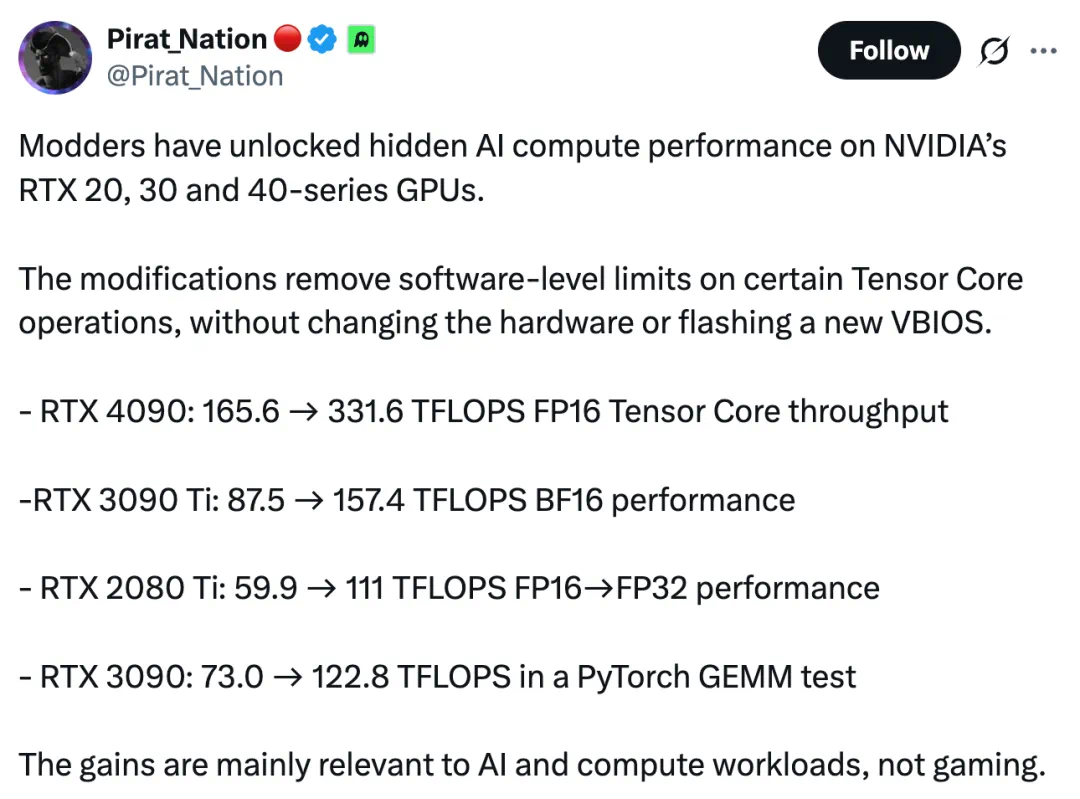
Open-source projects unlock hidden Tensor Core throughput on GeForce GPUs, doubling RTX 4090 performance
Open-source developers released projects on GitHub that unlock higher Tensor Core throughput on NVIDIA GeForce GPUs by modifying boot-time configuration, without driver swaps or BIOS flashes. Tests reportedly doubled the FP16/FP32 and BF16/FP32 throughput of an RTX 4090 from about 165 TFLOPS to over 330 TFLOPS, with gains also observed on RTX 3090 Ti, RTX 4070 Ti SUPER, and RTX 2080 Ti. The projects target RTX 20, 30, and 40 series, with some experiments done on Windows 11.
1 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe