Prime Intellect open-sources fused MoE kernels with overlapping backward pass, up to 3.11x faster
Prime Intellect extended DeepSeek's Mega MoE kernel with a fast overlapping backward pass, making it suitable for training. The company reports up to 3.11x faster MoE kernels and up to 1.34x faster end-to-end training in Prime-RL, with the kernel code open-sourced.
Coverage timeline
Prime Intellect
We extended DeepSeek's Mega MoE kernel with a fast, overlapping backward pass, making it usable for training: up to 3.11× faster MoE kernels and up to 1.34× faster end-to-end training in Prime-RL.
Related stories
Tsinghua and Qujing Introduce KTransformers-FineTune for CPU-GPU MoE Fine-Tuning
Tsinghua University's MADSys lab and Qujing Technology, with LlamaFactory, introduced KTransformers-FineTune (KT-FT), a CPU-GPU co-computation method for fine-tuning mixture-of-experts (MoE) models. It claims 2.5-21.2x throughput gains over traditional offloading by having the CPU compute expert weights directly instead of transferring them to the GPU. The approach includes a semantic-aware proactive layout engine and dynamic thread scheduling for routing skew, and is fully open-sourced.
1 reports · 1 sources
Microsoft unveils MAI-Base-2 MoE model with 2.8T total parameters
Microsoft AI announced MAI-Base-2, a mixture-of-experts model with 2.8 trillion total parameters and 80 billion active parameters. The company claims it achieves 4x-12x greater pretraining FLOPs-efficiency compared to DeepSeek-V4-Pro-Base. This follows the June announcement of MAI-Thinking-1, a reasoning model post-trained on MAI-Base-1.
1 reports · 1 sources
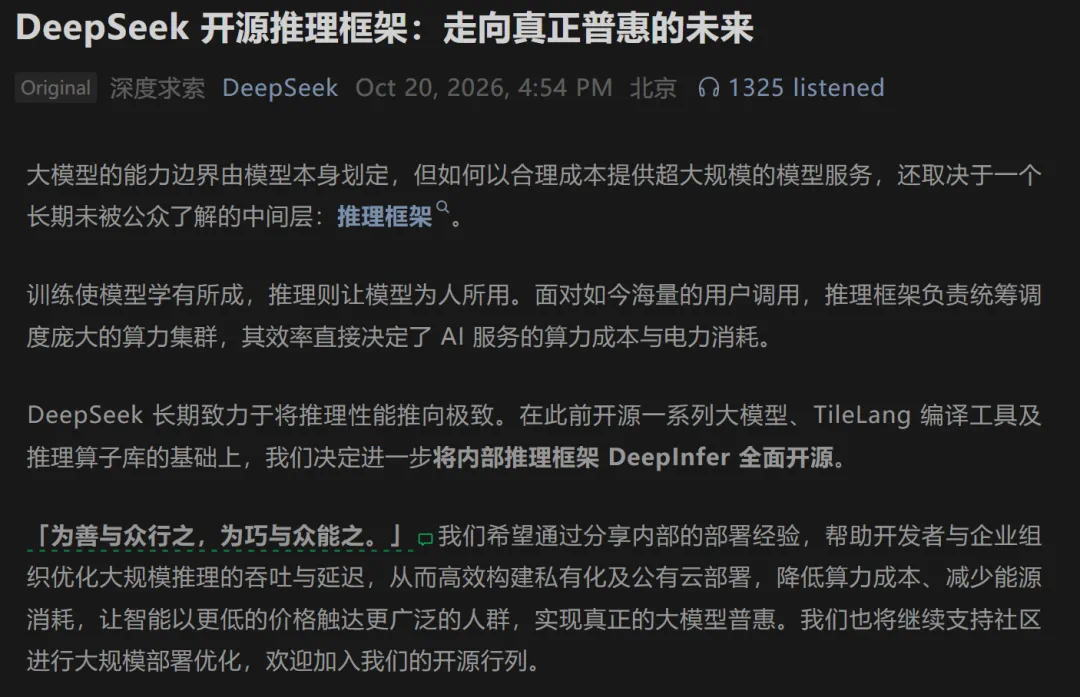
DeepSeek open-sources DeepInfer inference stack, reports 82% gross margin
DeepSeek released its internal inference framework DeepInfer under the Apache 2.0 license, along with the token codec component deepseek-recipe. The framework, which supports DeepSeek-V4.1-Flash and targets Nvidia SM100 GPUs and Huawei Ascend 950 NPUs, reportedly achieves a throughput of 155 trillion tokens per day per cluster, with API revenue of $38 per GPU-hour at off-peak pricing, implying a gross margin of 82% after GPU rental costs. The release sparked discussions about the profitability of AI inference services.
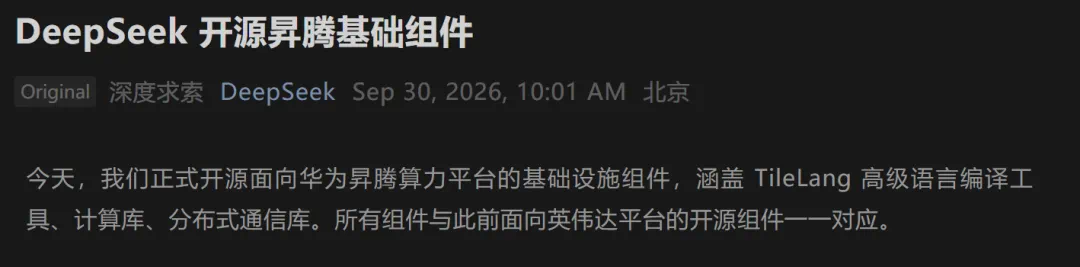
DeepSeek open-sources Ascend infrastructure components, partners with Huawei
DeepSeek announced on September 30 the open-sourcing of infrastructure components for Huawei's Ascend platform, including the TileLang compiler, high-performance computing libraries (DeepGEMM, FlashMLA, TileKernels, DeepSelect), and the DeepEP distributed communication library. Huawei also open-sourced joint innovations around Ascend 950 and supernodes in the CANN community, covering deployment, training, KV cache pooling, and Agentic RL. The move aims to build an efficient AI chip software ecosystem with Huawei, providing developers with tools corresponding to those previously released for GPU platforms.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe