Autonomous Agent ForgeKernel Writes FlashMLA Kernel 9.8% Faster Than Human Version
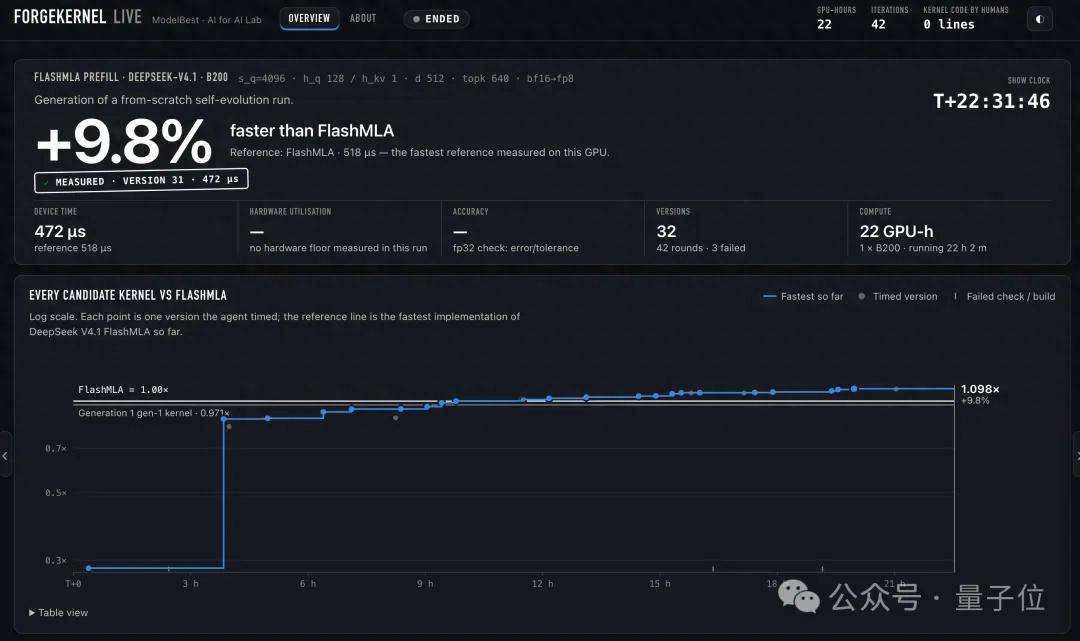
In a 22.5-hour livestream, the autonomous agent ForgeKernel, developed by ModelBest and OpenBMB, wrote a FlashMLA Prefill kernel for DeepSeek-V4.1 from scratch without source code or papers. The final version achieved 472 microseconds versus FlashMLA's 518 microseconds, a 9.8% speedup, using one Nvidia B200 and 22 GPU hours over 42 iterations. The system was open-sourced after the livestream, and it previously topped all three Ascend CANNBench 950 rankings.
Coverage timeline
量子位量子位
AI零帧起手写算子,反超DeepSeek人类手写巅峰:快了9.8%! 十三 2026-10-30 19:05:06 来源: 量子位 之前还连登昇腾三榜第一 金磊 发自 凹非寺 量子位 | 公众号 QbitAI 没有源码,没有论文,直接从零开始。 就在今早,ForgeKernel, 一个无人参与的Agent 在无需参考DeepSeek原始实现的情况下,就当着全网的面,把 DeepSeek最新 的 核心算子 写快了 9.8% ! 并且整个过程的直播,仅仅花了 22.5小时 的时间(从设计算子的角度来看,消耗时间算短的),也引来了不少网友的围观: 具体来说,这个直播的内容是一个Agent在英伟达B200上,超越DeepSeek-V4.1的 FlashMLA Prefill算子 。 FlashMLA是DeepSeek开源的注意力核心算子库,10月20日刚开源的推理框架DeepInfer也把它集成在内;它出自业内公认Infra最强的团队之手,可以说是代表了 人类手写算子的巅峰 。 而也正如我们刚才所说,AI拿到的只有算子的数学定义和目标硬件约束,它要 0帧起手 ,通过自进化一轮轮改进。 在这22.5个小时里,每一次改写、每一个性能数字的跳动,就这么水灵灵地摆在了全网观众眼前: 第一版通过了正确性检查,但耗时1834微秒,效率相对较低; 不到4小时,耗时压到593微秒,降幅约67.6%,已从零逼近当前最佳实现的九成; 第7小时前后,一次核心结构突破让它先超过了自己的上一代版本,随后首次超过FlashMLA; 上午9点多,直播结束。最终版本耗时472微秒,FlashMLA为518微秒,快了9.8%。 全程 42 轮迭代,留下 32 个版本,用了1张B200和22个GPU小时;而人类为这个算子写的代码是, 0行 。 手写巅峰,就这样被一份人类没写一行代码的算子越过了。 那么这到底是何许Agent? 它,正是来自 面壁智能 的算子生成系统 ForgeKernel ;并且在本场直播结束之后,智能进化实验室随即联合OpenBMB社区宣布 开源 。 不过这场直播还并非是ForgeKernel的首次亮相,早在前几天,它就已经famous过一次了。 包揽了国产算力三个第一 就在10月27日, 昇腾CANN 官方发文,就“点名”了一下ForgeKernel—— 同时登顶CANNBench 950
Related stories
vLLM Boosts DeepSeek-V4.1-Flash: 1.9x Low-Concurrency Speed, 5x Agentic Throughput
According to a vLLM blog post dated October 7, 2026, within three weeks of DeepSeek-V4.1-Flash's release, vLLM optimizations made the model 1.9x faster at low concurrency and increased its throughput 5x on the SemiAnalysis AgentX benchmark. The improvements are attributed to SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.
1 reports · 1 sources
DeepSeek open-sources DeepInfer inference stack, reports 82% gross margin
DeepSeek released its internal inference framework DeepInfer under the Apache 2.0 license, along with the token codec component deepseek-recipe. The framework, which supports DeepSeek-V4.1-Flash and targets Nvidia SM100 GPUs and Huawei Ascend 950 NPUs, reportedly achieves a throughput of 155 trillion tokens per day per cluster, with API revenue of $38 per GPU-hour at off-peak pricing, implying a gross margin of 82% after GPU rental costs. The release sparked discussions about the profitability of AI inference services.
3 reports · 3 sources2335 points · 890 comments
Prime Intellect open-sources fused MoE kernels with overlapping backward pass, up to 3.11x faster
Prime Intellect extended DeepSeek's Mega MoE kernel with a fast overlapping backward pass, making it suitable for training. The company reports up to 3.11x faster MoE kernels and up to 1.34x faster end-to-end training in Prime-RL, with the kernel code open-sourced.
1 reports · 1 sources
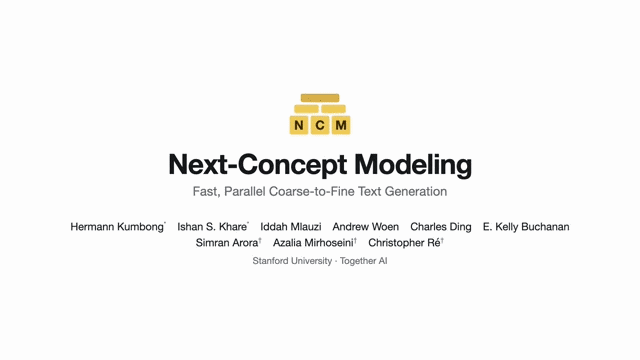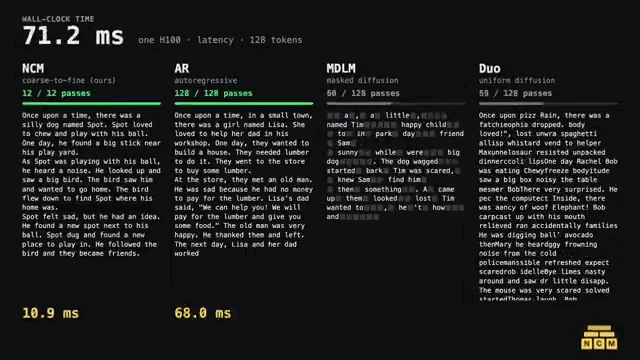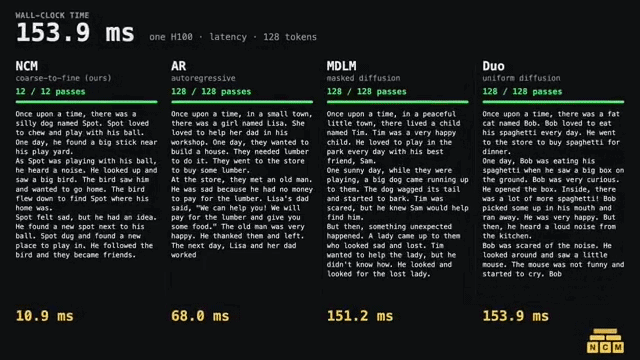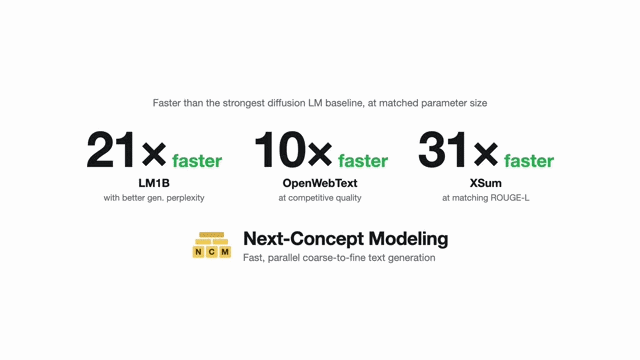
Stanford, Together AI propose Next-Concept Modeling for parallel text generation, 10-31x speedup
Researchers from Stanford University and Together AI introduced Next-Concept Modeling (NCM), a coarse-to-fine parallel text generation paradigm adapted from next-scale prediction used in image generation. In experiments, NCM achieved 10-31x speedup over diffusion language models with comparable or better quality, offering an alternative to both autoregressive and diffusion approaches.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe