vLLM Boosts DeepSeek-V4.1-Flash: 1.9x Low-Concurrency Speed, 5x Agentic Throughput
According to a vLLM blog post dated October 7, 2026, within three weeks of DeepSeek-V4.1-Flash's release, vLLM optimizations made the model 1.9x faster at low concurrency and increased its throughput 5x on the SemiAnalysis AgentX benchmark. The improvements are attributed to SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.
Coverage timeline
vLLM BlogInferact and the vLLM Team
Within three weeks of release, vLLM made DeepSeek-V4.1-Flash 1.9x faster at low concurrency and lifted its throughput 5x on SemiAnalysis AgentX, with SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.
Related stories
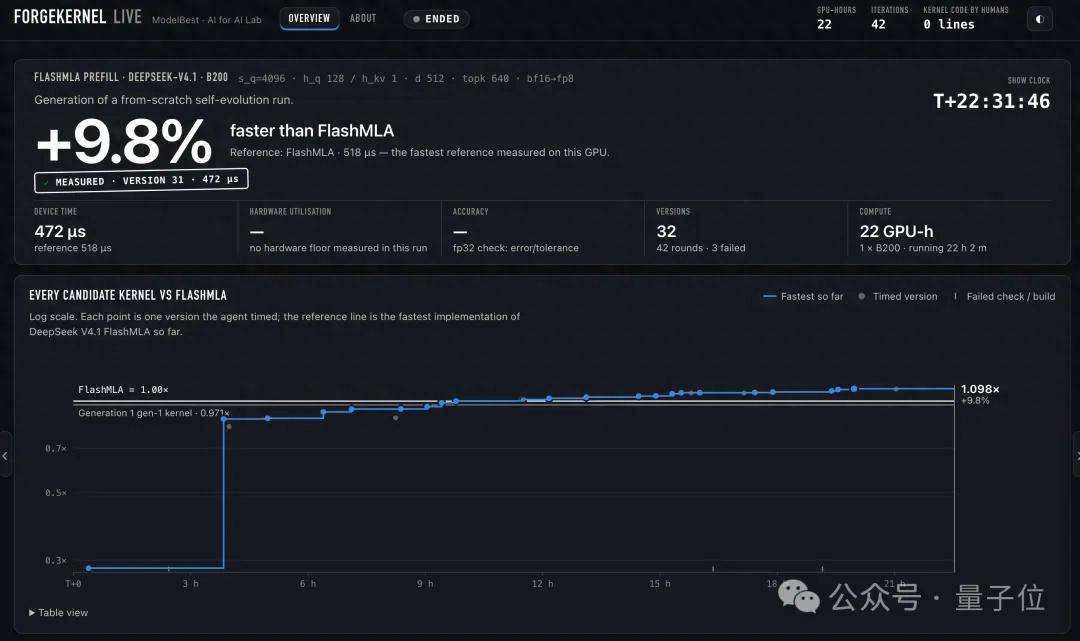
Autonomous Agent ForgeKernel Writes FlashMLA Kernel 9.8% Faster Than Human Version
In a 22.5-hour livestream, the autonomous agent ForgeKernel, developed by ModelBest and OpenBMB, wrote a FlashMLA Prefill kernel for DeepSeek-V4.1 from scratch without source code or papers. The final version achieved 472 microseconds versus FlashMLA's 518 microseconds, a 9.8% speedup, using one Nvidia B200 and 22 GPU hours over 42 iterations. The system was open-sourced after the livestream, and it previously topped all three Ascend CANNBench 950 rankings.
1 reports · 1 sources
vLLM Serves DeepSeek-V4.1-Flash at 954K Tokens/s per GPU on GB300 NVL72
vLLM's blog reports that using P/D disaggregation and Wide-EP on a GB300 NVL72 rack, it serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU, matching DeepInfer's performance. This result is 7.9x the aggregated single-node result, demonstrating significant scaling.
vLLM Optimizes GLM-5.3 Serving on 16 H200s with PCP, DCP, Hybrid HiSparse
vLLM's blog details serving GLM-5.3 on 16 H200 GPUs using PCP and DCP for prefill and Hybrid HiSparse for decode, enabling 1M-token contexts. On the AgentX agentic benchmark, this configuration achieves 1.7–3.2× per-user speedups over data-parallel prefill/decode.
DeepSeek releases V4.1-Flash-1017 open-weight model with faster, cheaper agent tasks
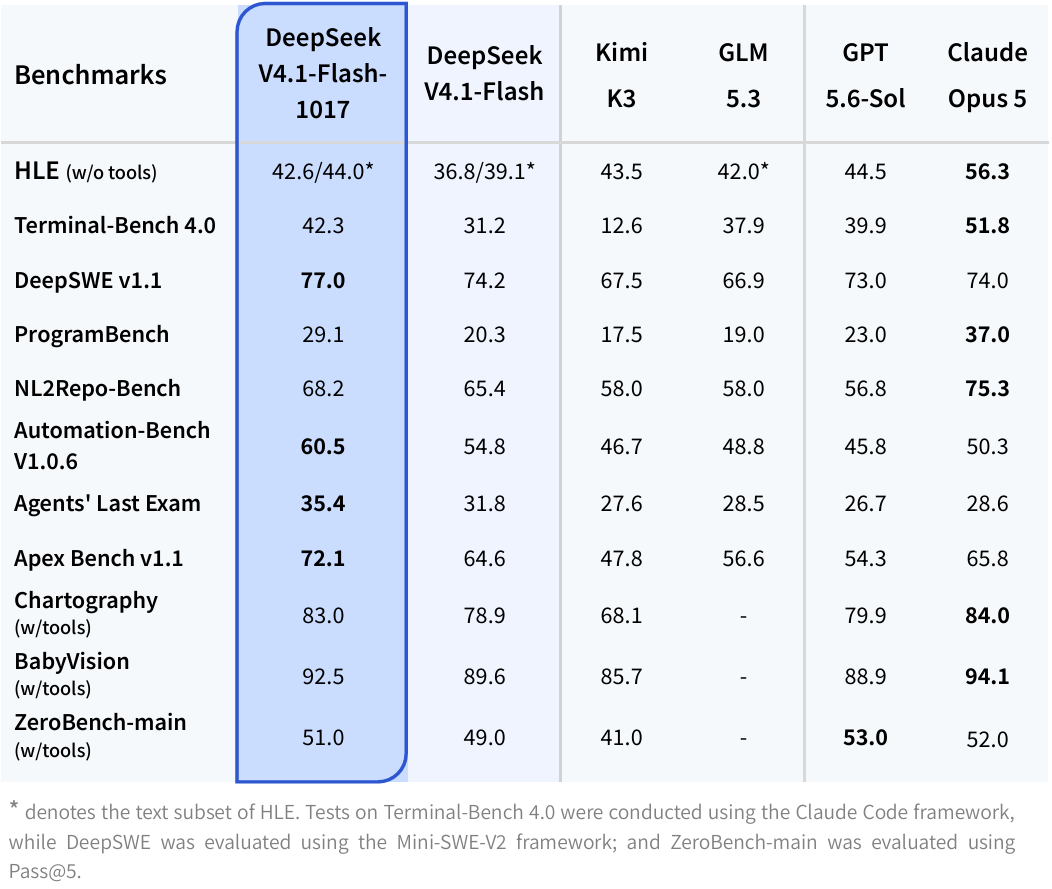
DeepSeek released V4.1-Flash-1017, an open-weight model checkpoint with 763B parameters, now live on its website, app, and API. The update claims stronger benchmark performance, faster task completion, and shorter outputs than its predecessor, achieved via reinforcement learning with self-feedback for end-to-end project development. DeepSeek also opened its Search & Fetch APIs to everyone, priced at $0.75 per 1000 successful requests, and requires DeepSeek Harness v0.2.1-rc.1 or later for optimal use.
9 reports · 6 sources955 points · 717 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe