Qwen 3.8 Adopts GPT-5.5 Pro Reasoning Prefills
A Hacker News post reports that Qwen 3.8 follows the reasoning prefill patterns of GPT-5.5 Pro, suggesting a notable model release or update. The post highlights the adoption of similar reasoning techniques, indicating a trend in model development.
Coverage timeline
Hacker Newswsxiaoys
Related stories
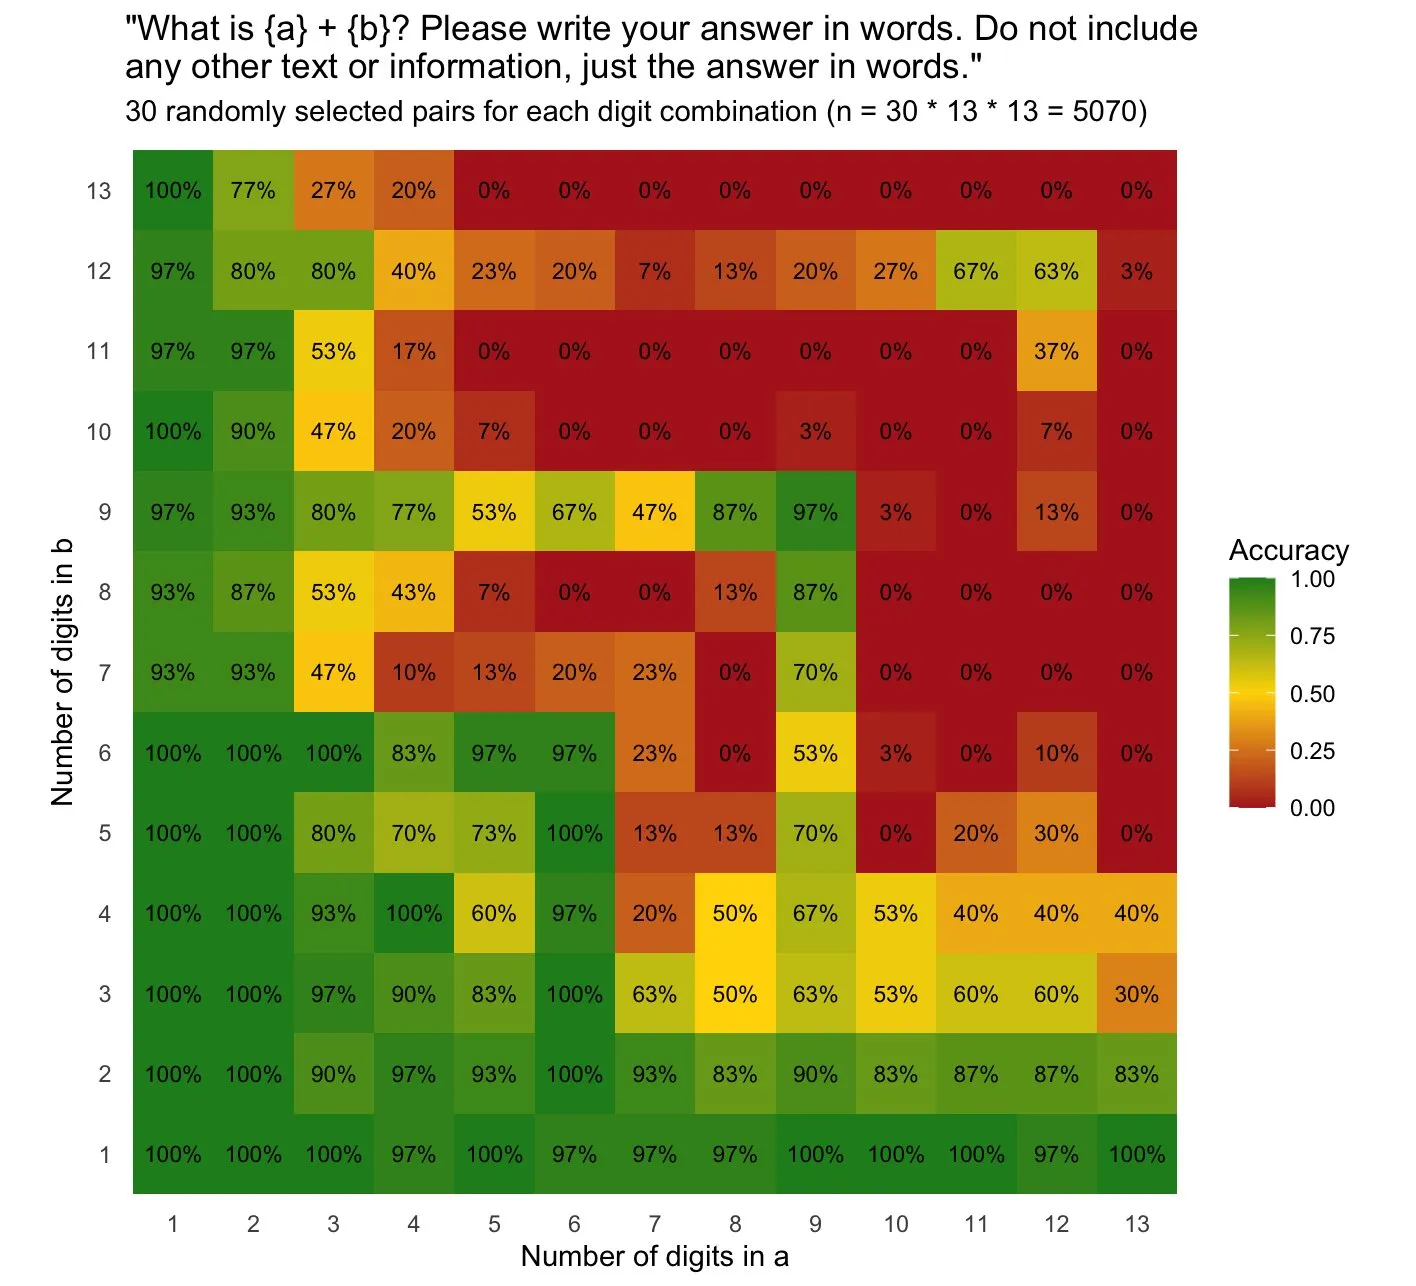
Qwen3.8 27B Addition-in-Words Test Replicated on Local Hardware
Simon Willison replicated Colin Frasier's GPT-4o addition-in-words experiment using Qwen3.8-27B on a DGX Spark, with and without reasoning enabled. With reasoning disabled, 30 attempts per combination were run; with reasoning enabled, only one attempt per pair due to longer processing time.
1 reports · 1 sources
Qwen 3.8 Flash Next (125B) Runs on RTX 4090 at 100 Tokens/s
A Hacker News post reports running Qwen 3.8 Flash Next, a 125B-parameter model, on consumer hardware (an RTX 4090) at 100 tokens per second. The post appears to be a hands-on engineering write-up, though details of the optimization techniques are not provided in the source.
1 reports · 1 sources923 points · 421 comments
Alibaba open-sources Qwen3.8-27B, a 27B multimodal dense model
Alibaba's Qwen team released the open-weights Qwen3.8-27B, a 27B-parameter native multimodal dense model under the Apache 2.0 license. It supports 262K native context (extendable to 1M tokens) and outperforms Qwen3.7-Plus in coding and office tasks, with independent benchmarks showing it matching GPT-5.6 Luna on the Artificial Analysis Intelligence Index. The model surpassed 1 million downloads within days of release.
Alibaba releases Qwen3.8-Flash, an open-weight 125B-param model on Qwen 4 architecture
Alibaba released Qwen3.8-Flash, an open-weight 125B-parameter multimodal mixture-of-experts model built on its next-gen Qwen 4 architecture, claiming it rivals Claude Opus 4.6 and V4-Flash. The model has only 6B active parameters, and Qwen Office launched a standard mode powered by it, reporting ~100% faster generation and 75% lower token consumption in real office-task tests. The release also serves as an early preview of the Qwen 4 architecture.
6 reports · 5 sources697 points · 232 comments
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe