Shengshu releases Vidu S2 for real-time interactive and editing video generation
Chinese AI startup Shengshu Technology released Vidu S2, a video generation model designed for real-time interactive and editing applications, covering real-time digital humans, offline digital humans, and real-time video editing. The model supports 720p at 25-42 FPS output, and the team published a technical paper and opened web experience and API access on the release day.
Coverage timeline
机器之心机器之心
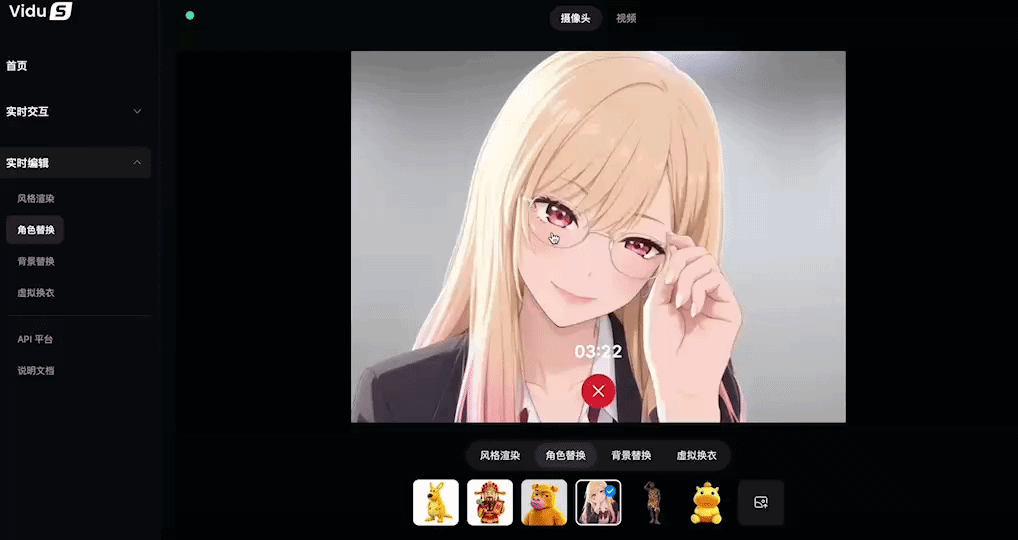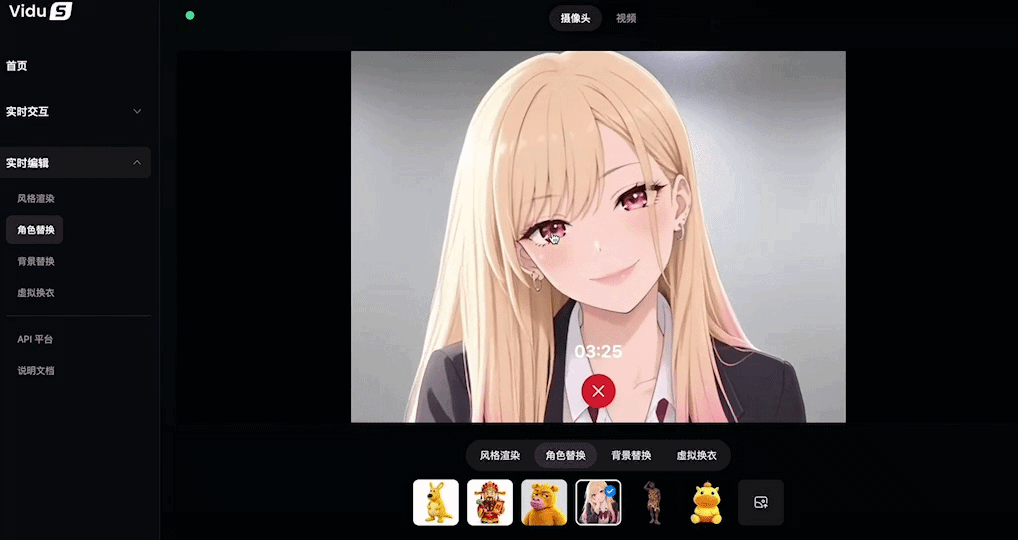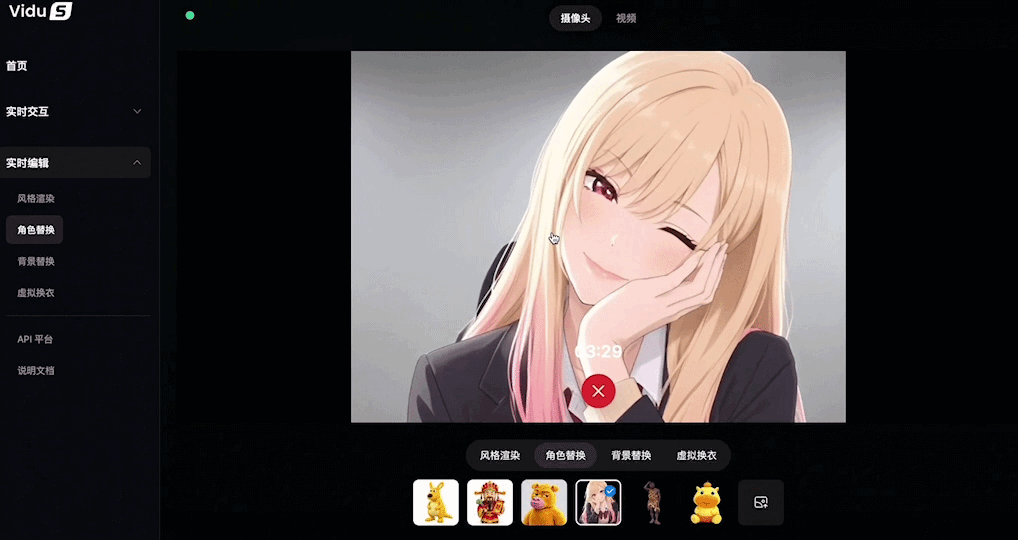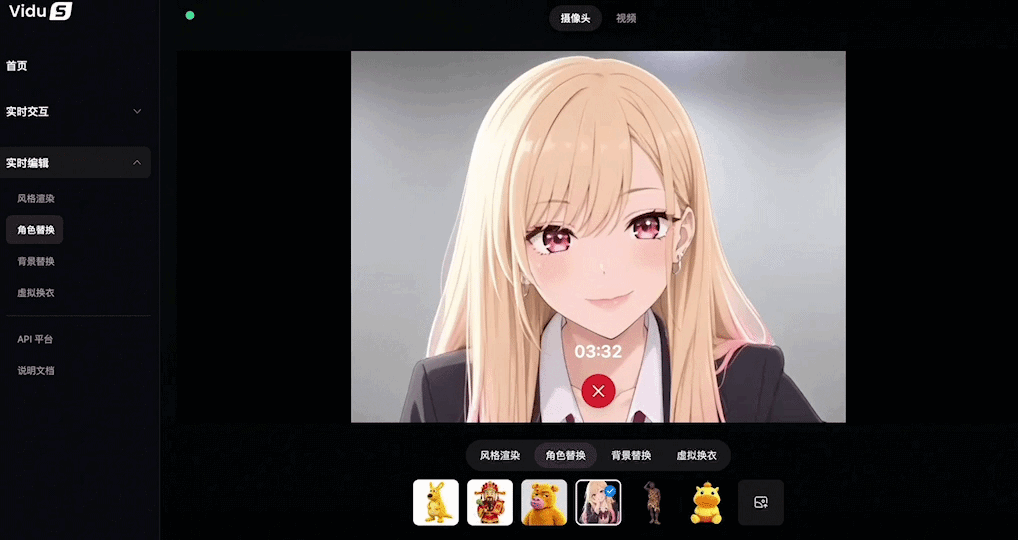
编辑|牛来 AI 视频,正在变成一个可以边播、边演、边改的实时系统。 比如,打开摄像头,点一下参考角色图,就能一键更换画面里的人物,动作、节奏丝毫不受影响。 和虚拟人的互动也能随时加戏,实时聊着天,一句「跳个舞」便能开启才艺模式,动作还挺丝滑。 就像 P 图一样,摄像头捕捉到的真人视频流,也能边拍边「P 视频」,在保留原有动作和节奏的情况下,实时改变画风、人物或背景。 这就是生数科技最新推出的 Vidu S2 ,一套专 为实时交互与实时编辑设计的视频生成模型 ,覆盖实时数字人、离线数字人和实时视频编辑三类核心能力。 其中,S2-Avatar 负责实时数字人的「实时表演」互动,支持 720p 、25~42 FPS 输出,能够处理舞蹈等更大幅度动作,并允许用户在生成途中继续加入人物、服装、道具或场景参考图。 S2-Editing 则是本次最显眼的新能力。它持续接收摄像头或源视频流,让新规则即时作用于后续画面,在保留原有姿态、肢体运动、镜头轨迹和时间顺序的同时,实时改变风格、服装、人物主体或背景。 此外,S2-Avatar [Offline] 面向预设内容生产,可根据图片、文案或音频批量生成动作时间点可控的数字人口播视频。 这些能力并非只停留在演示视频里。产品发布前夕,生数团队还公开了技术论文,详细披露实时数字人、流式视频编辑和空间视频背后的技术路线,并在发布当天开放网页体验与 API。 产品仍在持续打磨,团队希望从 Day 1 就把它作为一个开放实验交给用户进行共创。 体验链接: https://vidu.cn/vidu-stream API 平台: http://platform.vidu.cn/vidu-stream/doc 技术报告: https://arxiv.org/pdf/2609.11638 从 S1 论文于 7 月 3 日提交,到 S2 论文于 9 月 10 日正式公开, 前后仅相隔约 69 天 ,生数团队的技术迭代节奏相当紧凑。Vidu S1、Vidu S2 的全链路研发均由朱军教授的博士生、生数科技流式视频生成与推理负责人张金涛负责。 如此短的周期里,升级并非只多了几个功能:控制对象从固定数字人扩展到动态参考图和完整视频流,输出从 540p 提升到 720p,动作从说话为主扩展到舞蹈等全身表演,并进一步把实时链路延伸到左右眼同步的空间视频。 如果说
Related stories
ByteDance launches Doubao Work agent, merging Trae and Coze into Doubao
ByteDance has officially launched Doubao Work, a new agent product for productivity scenarios, deeply integrated with Feishu to leverage enterprise context. The company is also consolidating its coding platform Trae and agent-building tool Coze into Doubao, with plans to compete with Tencent's WorkBuddy. Doubao Work offers a 30-day free trial and can autonomously decompose tasks, call tools, and operate browsers and cloud computers.
3 reports · 3 sources

VoiceMem: Streaming Dual-Brain Memory System for Real-Time Voice AI
Researchers from four top universities and Open Interaction Lab released VoiceMem, a streaming dual-brain memory system for real-time voice interaction. It addresses the lack of memory in current voice assistants by integrating short-term and long-term memory, and has been adopted by Qwen Audio Agent as an optional memory module.
1 reports · 1 sources
Alibaba launches Wan3.0 video model with 30-second generation and document input
Alibaba officially launched its video generation model Wan3.0 on August 24, 2026, featuring upgrades in generation length, document input, and realism. The model can generate 30-second videos in a single run and, for the first time, supports input from document formats such as doc, xls, ppt, pdf, and md. Early enterprise users report consistent feedback describing the model as stable, realistic, and textured, with applications in short dramas, film, advertising, and cultural tourism.
2 reports · 2 sources
Google DeepMind launches Gemini Omni 1.1 Flash video model with scene extension, 4K upscaling
Google DeepMind announced Gemini Omni 1.1 Flash, a video production model with scene extension, first/last frame interpolation, and 4K upscaling. It reads up to 10 seconds of prior video context, extends scenes in 10-second increments up to 40 seconds total, and offers a 360p draft mode with up to 60% higher throughput and about one-third the cost of 720p.

News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe