VoiceMem: Streaming Dual-Brain Memory System for Real-Time Voice AI
Researchers from four top universities and Open Interaction Lab released VoiceMem, a streaming dual-brain memory system for real-time voice interaction. It addresses the lack of memory in current voice assistants by integrating short-term and long-term memory, and has been adopted by Qwen Audio Agent as an optional memory module.
Coverage timeline
机器之心机器之心
科幻早就预演过这一天,而这两年 AI 的真实进展,正把它推成一个可讨论的命题:AI 或许不会停在「工具」上,而会成为与人类共生的存在 ——AGI Being。 共生的第一道门槛,是能跟人实时说话。这是 GPT-4o、全双工模型、Interaction Model 在做的事。 但用久一点,共同的短板就浮出来:它们没有记忆。听得懂你此刻在说什么,却不知道你是谁。认识始终是单向的 —— 你越来越熟悉它,它对你永远停在第一天。 没有记忆的交互系统是没有灵魂的,再流畅的陪伴者也逃不掉工具的身份。每次打开都要重新问你是谁;说过不吃坚果,明天照样推荐给你。 代价有两个: 1. 信任被清零。 消耗掉的不是效率,是刚建立起来的那点连接。 2. 只会「答对」,学不会「懂你」 。 现有记忆只记信息:你说过什么、涉及到谁;但交互的另一半是情感 —— 你说「我没事」时的语气,提到某个人时不自觉地停顿 xq。 这正是 VoiceMem 在做的事:面向多模态陪伴者的类脑记忆系统,补全 Digital Embodiment 的第三根支柱。 这项工作也延续了论文第一作者谢之非的研究主线:他是目前大音频语言模型、实时语音交互与多模态 AI 领域内非常活跃的研究者之一。 VoiceMem 不是炒概念讲故事,而是四家顶级高校与 Open Interaction Lab 联合发布的记忆框架,工程优化充分,一行代码就能跑。目标是实时交互版的「Mem0」。 目前,Qwen Audio Agent 也已将 VoiceMem 接入为可选的记忆系统,让语音助手的记忆不止于文本,还可以从真实世界中记住语音、说话人、声音事件、音乐等丰富信息。 论文标题:VOICEMEM: STREAMING DUAL-BRAIN MEMORYFOR REAL-TIME INTERACTION Project page: https://xzf-thu.github.io/VoiceMem Code: https://github.com/xzf-thu/VoiceMem Report: https://arxiv.org/pdf/2608.26005 为什么是 VoiceMem Mem0、Zep、MemOS 直接用不行吗? 不行,两个原因。 一、应用上,时间和信息输出都不可用。 语音留给「想一想」的时间太短。从你说完到 AI 开口,总预
Related stories
Microsoft launches MAI-Transcribe-2-Streaming and two new voice models
Microsoft AI announced the launch of MAI-Transcribe-2-Streaming, a low-latency real-time transcription model, alongside two new voice models, MAI-Voice-2.1 and MAI-Voice-2.1-Flash. The models are positioned for accurate, fast, and low-cost audio understanding and generation, targeting conversational voice agents.
1 reports · 1 sources
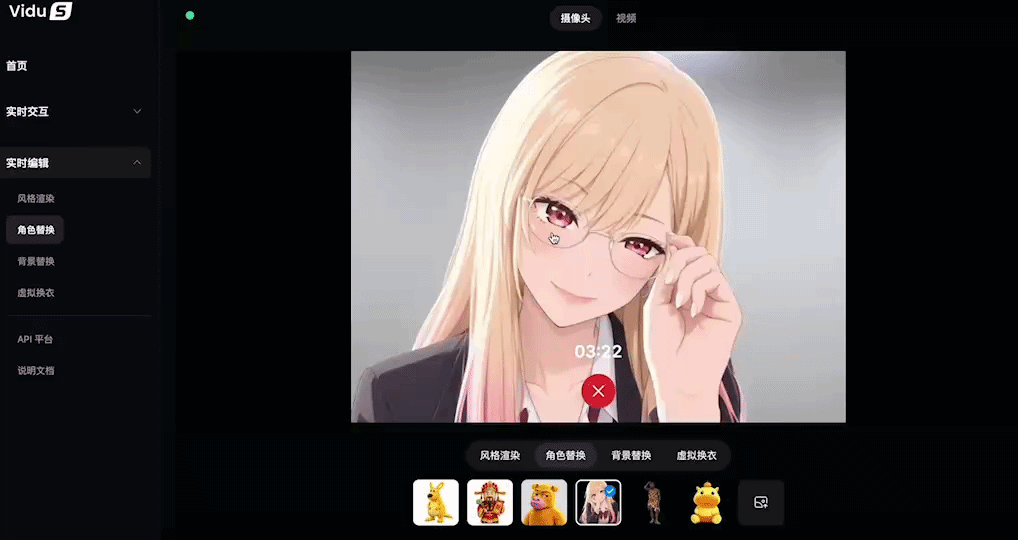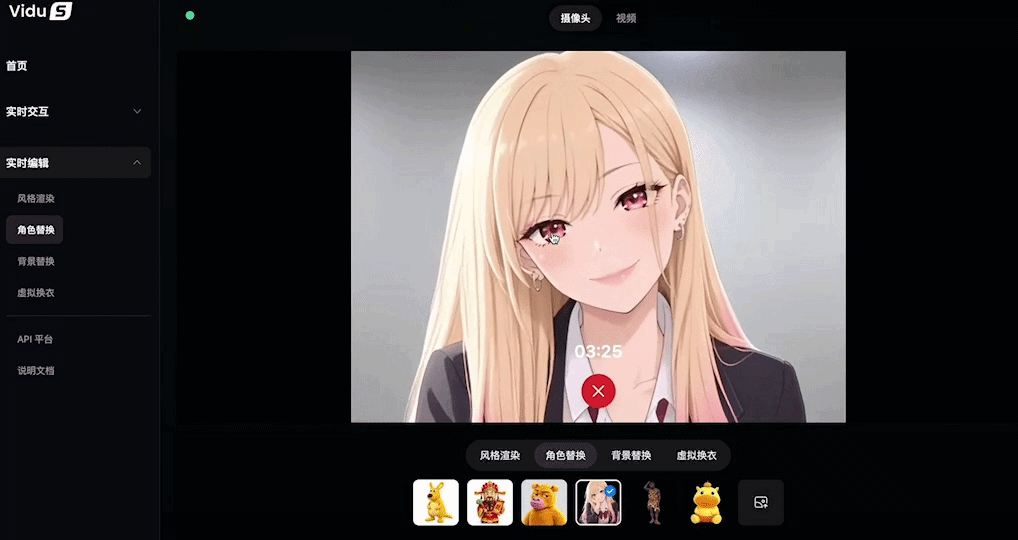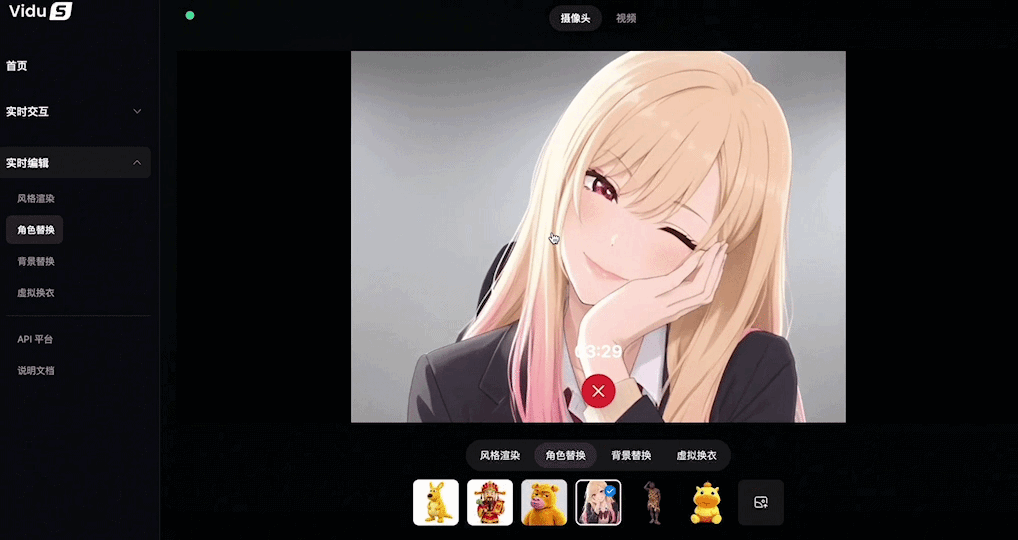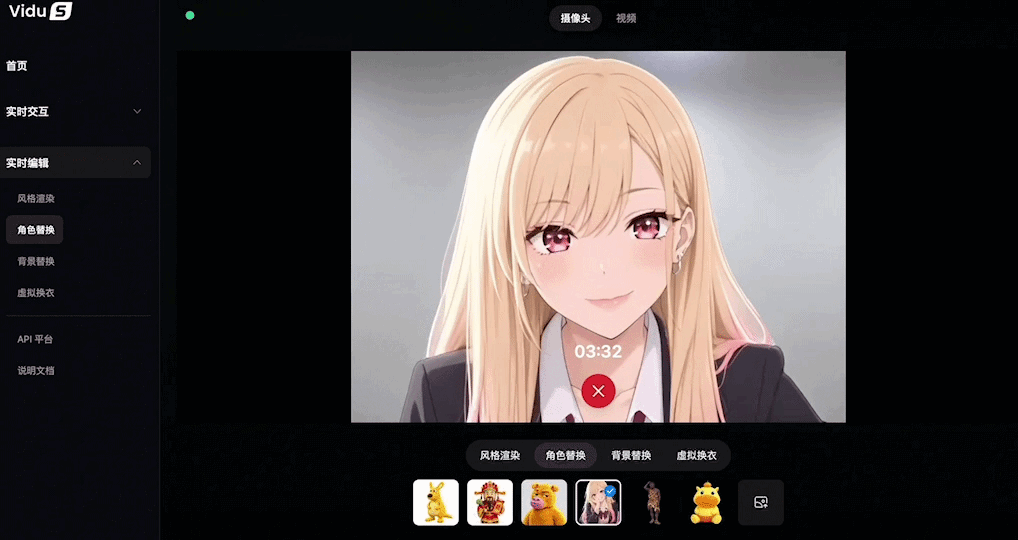
Shengshu releases Vidu S2 for real-time interactive and editing video generation
Chinese AI startup Shengshu Technology released Vidu S2, a video generation model designed for real-time interactive and editing applications, covering real-time digital humans, offline digital humans, and real-time video editing. The model supports 720p at 25-42 FPS output, and the team published a technical paper and opened web experience and API access on the release day.
1 reports · 1 sources
ByteDance Releases SeedRealtime: Full-Duplex Audio-Video Model for Natural Interaction
ByteDance's Seed team unveiled SeedRealtime, a native full-duplex audio-video large model that jointly understands sound, images, and temporal information. It enables real-time, natural interaction where the model can see, listen, and speak simultaneously, marking a step toward fully multimodal conversational AI.
1 reports · 1 sources
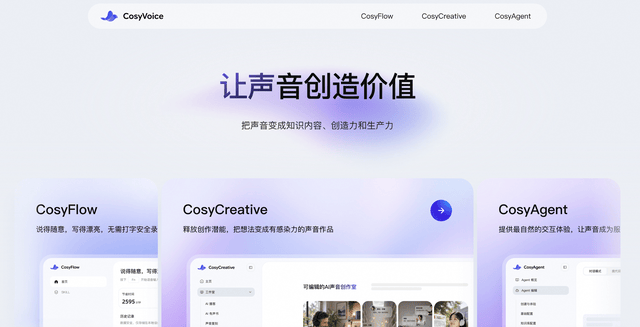
Alibaba launches CosyVoice Studio, first all-in-one AI voice platform in China
On August 7, Alibaba launched CosyVoice Studio, China's first all-in-one AI voice production platform, built on its self-developed Qwen-Audio model, which ranked first globally in ASR, real-time interaction, and TTS on Artificial Analysis. The platform offers a voice keyboard that cleans speech into structured text, audio content creation for podcasts and audiobooks, and voice agents for real-time enterprise conversations. It marks the first time Alibaba's voice capabilities are offered as an aggregated product, with enterprise API access and direct consumer use.
1 reports · 1 sources
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe