ByteDance Releases SeedRealtime: Full-Duplex Audio-Video Model for Natural Interaction
ByteDance's Seed team unveiled SeedRealtime, a native full-duplex audio-video large model that jointly understands sound, images, and temporal information. It enables real-time, natural interaction where the model can see, listen, and speak simultaneously, marking a step toward fully multimodal conversational AI.
Coverage timeline
ByteDance Seed Blog
作为原生音视频全双工大模型,联合理解声音、画面与时序信息,带来边看、边听、边说的自然交互体验
Related stories
VoiceMem: Streaming Dual-Brain Memory System for Real-Time Voice AI
Researchers from four top universities and Open Interaction Lab released VoiceMem, a streaming dual-brain memory system for real-time voice interaction. It addresses the lack of memory in current voice assistants by integrating short-term and long-term memory, and has been adopted by Qwen Audio Agent as an optional memory module.
1 reports · 1 sources
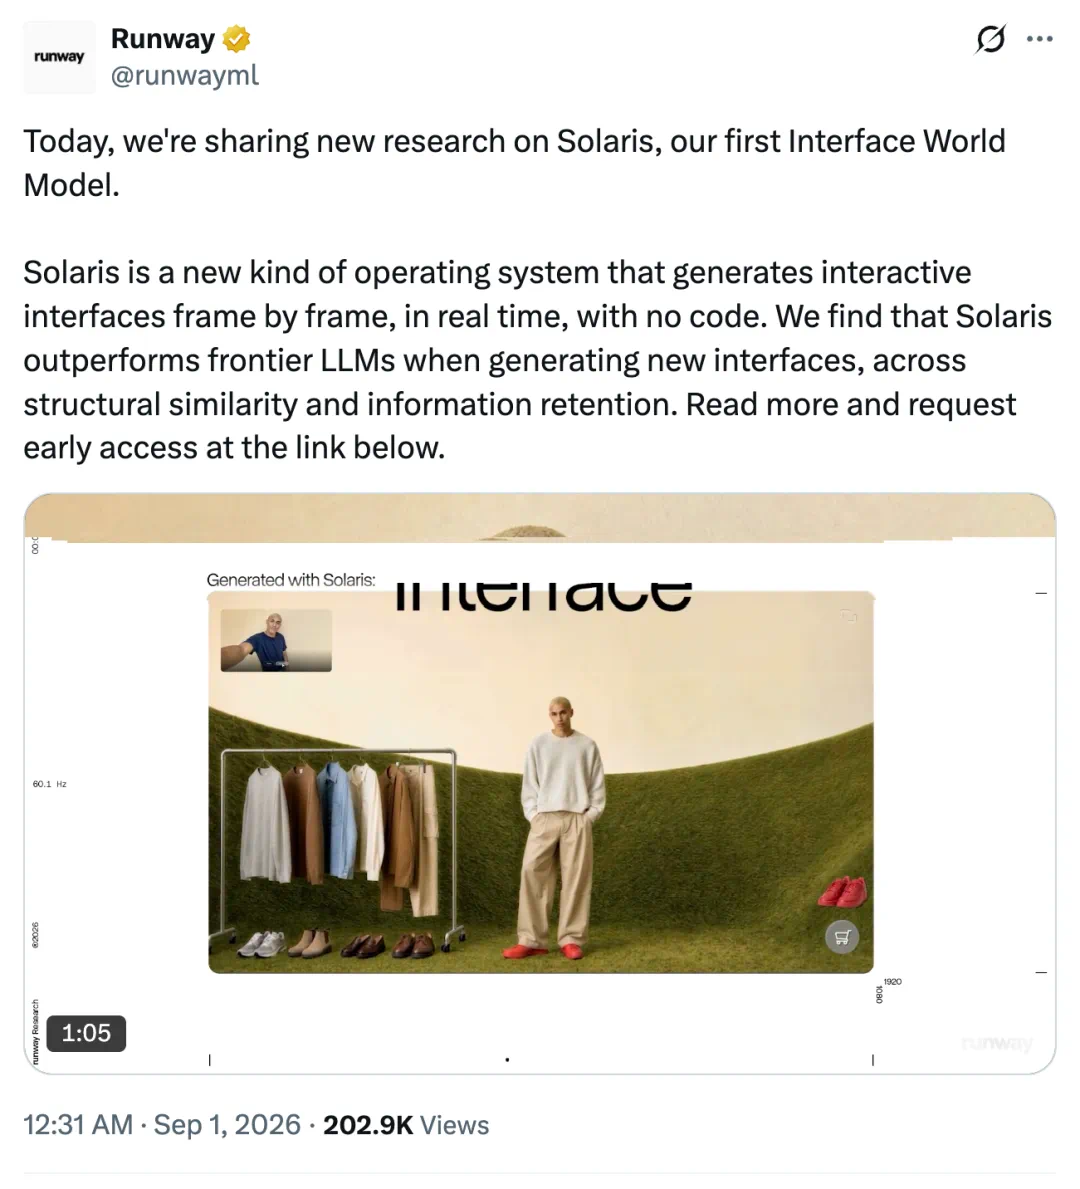
Runway unveils Solaris, an 'Interface World Model' generating app interfaces frame-by-frame
Runway announced Solaris, described as the first 'Interface World Model,' a research project that generates interactive app interfaces frame-by-frame like video, eliminating the need for code. The model responds to clicks, drags, or text input by continuing to generate the next frame based on the current state, potentially turning visual designs directly into runnable software.
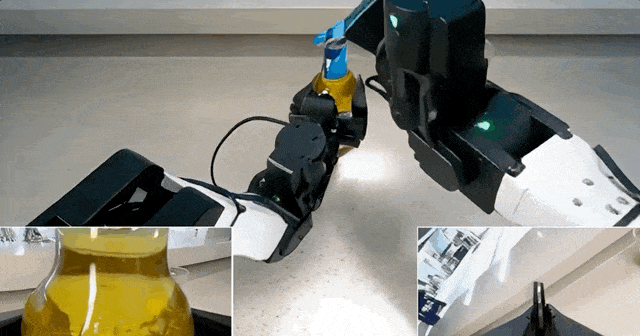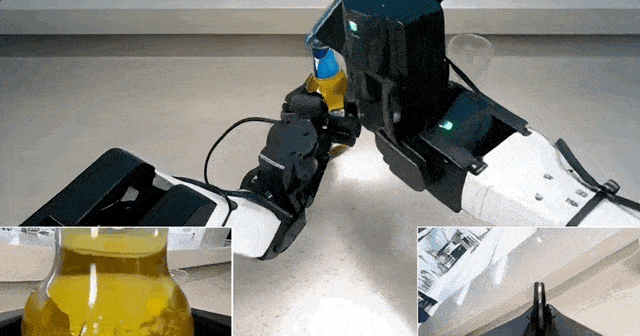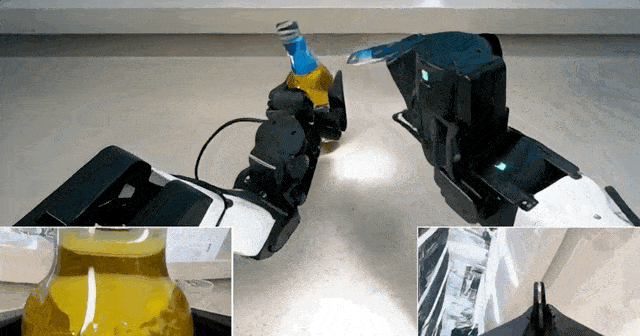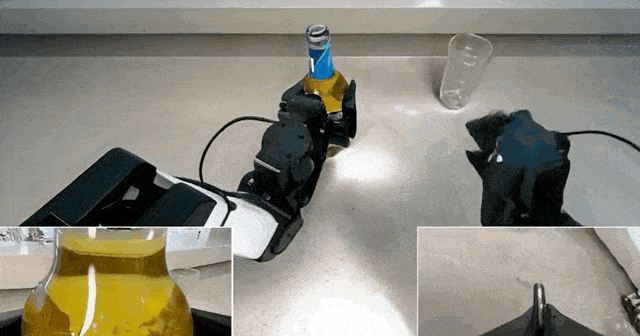
Current Robotics Unveils CurrentWorld-0, an Interactive World Simulator
Current Robotics released CurrentWorld-0, an interactive world simulator that models cross-embodiment, multi-view, and multimodal physical interactions for robot learning and evaluation. It is the team's second work after the humanoid whole-body manipulation model Curr-0, and is described as a data-driven alternative to traditional physics engines, capable of simulating flexible objects and fluids.
2 reports · 2 sources
ByteDance Seed: Caption Information Density, Not Length, Drives Text-to-Image Scaling
ByteDance Seed researchers published a paper showing that in text-to-image models, the information density of captions, not their token length, predicts diffusion training loss. They propose Structured Prompt to increase image-bound information from both Diffusability and Promptability sides, significantly improving complex composition, reasoning, and world knowledge generation tasks.
News updates every hour. Subscribe in your RSS reader to get new stories automatically.
Subscribe